The decoder swap passed its word-error gate
Both routes used the same community 6-bit MLX T3 generator. The hybrid replaced only the audio stage with the unchanged published ONNX conditional decoder. No CoreML execution occurred in this hybrid.
Key finding
No hybrid output added word errors in 40 exact-token comparisons, but the ONNX decoder made the route slower.
Edited finding from the pinned experiment record. The report and figure metadata preserve the original workload and limits.
The boundary
Eight generic English phrases with two seeds and a smaller selected-voice subset. ASR agreement is not human naturalness or Spanish acceptance.
Data
Reviewed aggregate results with explicit units, sources and qualification limits. Different cohorts remain separate.
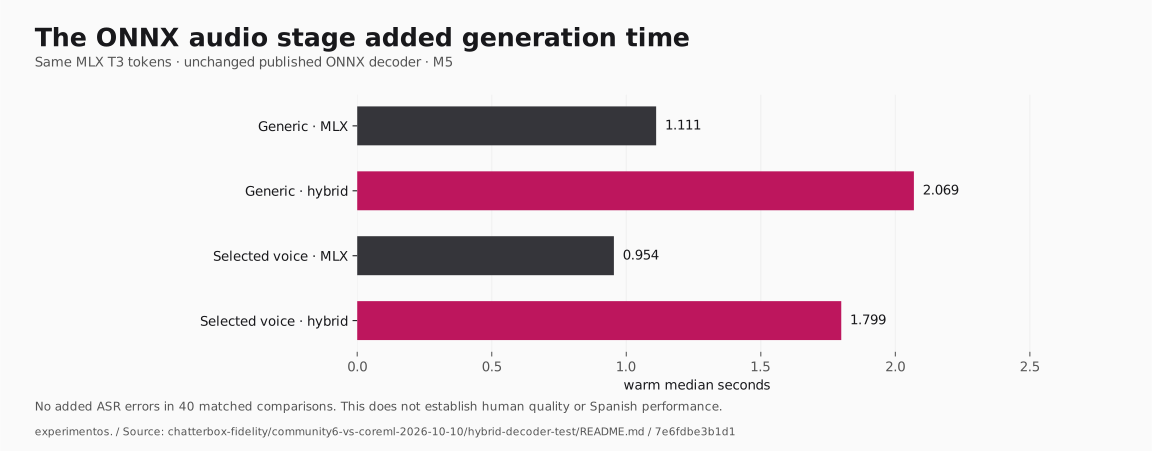
The ONNX audio stage added generation time
Same MLX T3 tokens · unchanged published ONNX decoder · M5
- Generic · MLX1.111
- Generic · hybrid2.069
- Selected voice · MLX0.954
- Selected voice · hybrid1.799
warm median seconds
No added ASR errors in 40 matched comparisons. This does not establish human quality or Spanish performance.
View data & source
| Configuration | Value |
|---|---|
| Generic · MLX | 1.111 |
| Generic · hybrid | 2.069 |
| Selected voice · MLX | 0.954 |
| Selected voice · hybrid | 1.799 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
Write-ups
Report chatterbox-fidelity/community6-vs-coreml-2026-10-10/hybrid-decoder-test/README.md
Measure the proposed component swap
Both routes used the same community 6-bit MLX T3 generator. The hybrid replaced only the audio stage with the unchanged published ONNX conditional decoder. No CoreML execution occurred in this hybrid.
Every comparison checked the generated speech-token hash. Each MLX baseline was paired with two hybrid outputs using fresh internal noise. Thirty-eight of forty pairs tied on word errors; two hybrid outputs had two fewer edits each.
The cost of the swap
For the generic corpus, median warm time changed from 1.111 to 2.069 seconds and median RTF from 0.230 to 0.411. Selected-voice medians changed from 0.954 to 1.799 seconds. Instrumentation placed the extra time in audio decoding, rather than T3 generation.
The generic corpus had 8/250 baseline edits. Repeating each baseline score across its two matched hybrid comparisons gives 16/500 versus 12/500. Those equal denominators avoid implying that twice as many hybrid clips provide twice as much independent coverage.
The result I can use
The optional route passed its local intelligibility gate, while MLX remained faster. Reference voice audio and conditioning are excluded from this publication. Human preference, multilingual speech and longer-form behavior remain open.
Evidence and publication boundary
This is an edited account of the recorded experiment. The linked archive is private; the methods, aggregate findings and limits are included above. Reference recordings, raw conversations, authentication material and workstation configuration are excluded.
More in Speech & codecs
MOSS on a 3090: Q2 failed, AWQ4 stayed closer
Every profile began with the pinned BF16 generator. The comparison reused fixed reference codes and an FP32 decoder for the main quality measurements, keeping codec changes separate from generator quantization.
AWQ4 stayed close to the BF16 reference on WavLM and character errors; the sensitivity Q2 candidate was rejected.
Drama3: BF16 decoded the same codes about three times faster
The experiment replayed saved Spanish and English codes representing 21.5481 and 15.8824 seconds of audio. It compared FP32, BF16, mixed BF16 and two INT8 decoder variants on one RTX 3090.
BF16 reduced median decoder time from 390.07 to 129.54 ms in Spanish and from 292.42 to 96.88 ms in English.
Keeping FP32 and moving Supertonic to Triton
Rather than reduce the CPU graph precision again, this follow-up used NVIDIA Triton’s ONNX backend with CUDA execution and the unchanged FP32 graphs. The paired comparison retained both speed and acoustic checks.
The paired GPU test cut median first-audio time to about 0.35 seconds while preserving the measured ASR results.