Benchmark explorer
Benchmarks
56 reviewed figures across 6 areas, with CSV, JSON, SVG and PNG exports. Different experiments use different prompts, settings and hardware, so compare across experiments with care.
Headline results (69)
Edited findings from the reviewed experiment records. Qualification limits remain attached to each report.
| Experiment | Area | Hardware | Key measured result |
|---|---|---|---|
| A benchmark harness that keeps dry runs out of the results | Devices & tools | The archive now includes standard-library harnesses for throughput, quant comparison, task evaluation and VRAM measurement. | |
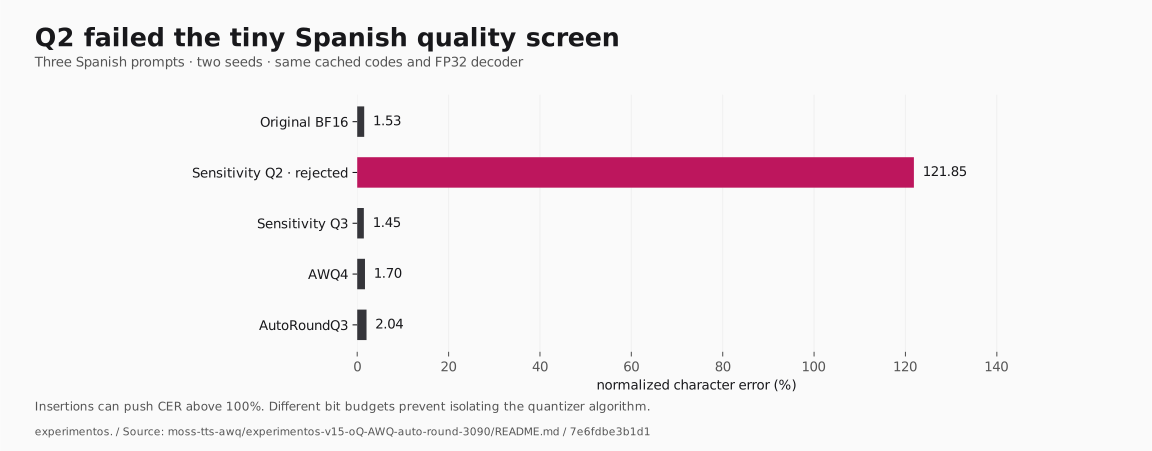
| MOSS on a 3090: Q2 failed, AWQ4 stayed closer | Speech & codecs | AWQ4 stayed close to the BF16 reference on WavLM and character errors; the sensitivity Q2 candidate was rejected. | |
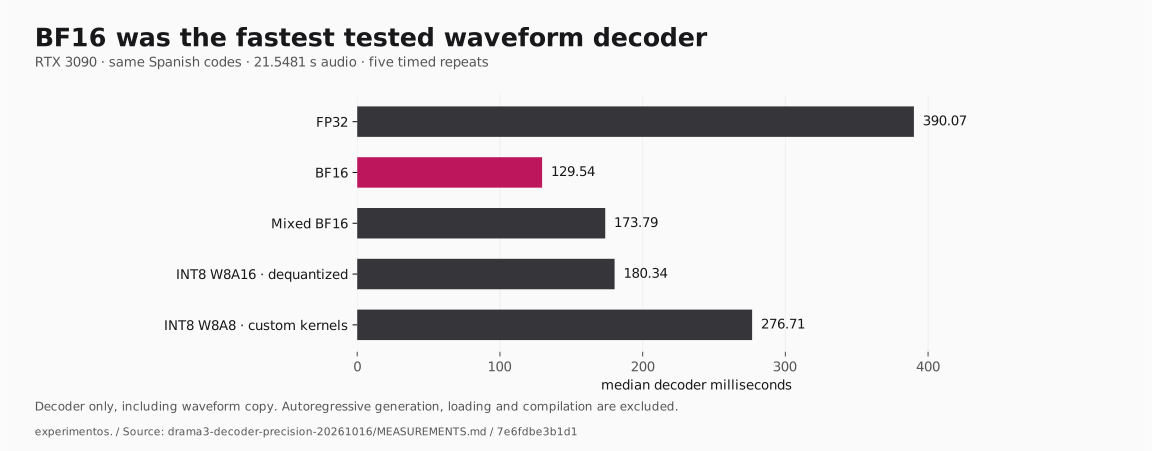
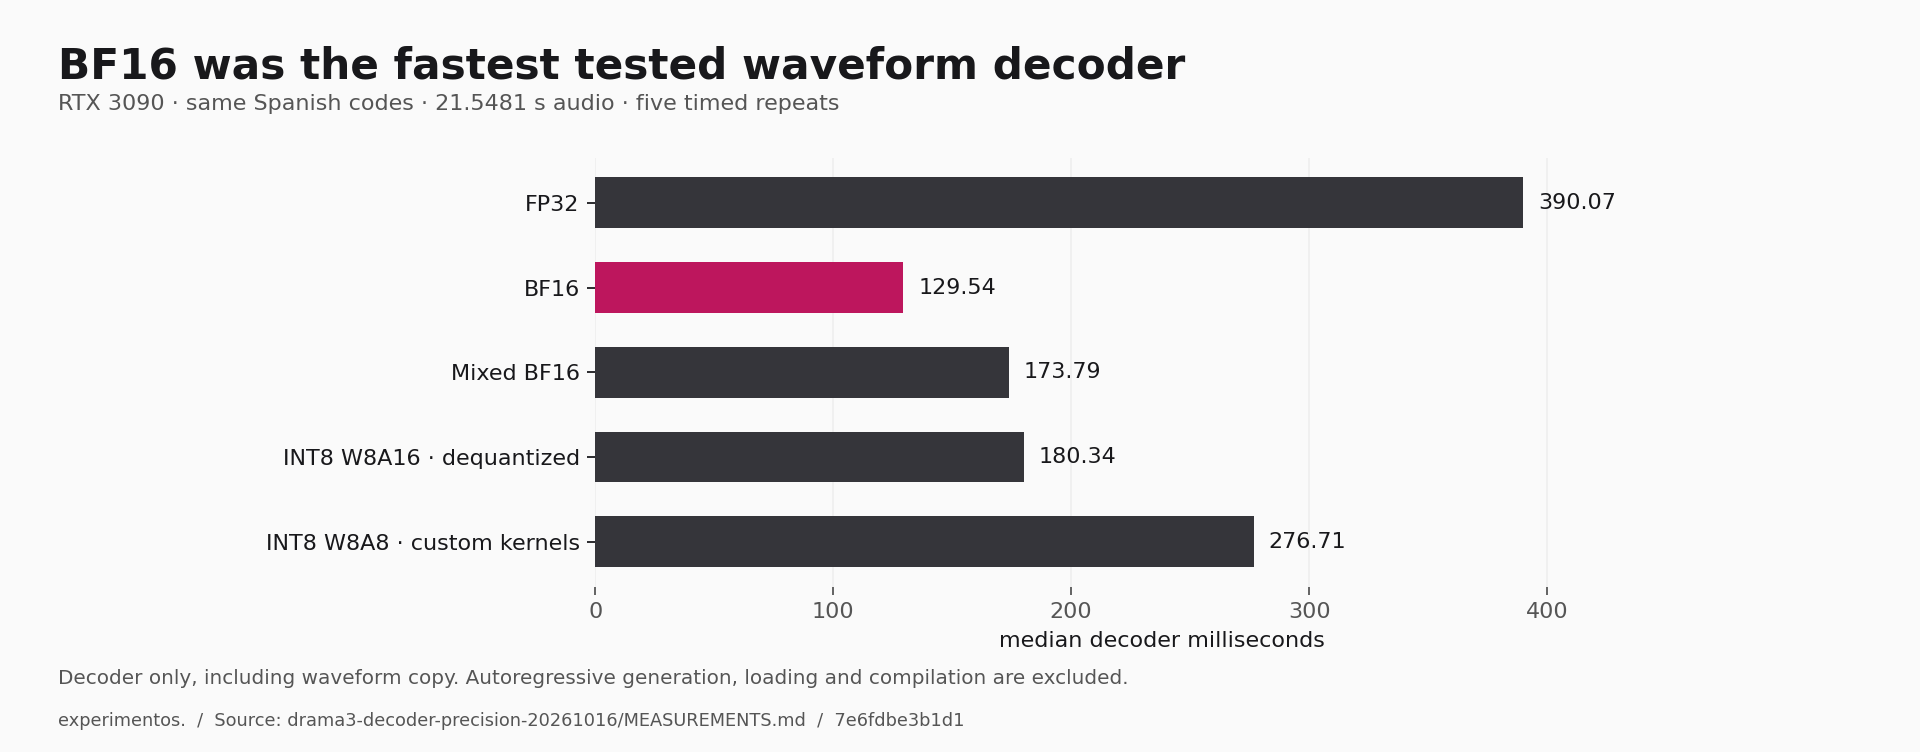
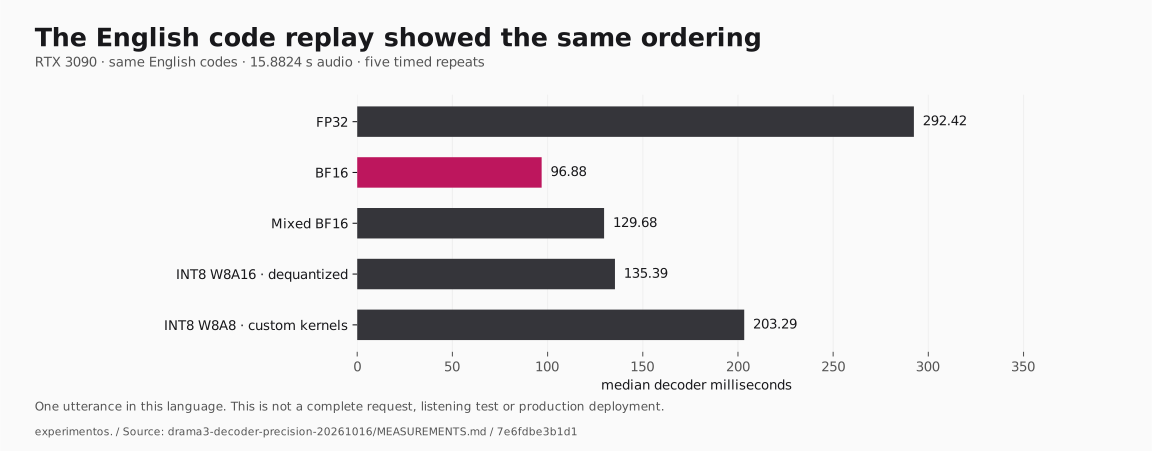
| Drama3: BF16 decoded the same codes about three times faster | Speech & codecs | RTX 3090 | BF16 reduced median decoder time from 390.07 to 129.54 ms in Spanish and from 292.42 to 96.88 ms in English. |
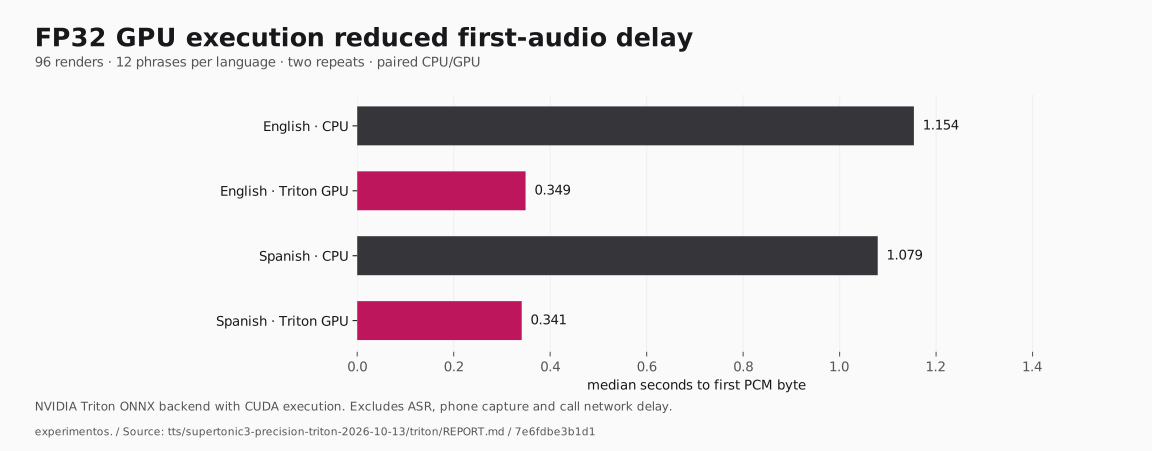
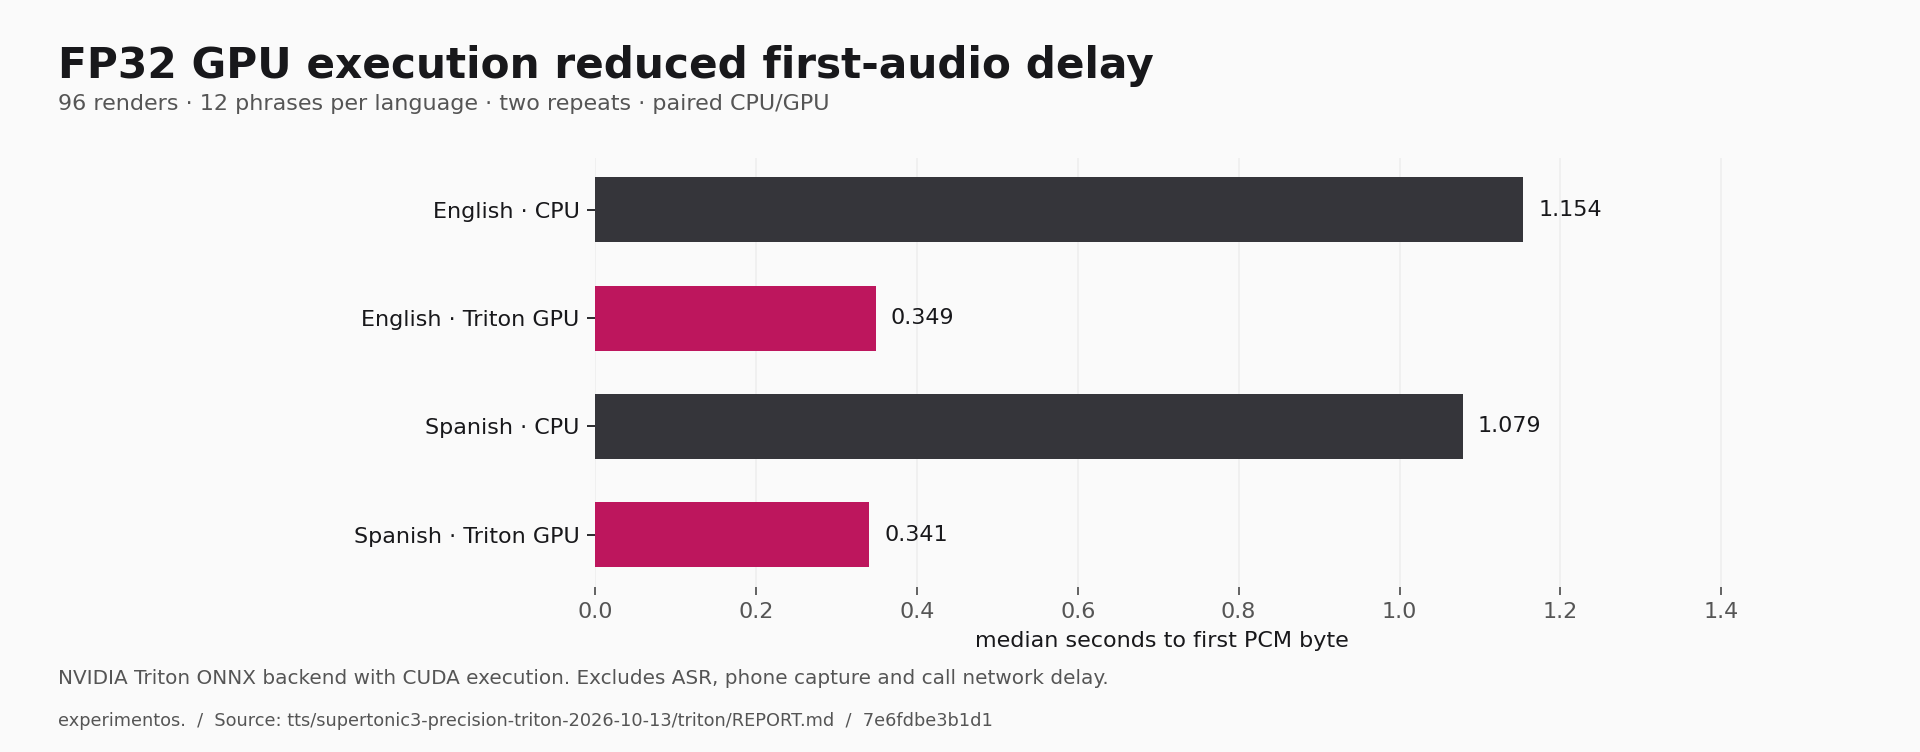
| Keeping FP32 and moving Supertonic to Triton | Speech & codecs | The paired GPU test cut median first-audio time to about 0.35 seconds while preserving the measured ASR results. | |
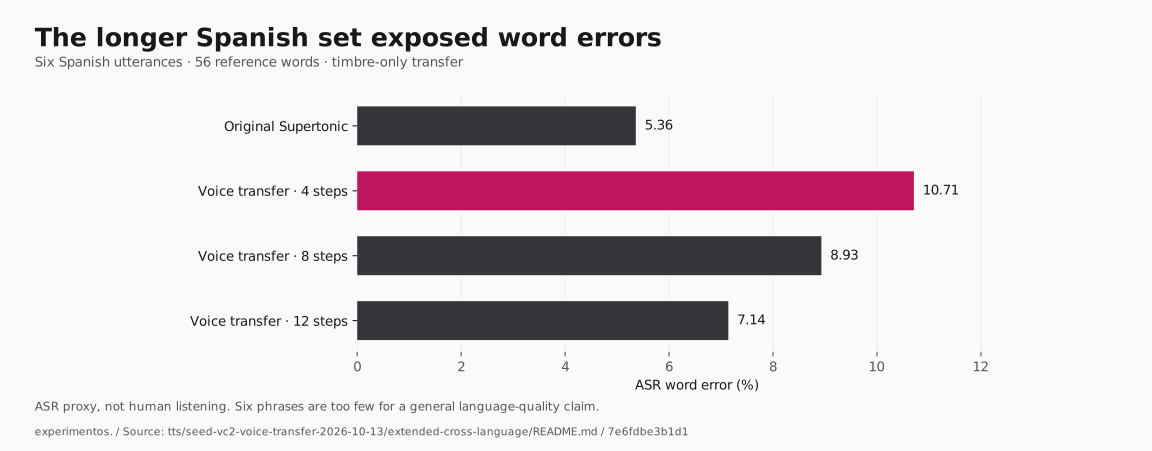
| Longer Spanish phrases exposed the voice-transfer cost | Speech & codecs | Speaker resemblance improved on longer phrases, but Spanish word error increased and conversion added over a second. | |
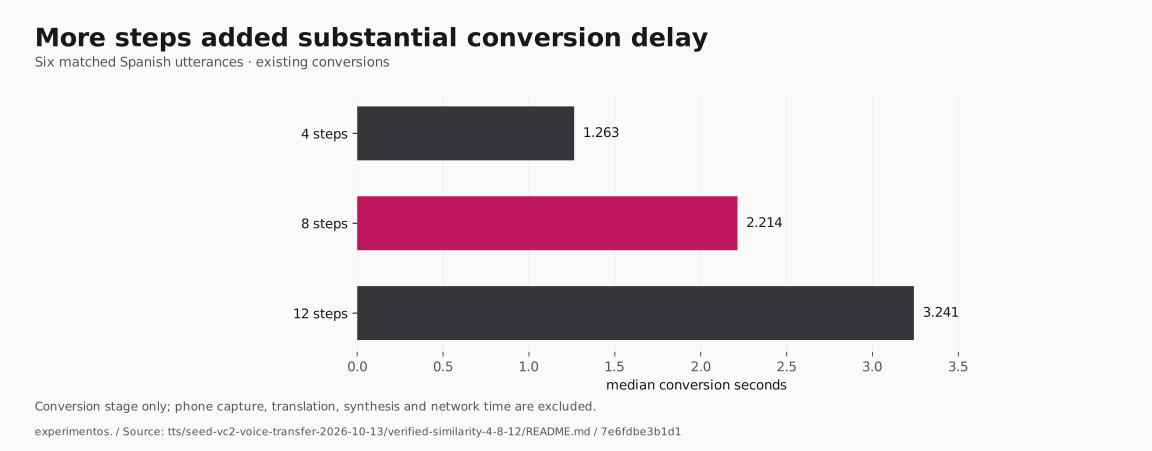
| More diffusion steps did not reliably improve the voice match | Speech & codecs | Matched six-sentence similarity intervals crossed zero for both eight-minus-four and twelve-minus-four steps. | |
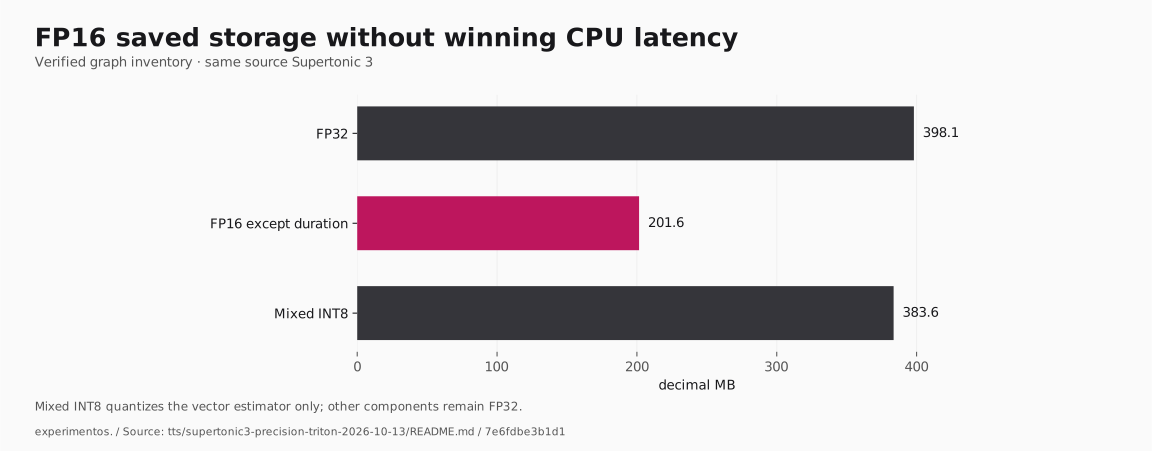
| Supertonic: half the storage did not mean faster CPU speech | Speech & codecs | FP16 roughly halved the model storage but increased measured median time to first audio on this CPU workload. | |
| Voice resemblance improved before call readiness did | Speech & codecs | Timbre-only transfer improved speaker-embedding similarity on short greetings, while style transfer could destroy the words. | |
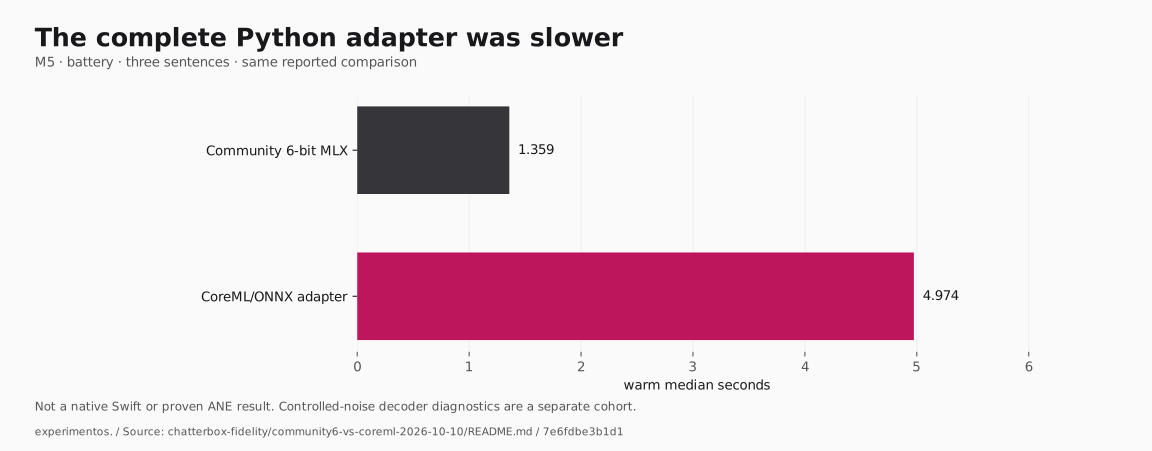
| A faithful decoder can still be the slower pipeline | Speech & codecs | Apple M5 | The community MLX pipeline was faster in this Python comparison; a controlled decoder diagnostic favored the other acoustic route. |
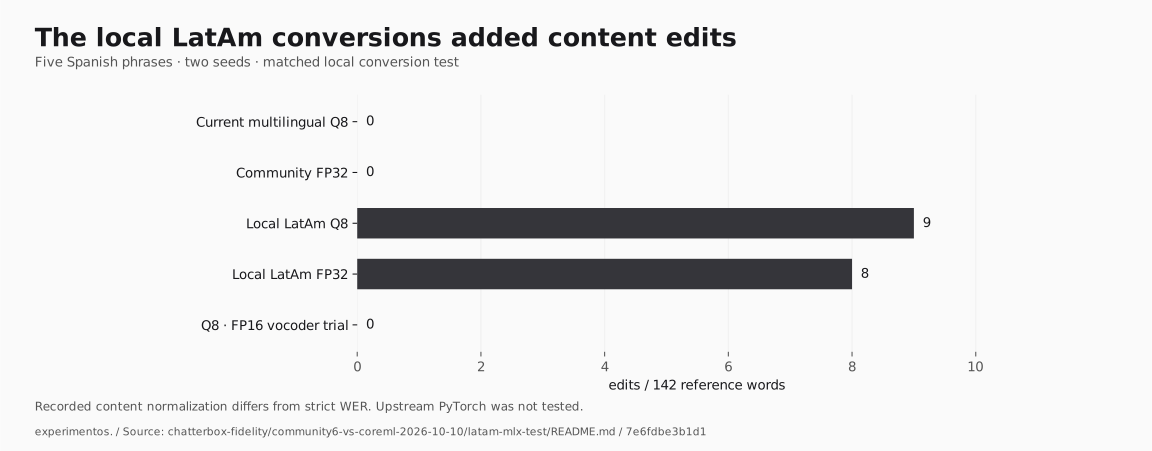
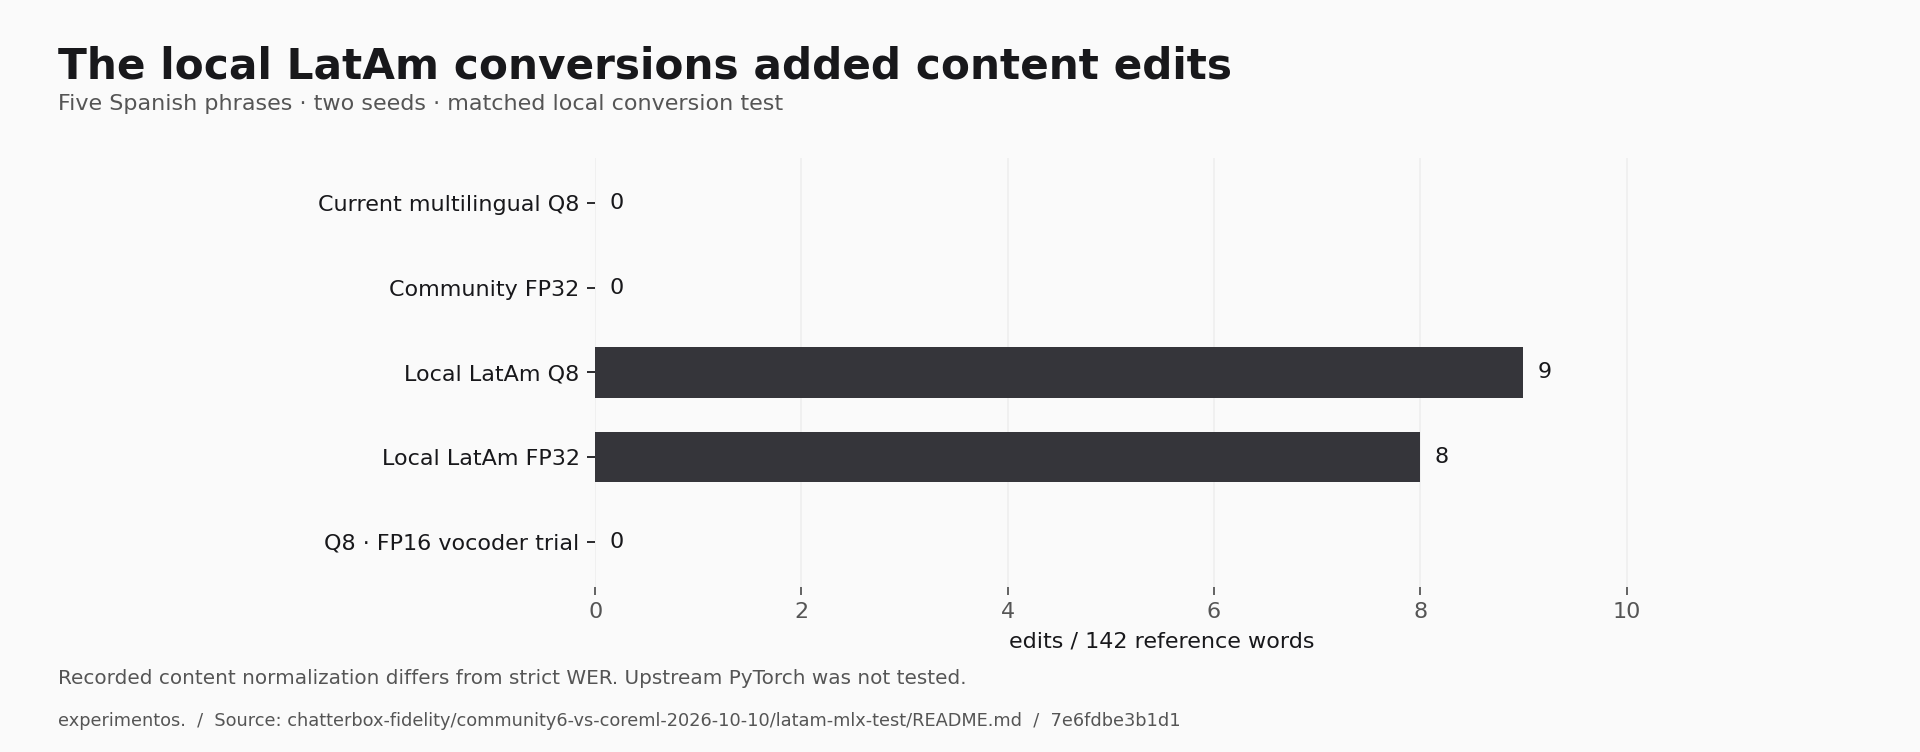
| A local LatAm conversion failed the content gate | Speech & codecs | The deployed multilingual Q8 remained the choice: the local LatAm Q8 conversion added nine content edits over 142 words. | |
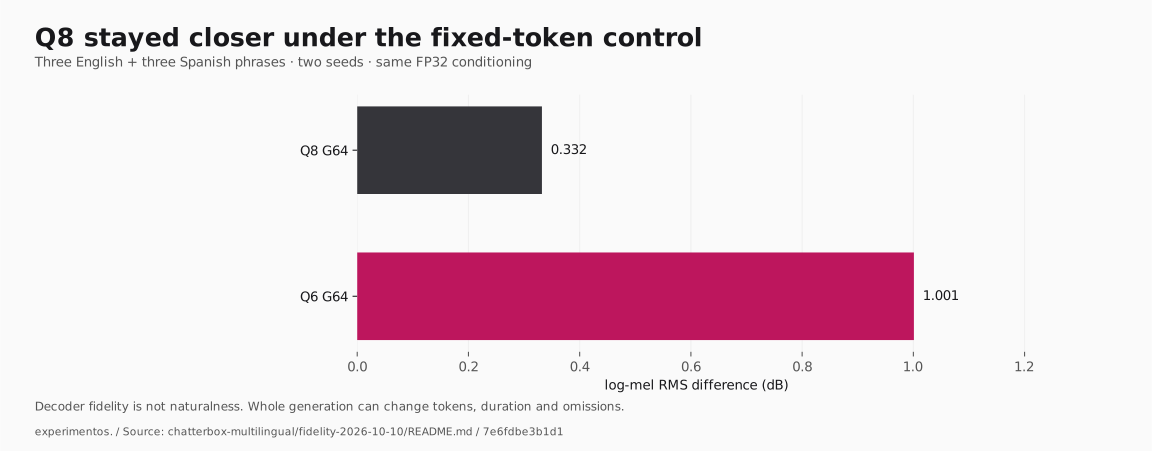
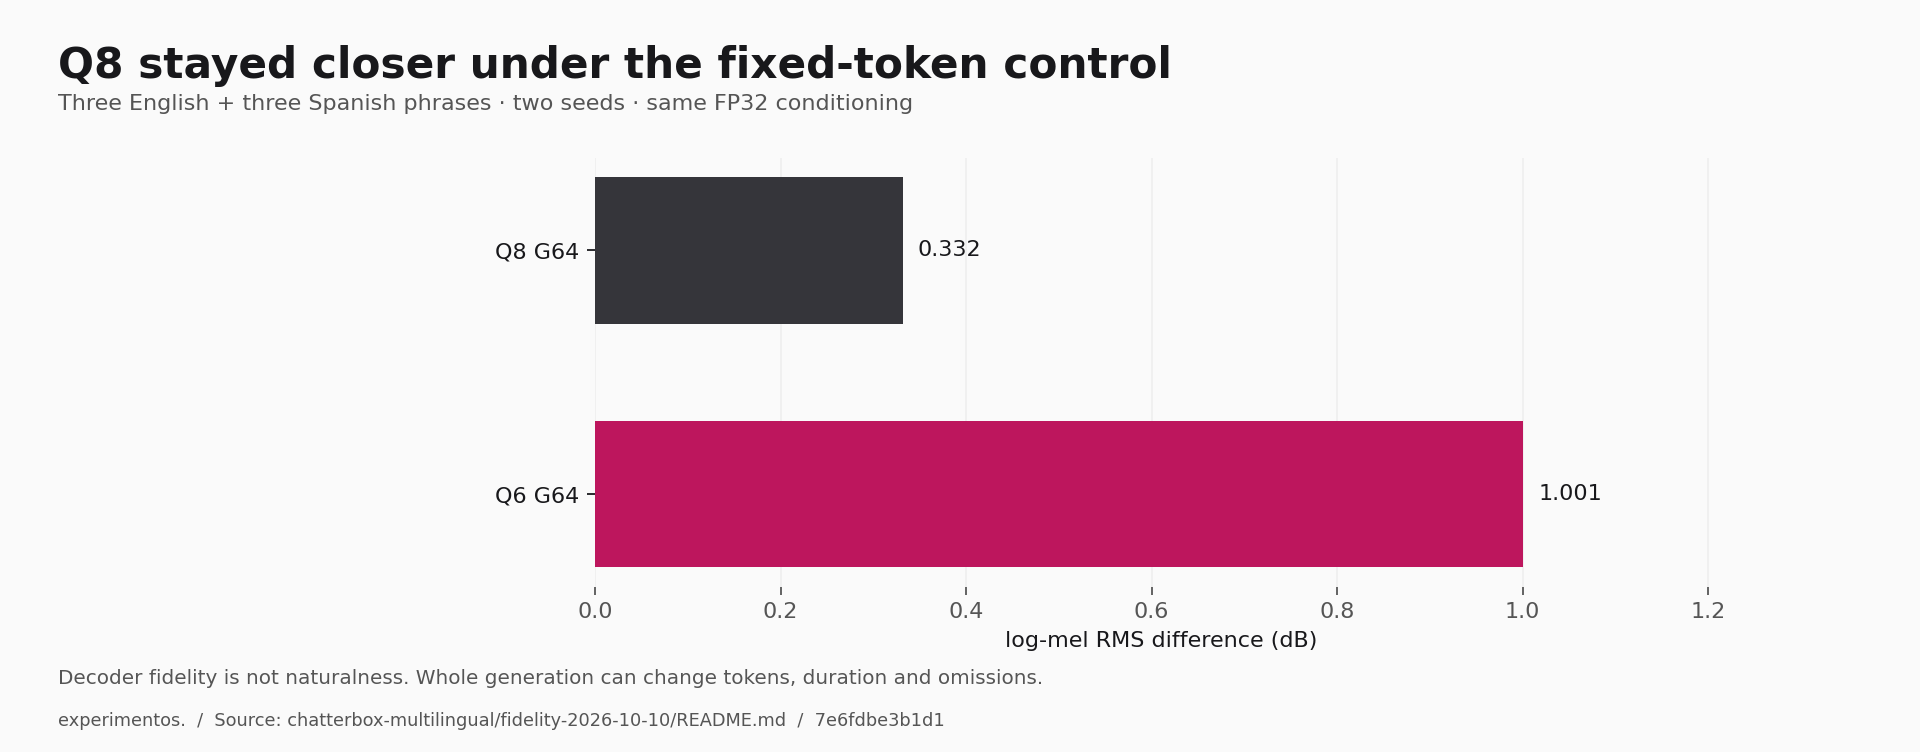
| Holding speech tokens fixed made the Q8 advantage clearer | Speech & codecs | Q8 had lower controlled decoder error than Q6 on the paired English and Spanish clips. | |
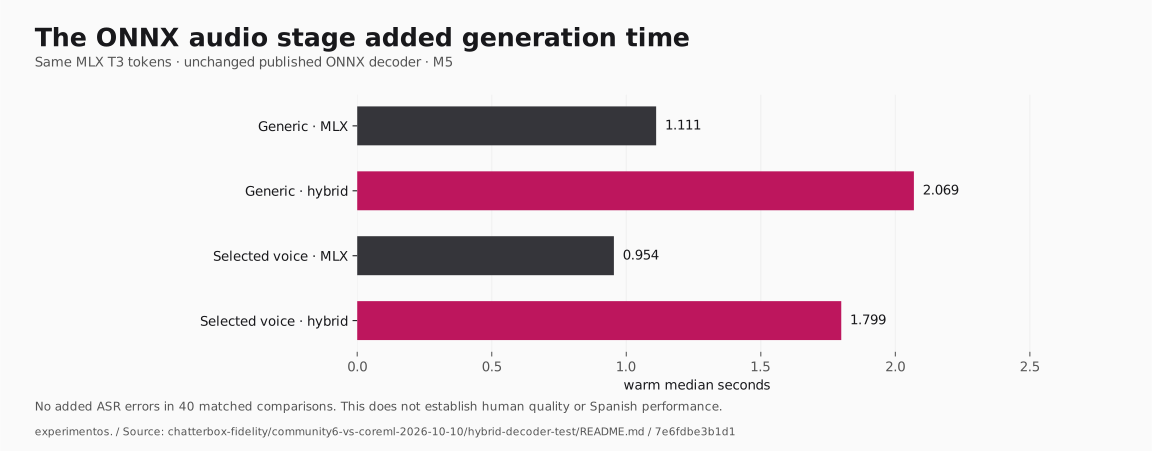
| The decoder swap passed its word-error gate | Speech & codecs | Apple M5 | No hybrid output added word errors in 40 exact-token comparisons, but the ONNX decoder made the route slower. |
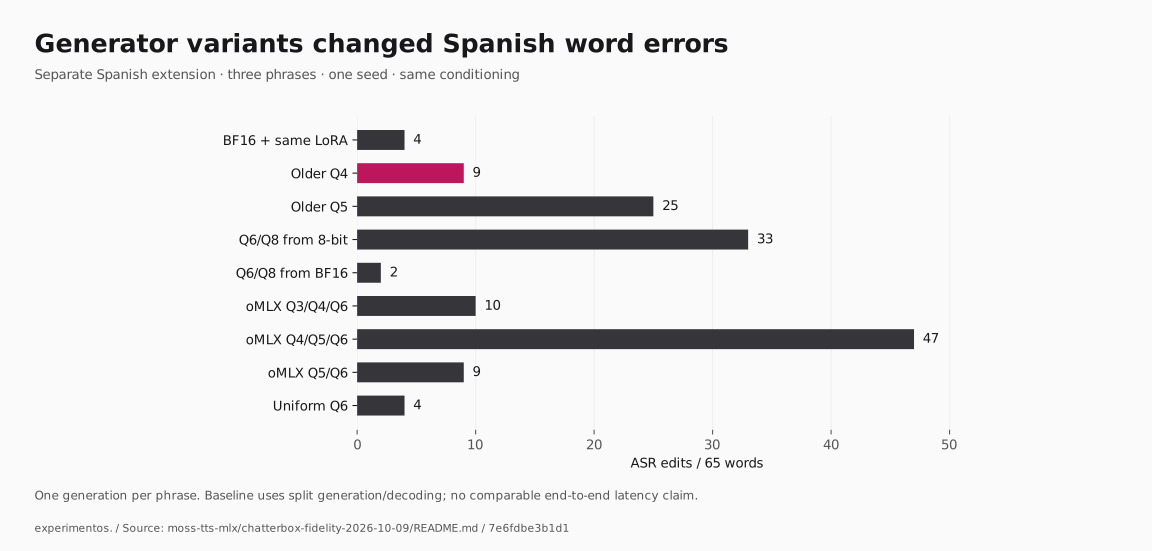
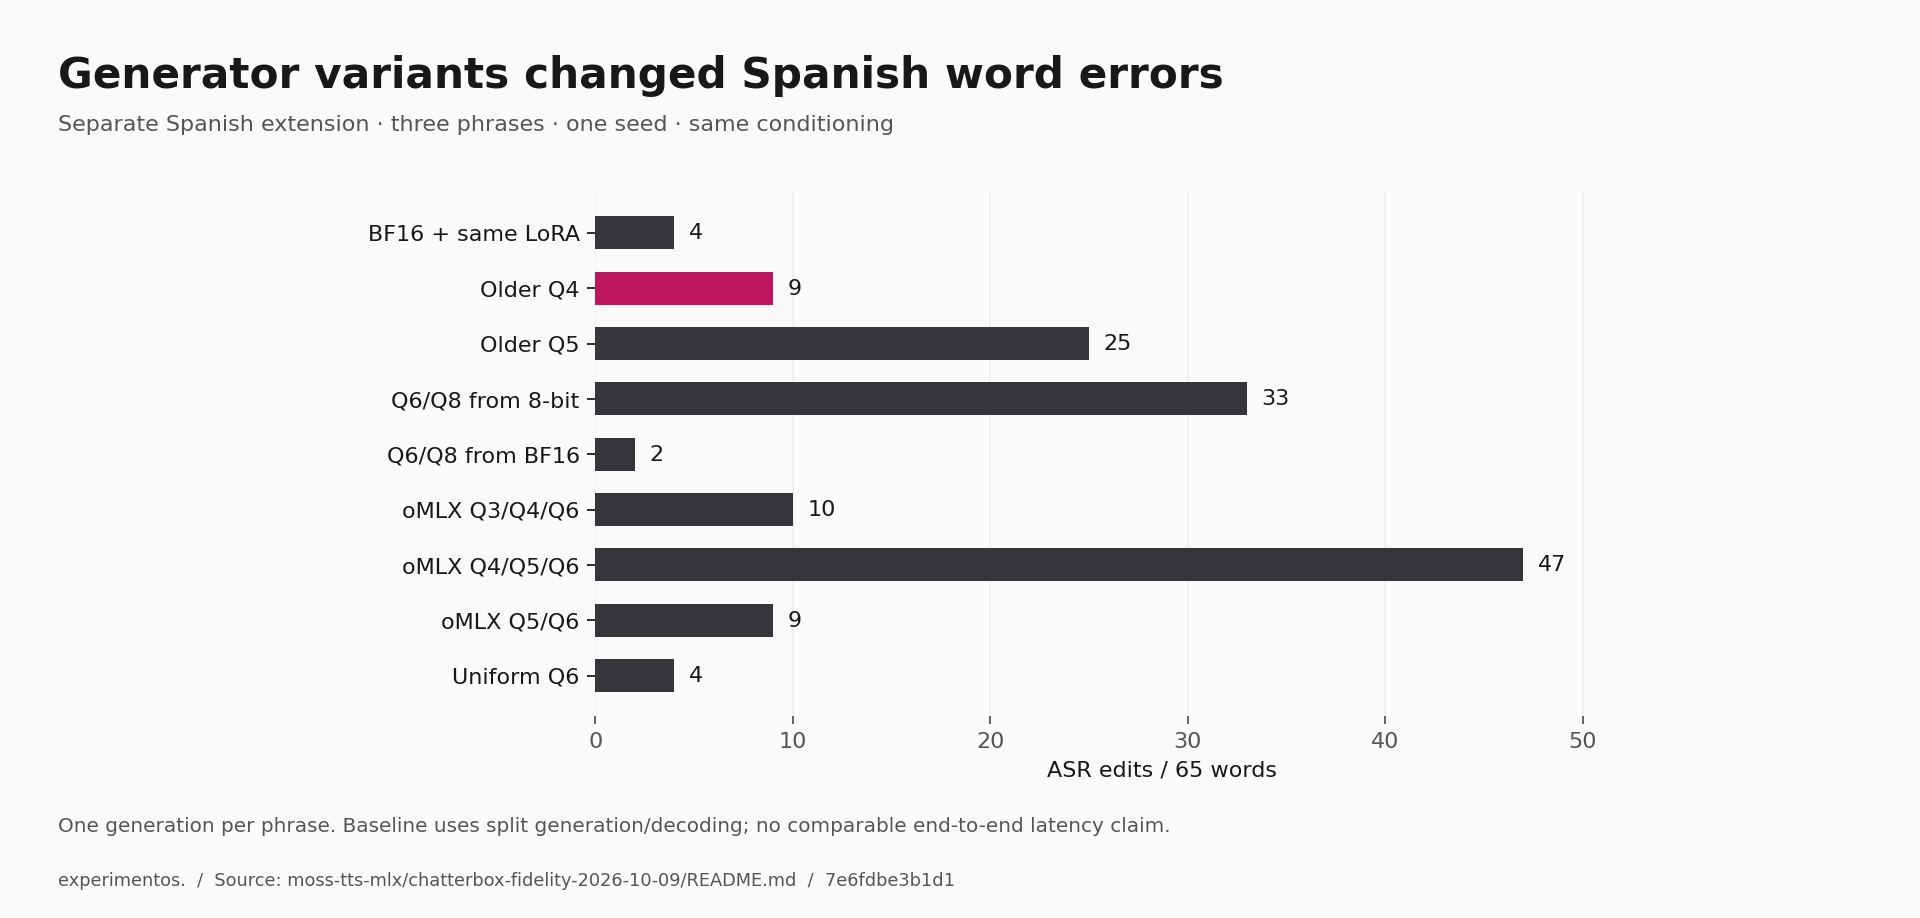
| MOSS: the best similarity score did not mean the fewest word errors | Speech & codecs | Q6/Q8 built directly from BF16 had the fewest Spanish ASR edits, while the older Q4 had higher speaker cosine. | |
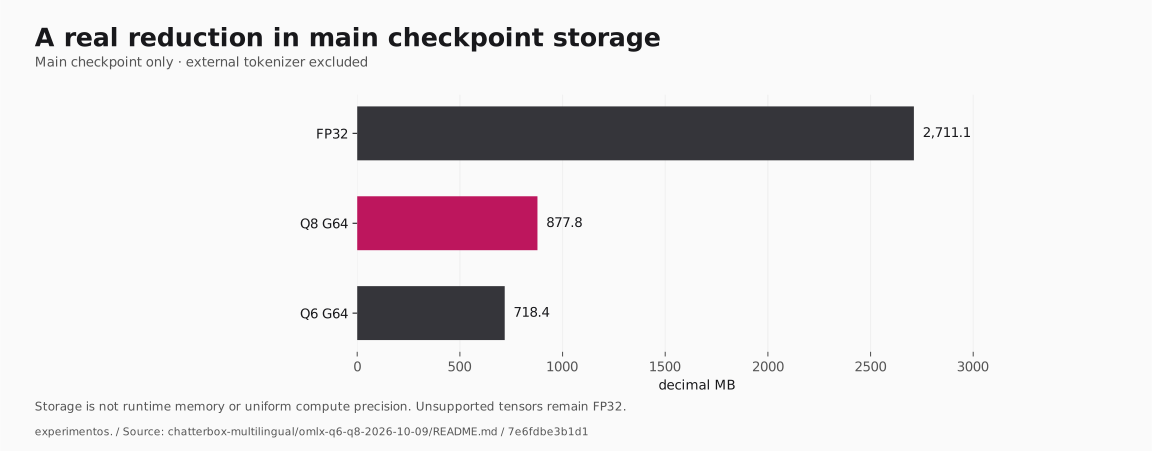
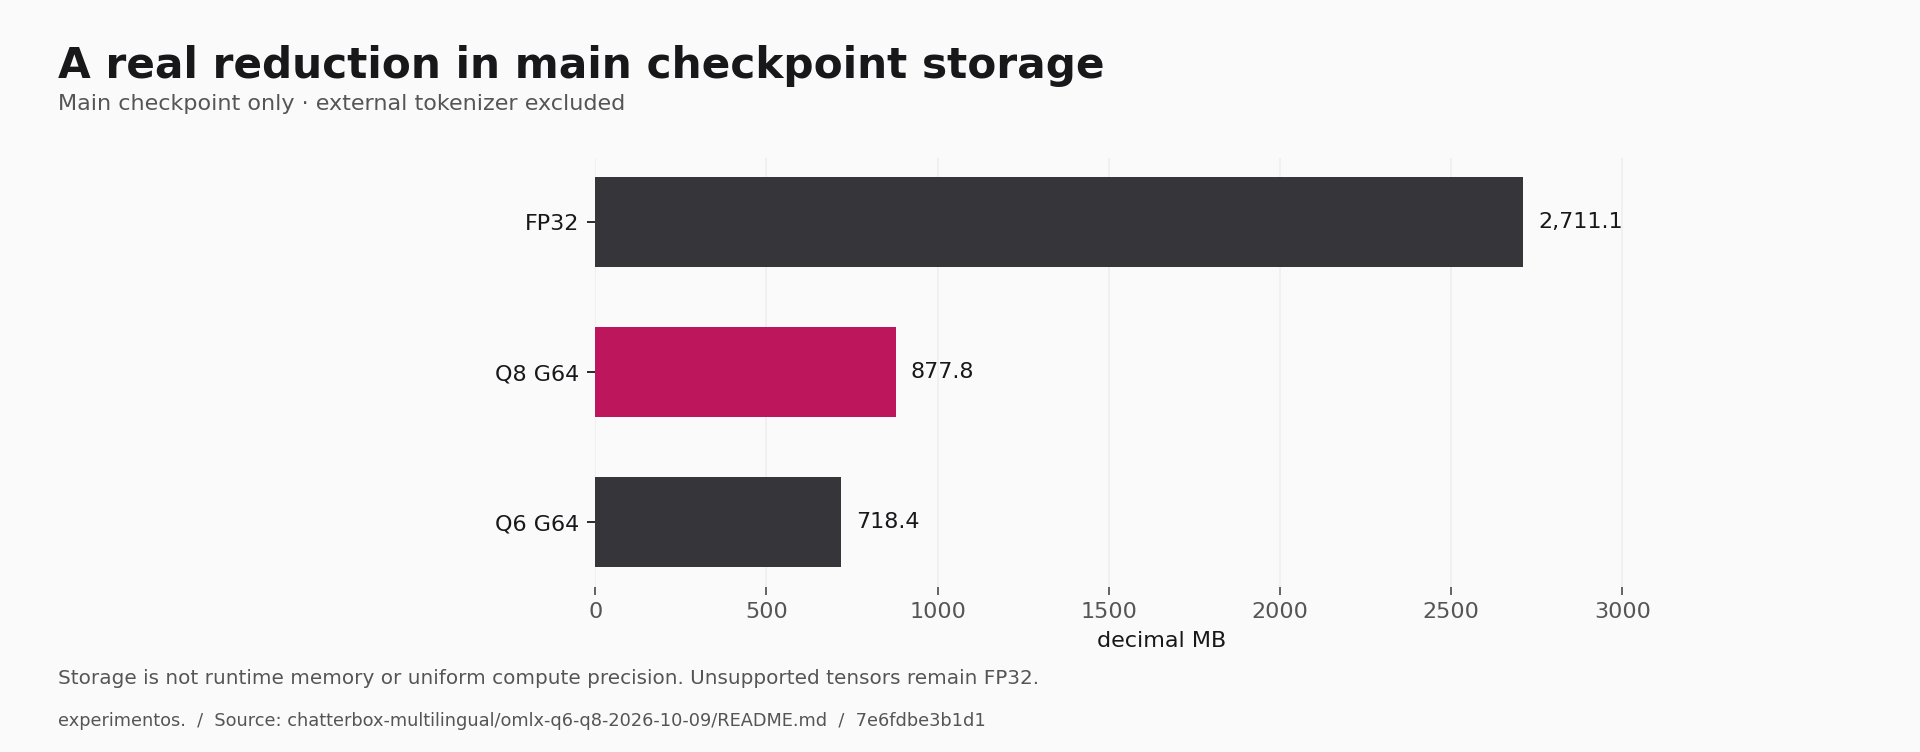
| Q6 saved space; predicted MOS did not settle naturalness | Speech & codecs | Q6 reduced the main checkpoint by 18.2% versus Q8, while their English predicted-MOS difference remained uncertain. | |
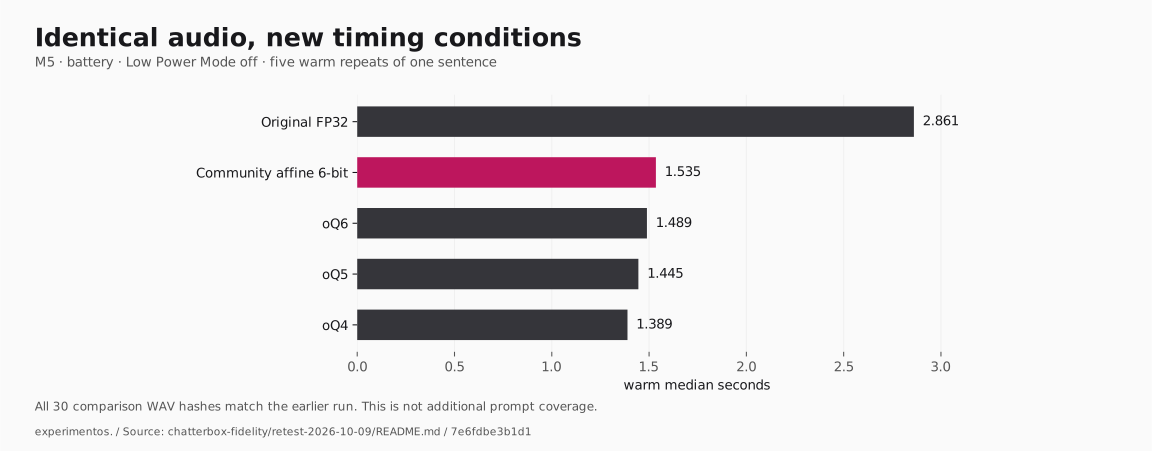
| The audio was identical. The benchmark numbers changed. | Speech & codecs | Apple M5 | All 30 comparison WAV hashes matched the earlier run, while timings and four ASR transcripts changed. |
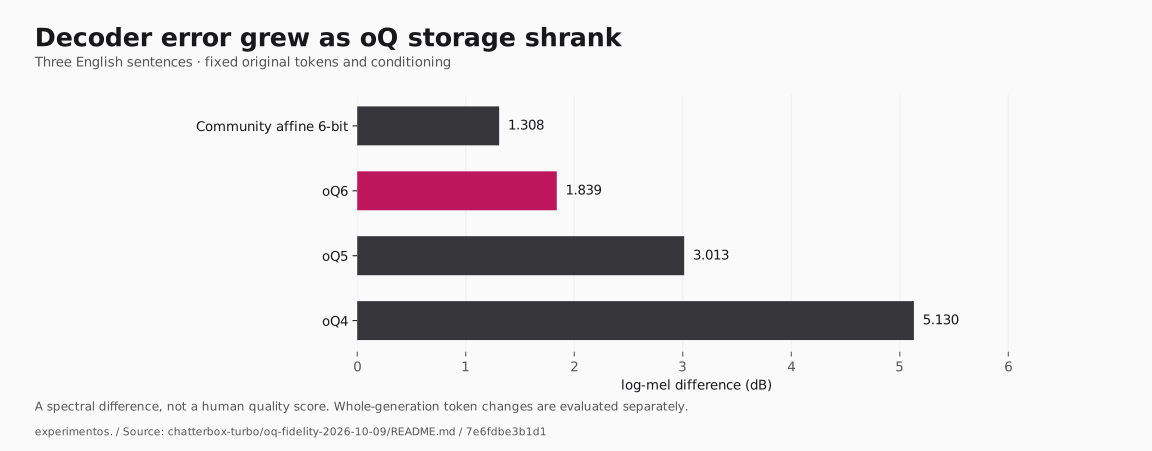
| What six bits preserved in Chatterbox Turbo | Speech & codecs | Community affine 6-bit had the closest controlled decoder output among the tested quantized candidates; oQ6 led the new oQ variants. | |
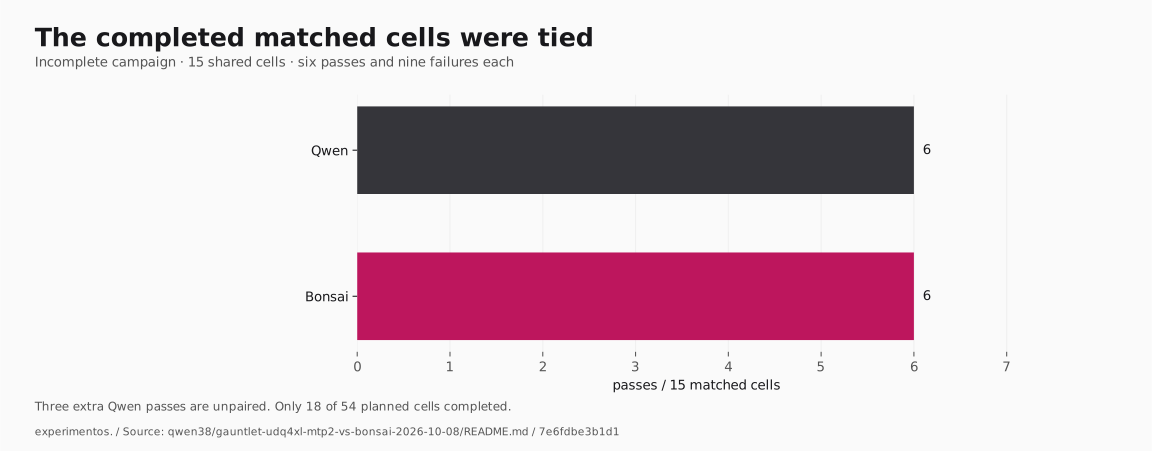
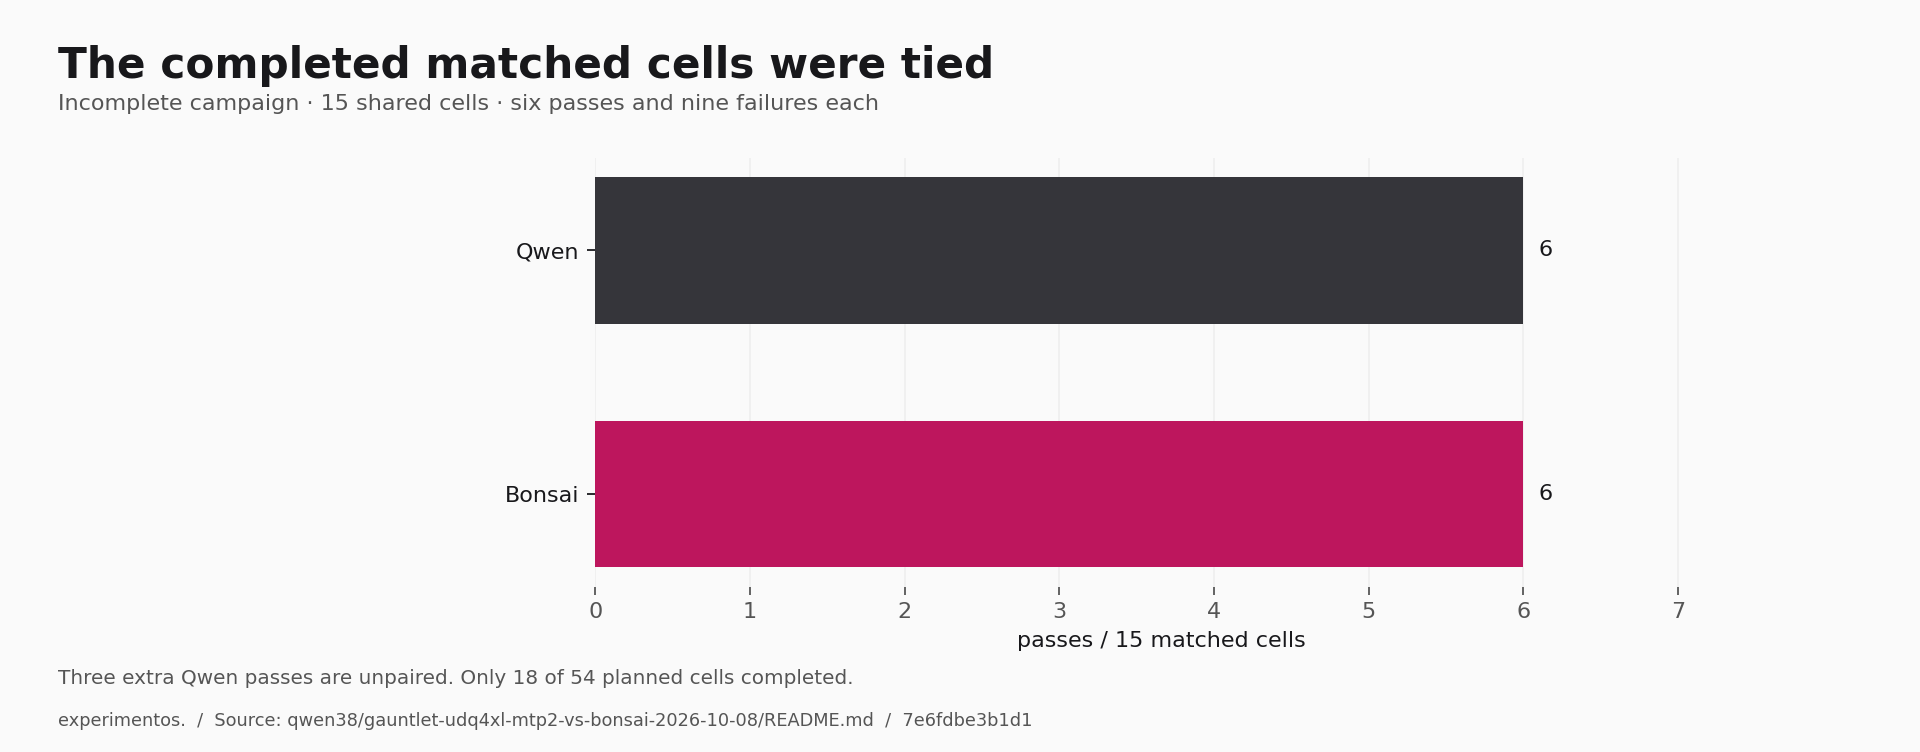
| An unfinished gauntlet cannot name a winner | Language models | The 15 matched cells tied: six passes and nine failures for each model. | |
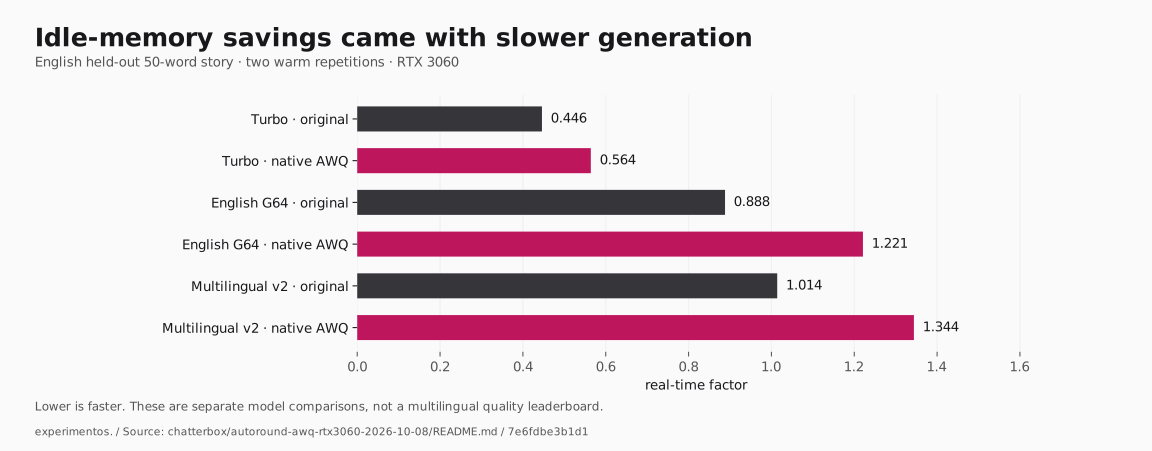
| Native AWQ saved idle memory and cost speech time | Speech & codecs | RTX 3060 | The native AWQ candidates saved roughly 0.40–0.69 GiB at idle but were slower on the tested speech workloads. |
| Spanish Chatterbox: smaller weights, uneven speech | Speech & codecs | The emulated FP8 variant was a useful listening candidate; several smaller alternatives produced silence, tails or slower speech. | |
| The fastest kernel was not the qualified speech stack | Speech & codecs | HQ4, SDPA and the GPU INT8 codec formed the qualified fitting stack; a faster kernel experiment lacked complete audio evidence. | |
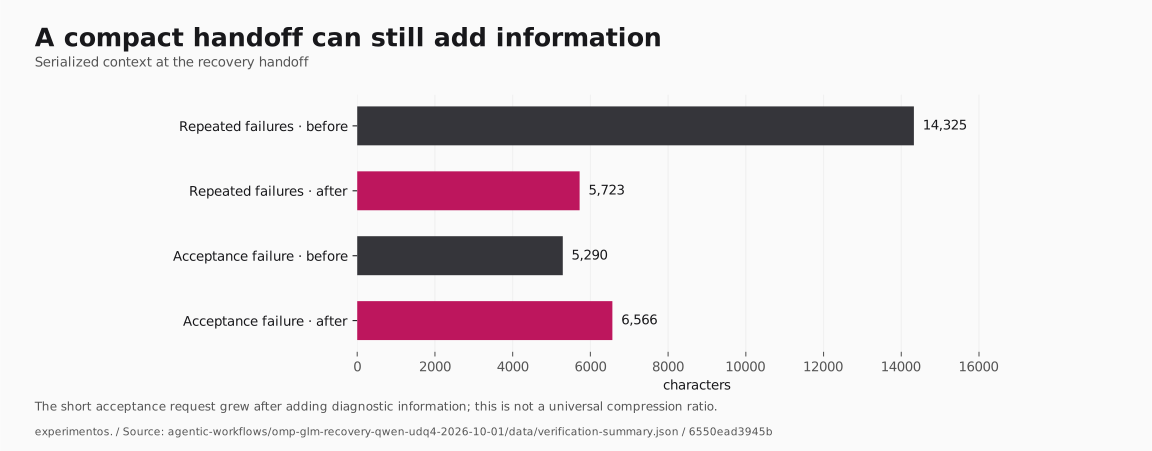
| 144 recoveries, one carefully bounded task | Agents & systems | All 144 supervised continuations completed; a smaller handoff used fewer worker tokens. | |
| A context setting is not a context test | Language models | The largest verified successful coding prompt was 49,124 tokens; larger configured windows remained unproven. | |
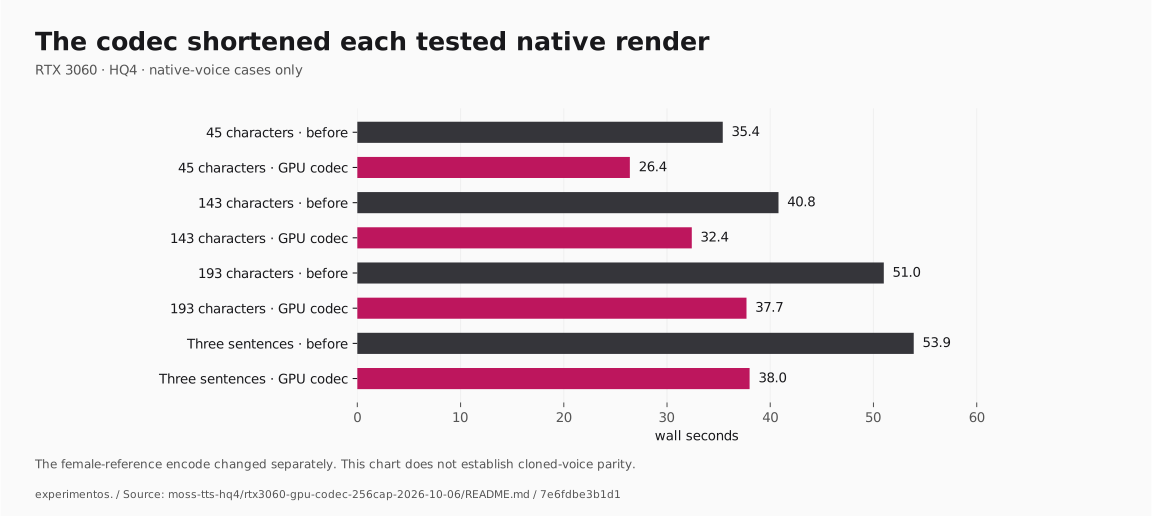
| Making MOSS fit: the codec and the chunk budget | Speech & codecs | RTX 3060 | GPU codec decoding cut several seconds from each tested render, but the token cap still required shorter text chunks. |
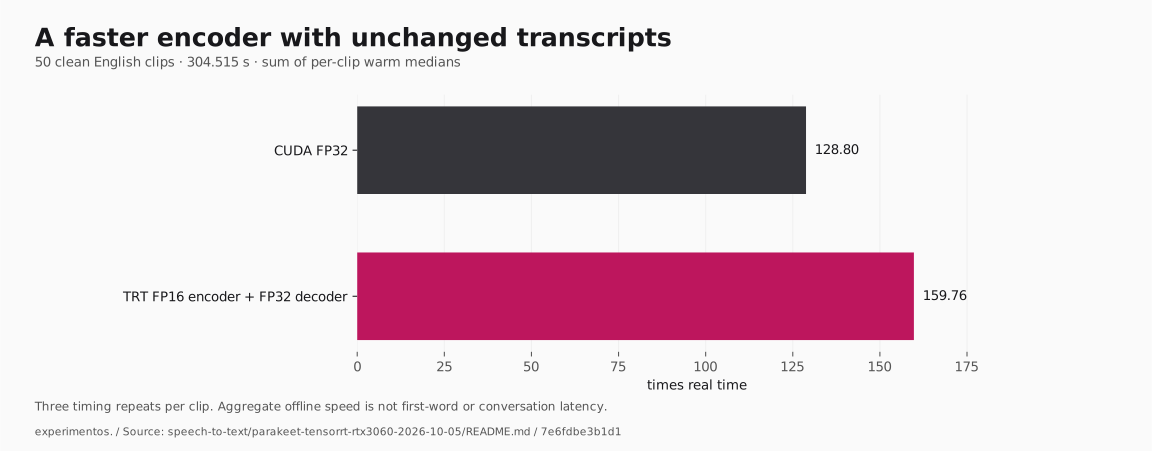
| A faster speech encoder with the same 50 transcripts | Speech & codecs | RTX 3060 | TensorRT FP16 encoding raised measured throughput from 128.80× to 159.76× real time with identical transcripts. |
| Why a busy speech GPU felt slower | Speech & codecs | Mixed speech, embedding and synthesis traffic increased latency even when every request passed. | |
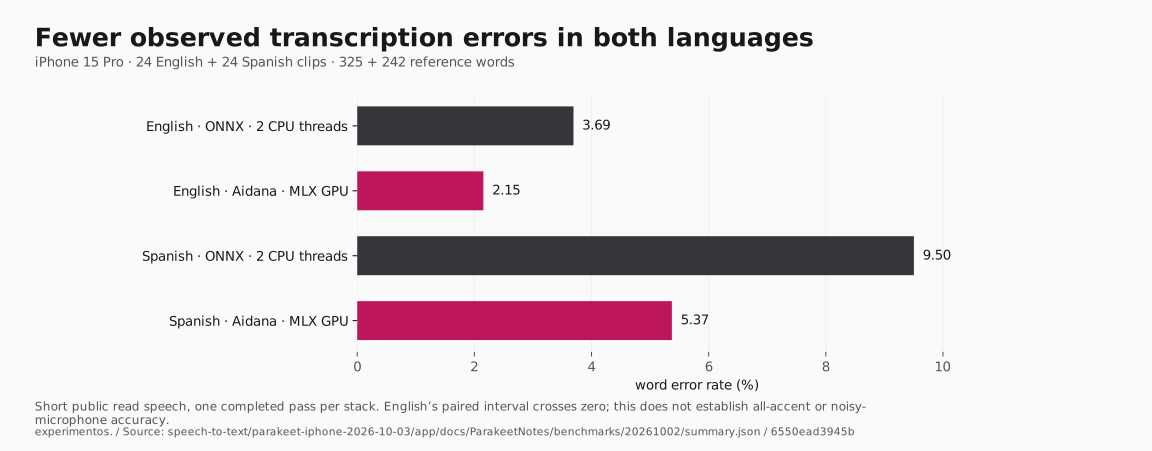
| A smaller speech model earns its place on the iPhone | Speech & codecs | iPhone 15 Pro | Aidana transcribed the 47 matched clips 3.35 times faster, with observed English WER of 2.15% and Spanish WER of 5.37%. |
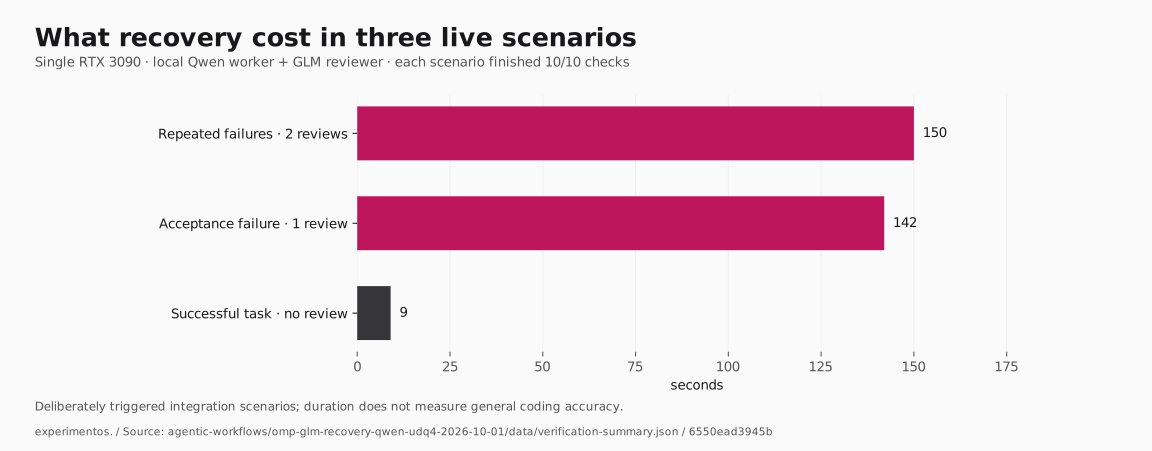
| A coding agent that knows when to ask for help | Agents & systems | RTX 3090 | Three live recovery scenarios passed, each finishing with 10/10 checks. |
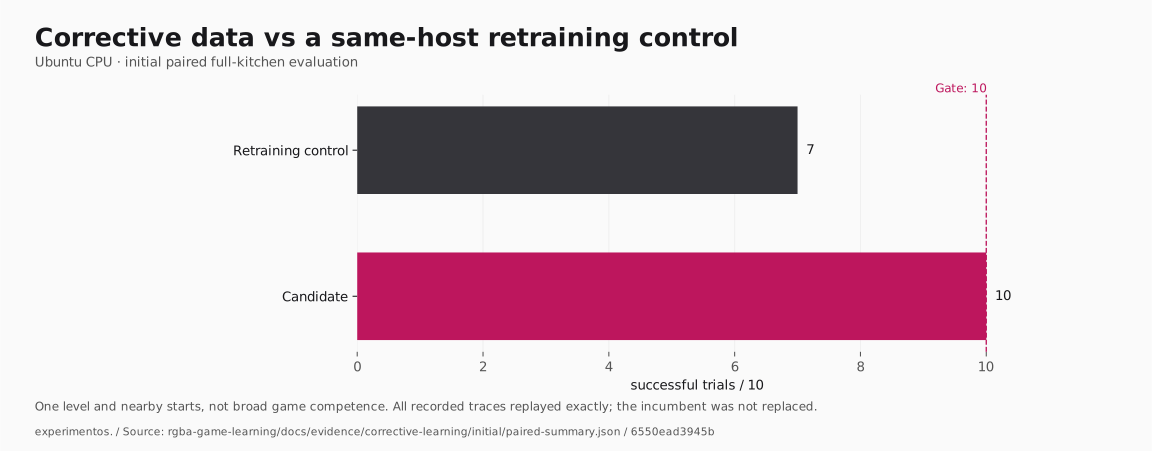
| Corrective data meets a fresh gameplay gate | Game learning | On Ubuntu CPU, the corrected policy passed 10/10 full-kitchen trials against a same-host retraining control at 7/10. | |
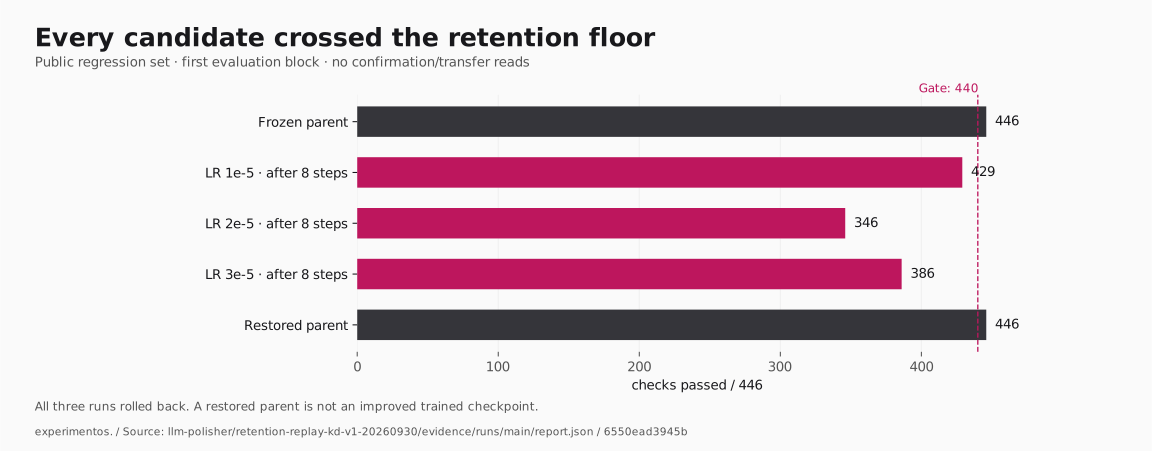
| When the retention gate says stop | Training & adaptation | All three registered learning rates crossed the retention floor after eight steps and rolled back. | |
| A second dish, a new frozen test | Game learning | The corrected candidate passed 10/10 paired two-dish trials against a frozen baseline at 0/10. | |
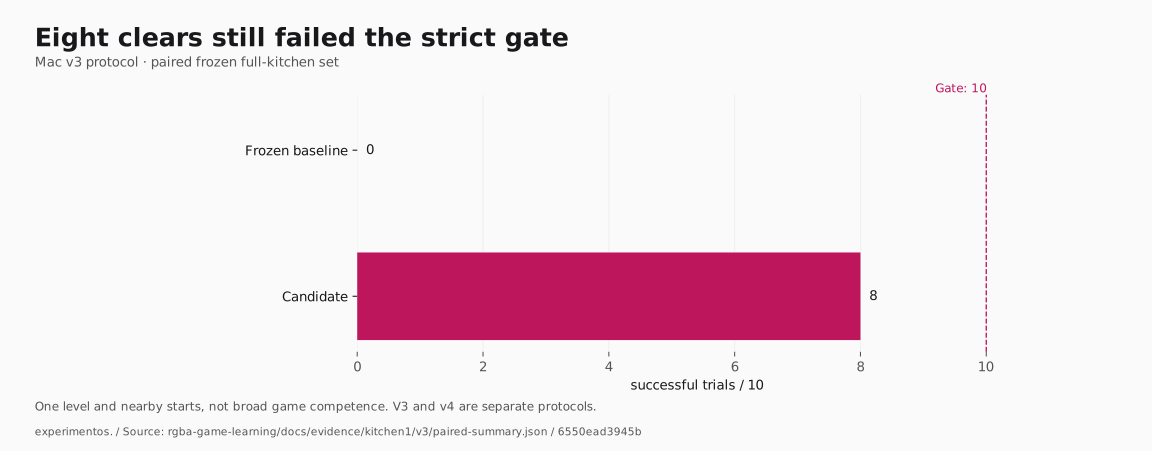
| Eight clears are still not a promotion | Game learning | The v3 protocol measured 8/10 full-stage clears versus 0/10 for its paired baseline; the strict gate rejected it. | |
| Learning to play from pixels | Game learning | The first-dish baseline produced six successful recorded evaluations across five starting positions, with exact replay. | |
| The reusable RGBA learning pipeline | Game learning | Owned frames, bounded controls, saved state, teacher-data export and exact replay form one auditable pipeline. | |
| What counts as a successful episode? | Game learning | The evaluator tightened survival, terminal-state and exact-replay checks without rewriting historical experimental outcomes. | |
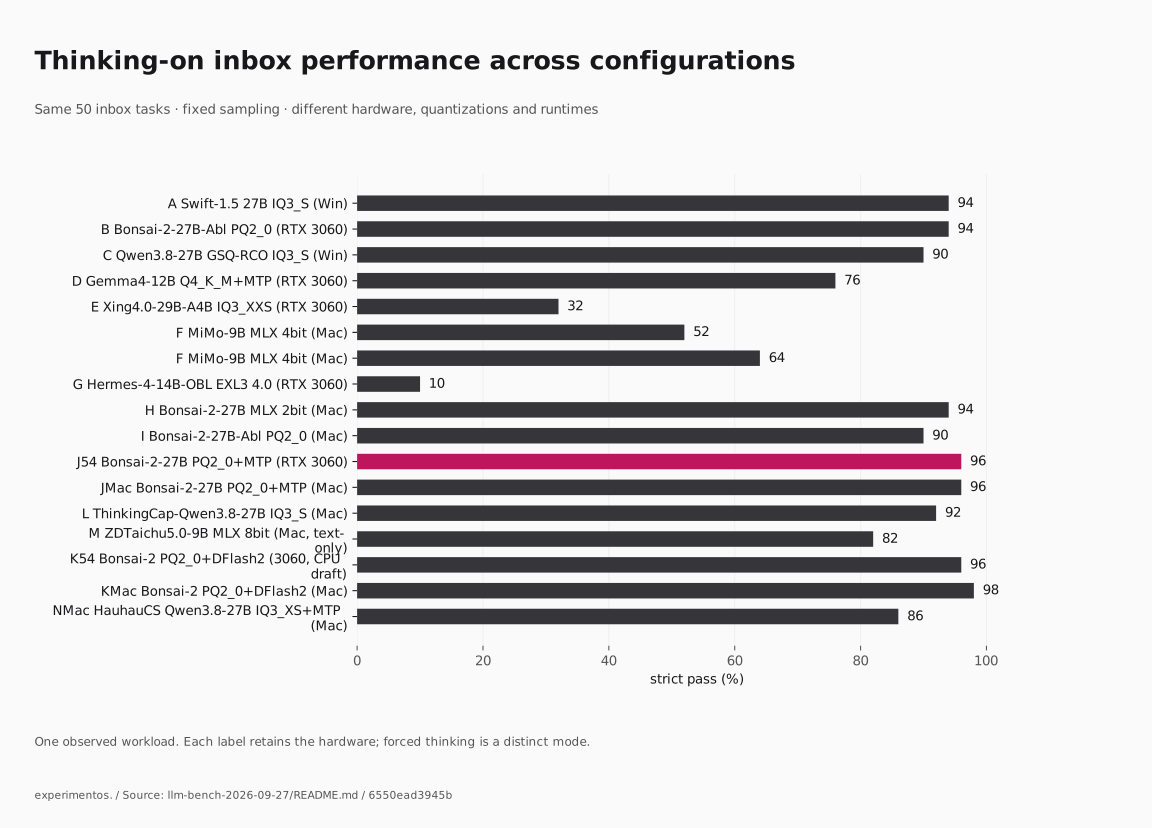
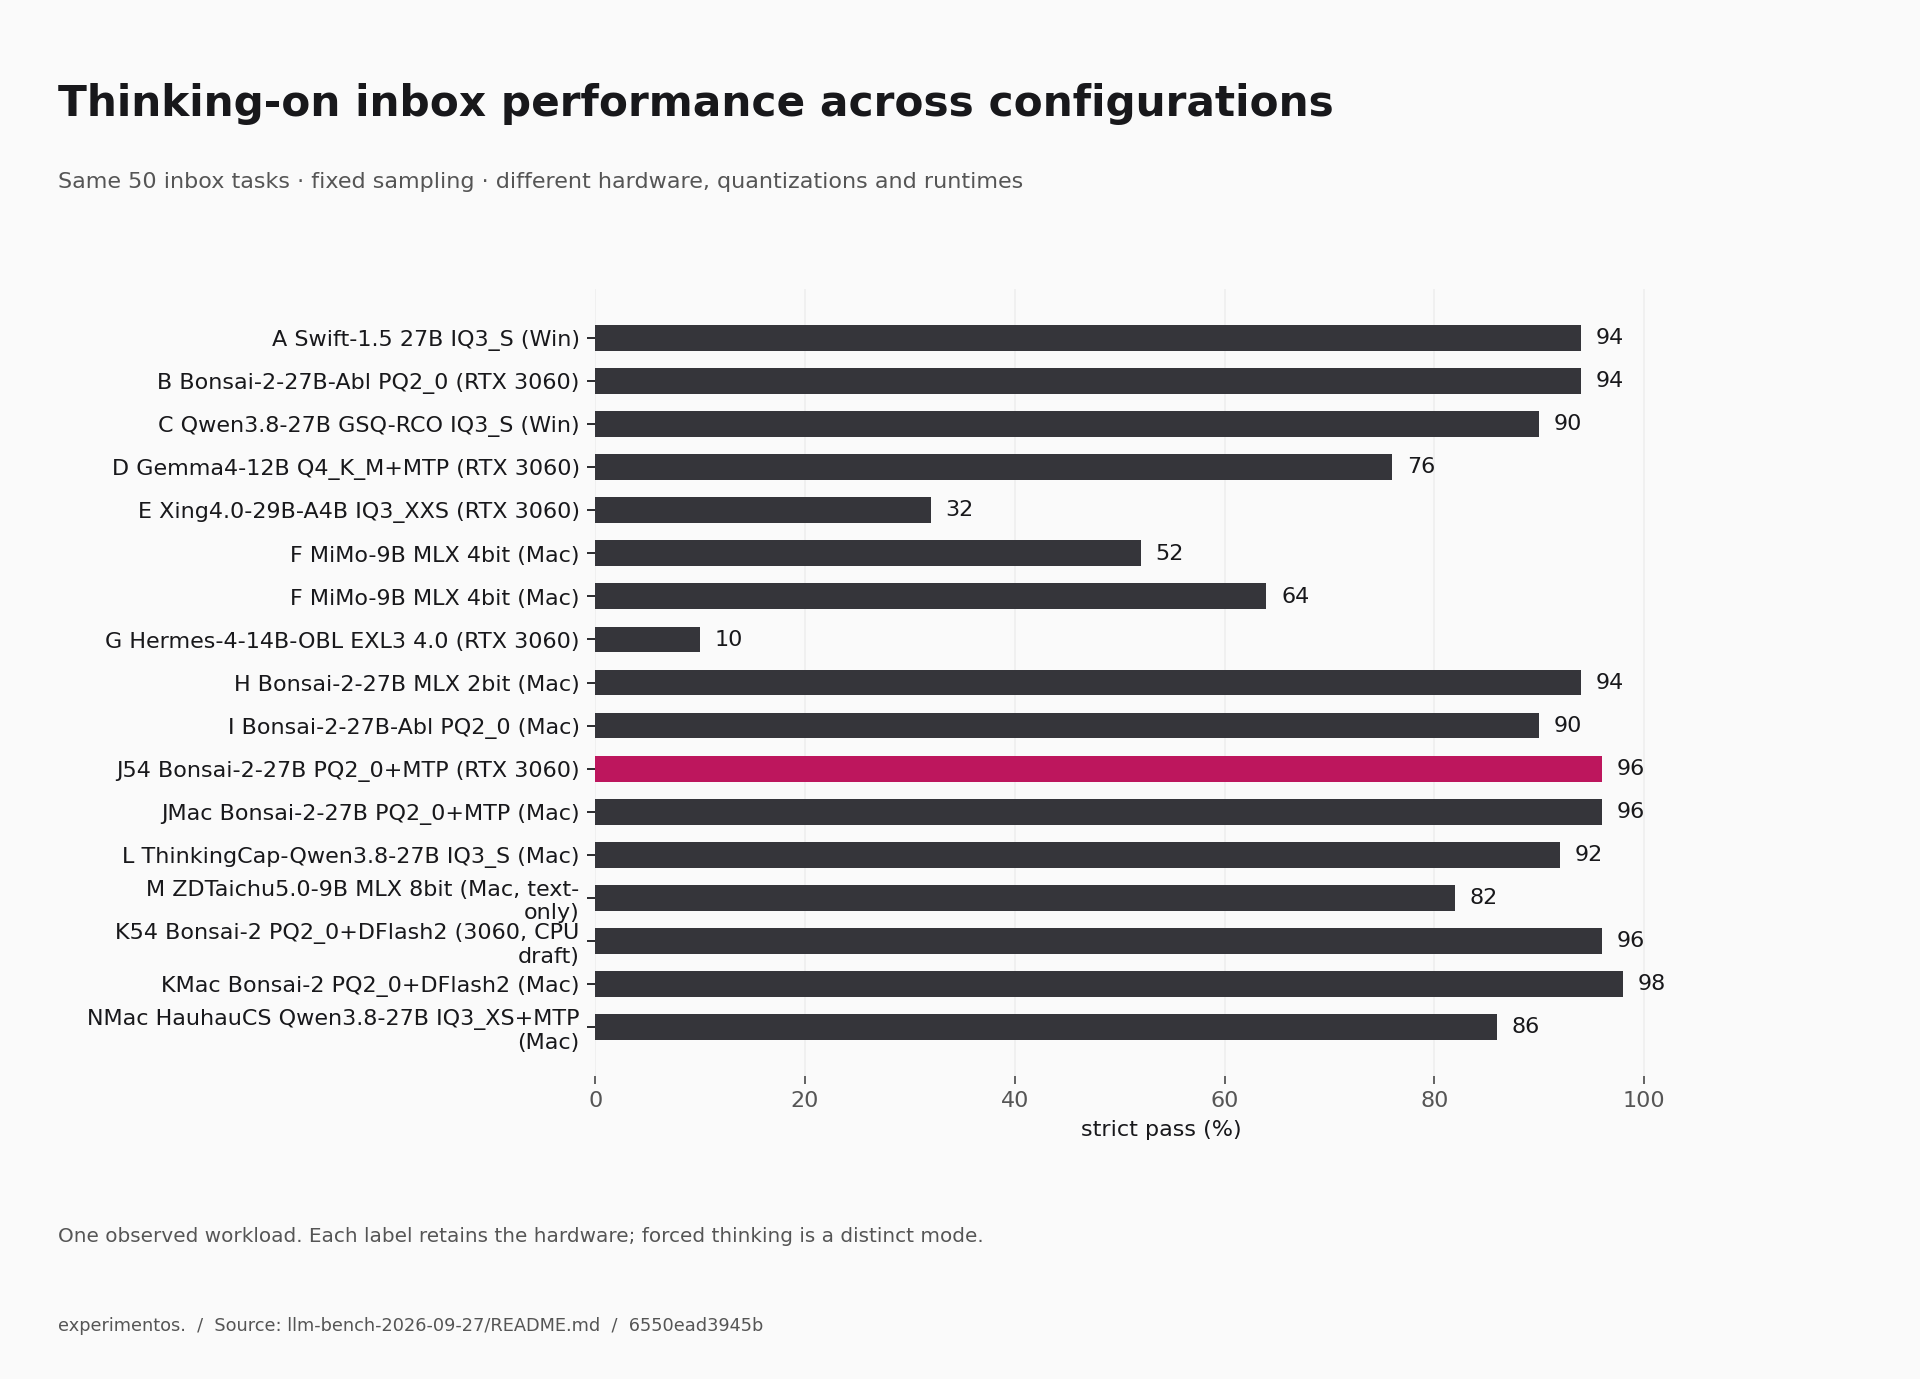
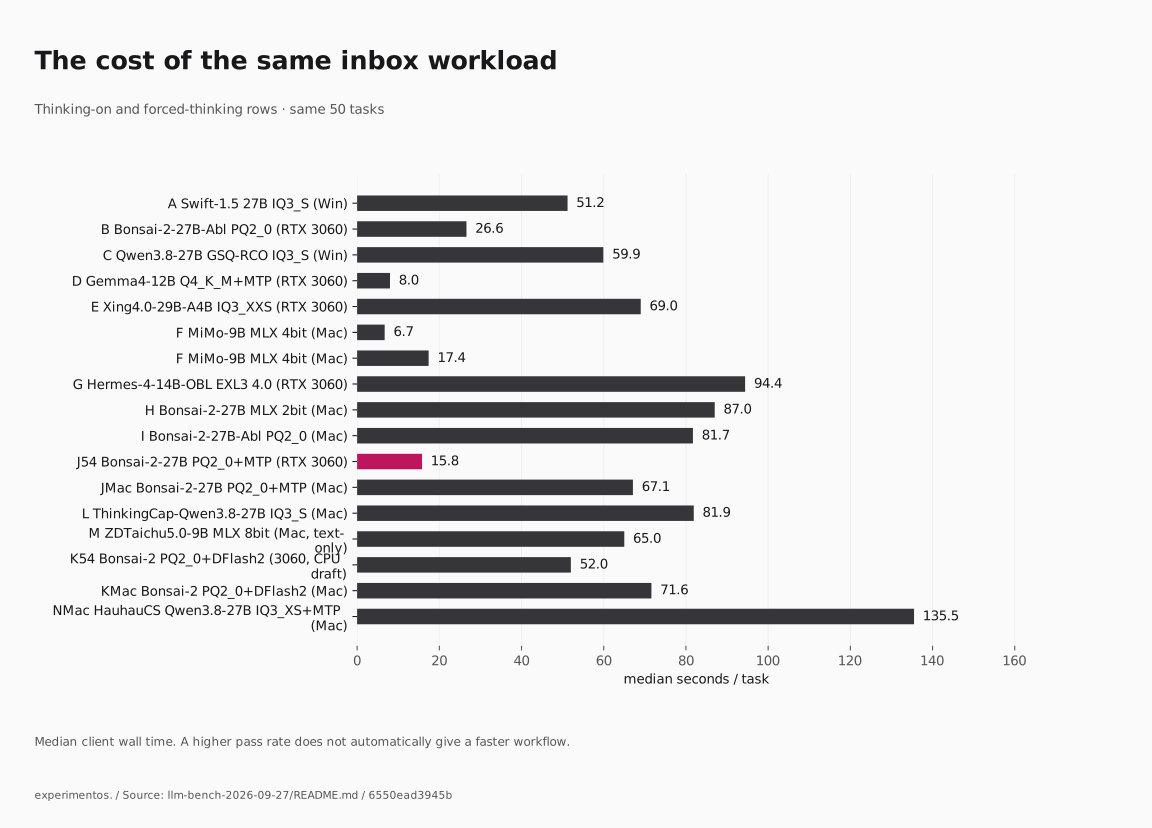
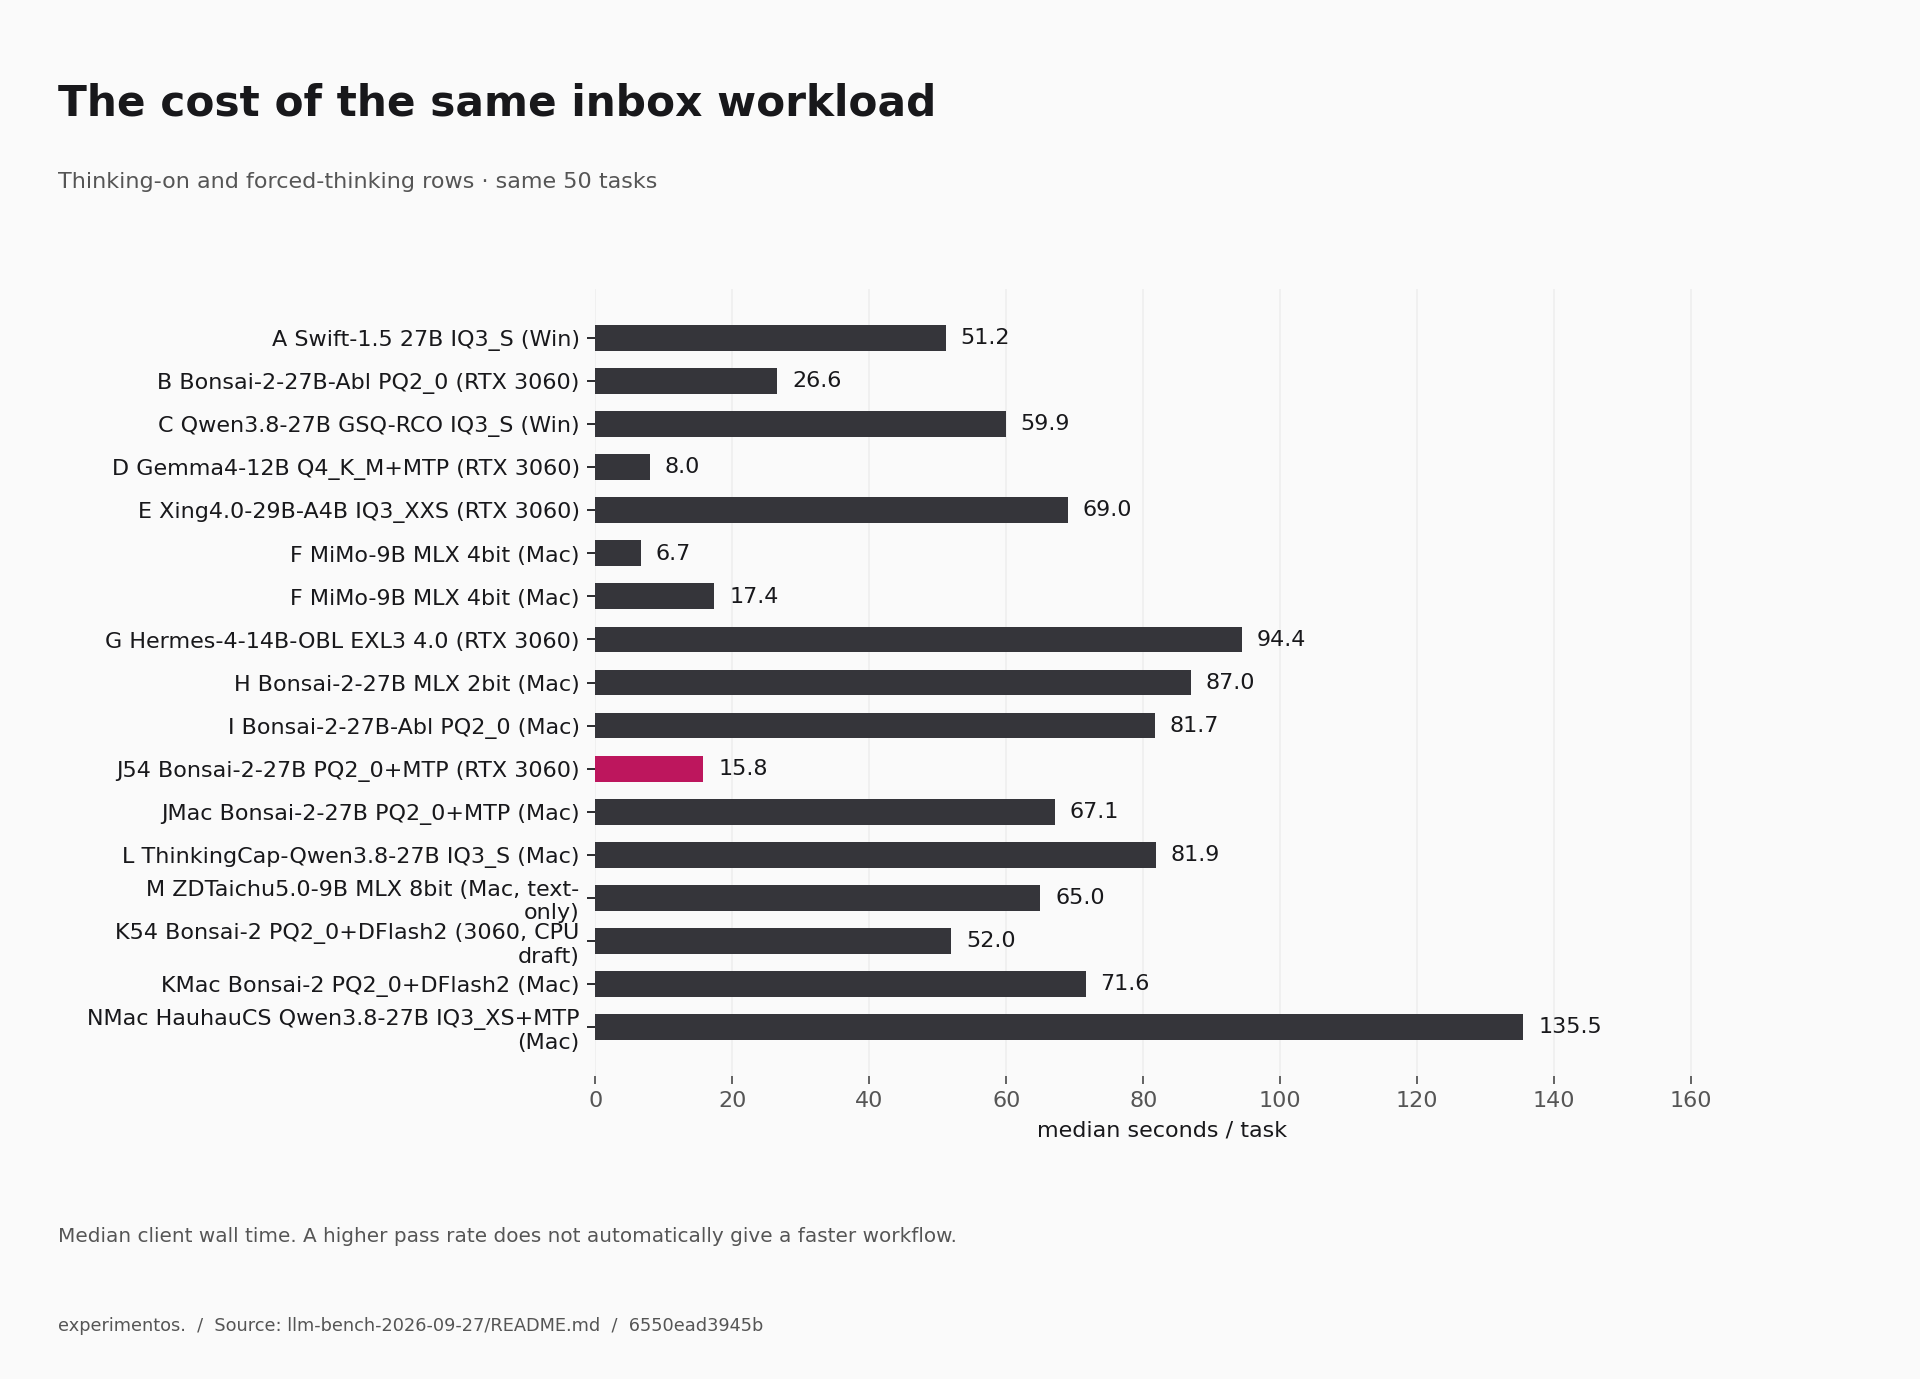
| Finding a local model for the inbox | Language models | Bonsai-2-27B PQ2_0 with MTP passed 48/50 tasks with thinking on, at a 15.8-second median on an RTX 3060. | |
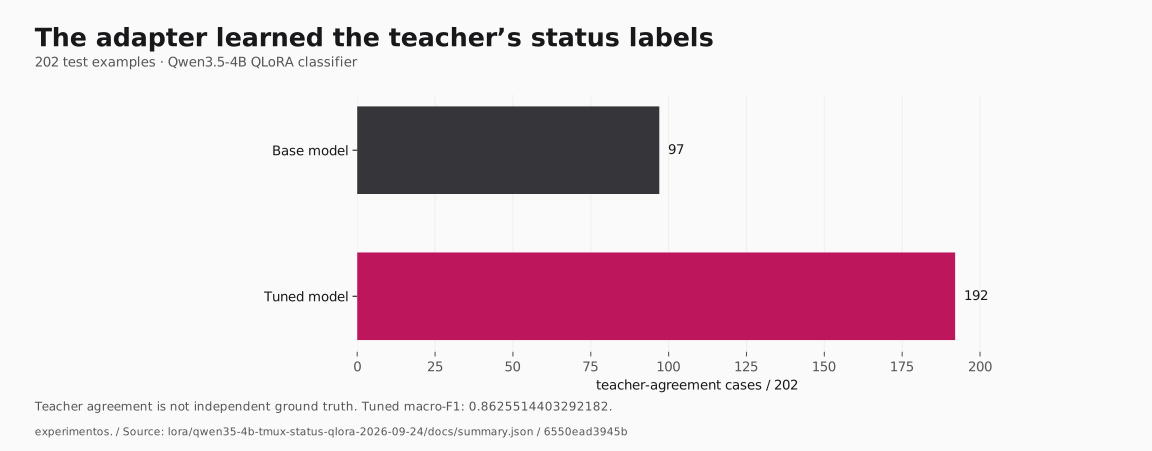
| Teaching a 4B model to read tmux status | Training & adaptation | The classifier matched its teacher on 192/202 examples, with macro-F1 0.863. | |
| An image editor that respects the pixels you keep | Images & video | A real masked object removal finished in 24.39 seconds and preserved every unselected decoded pixel exactly. | |
| Character LoRAs: identity, motion, and continuity | Images & video | Three initial adapters completed: 600 LTX steps and two Qwen identity runs of 800 steps each. | |
| Fifteen pictures, one photographic-style adapter | Images & video | 213 files became 97 unique decoded images; the curated random selection used 15 distinct photographs or photo-like images. | |
| Making the keyboard lock key really sleep the phone | Devices & tools | A keyboard-specific handler preserved the lock gesture and the display reached OFF roughly 0.7 seconds later. | |
| Masked cleanup before a fresh LoRA | Images & video | 25 distinct images were cleaned into lossless copies, preserving dimensions and all decoded pixels outside each mask. | |
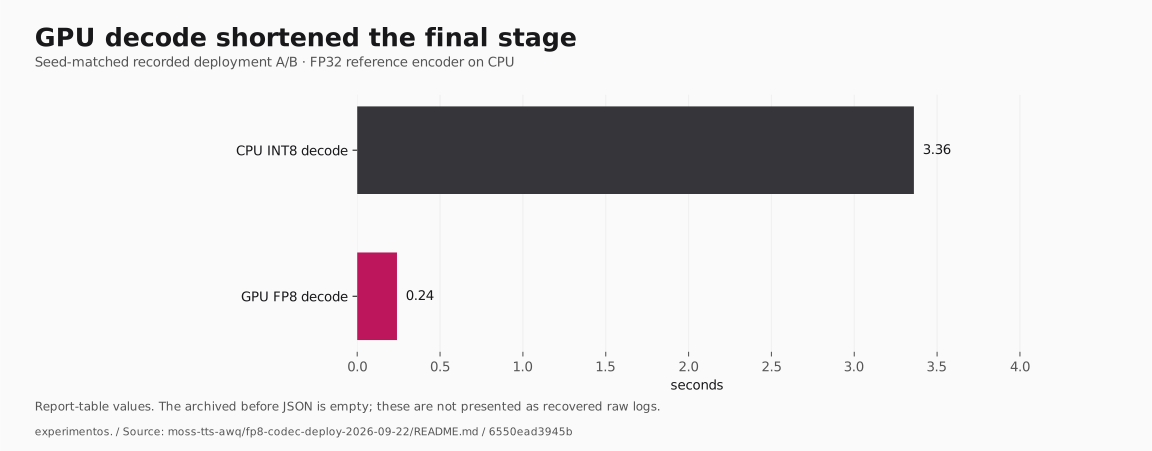
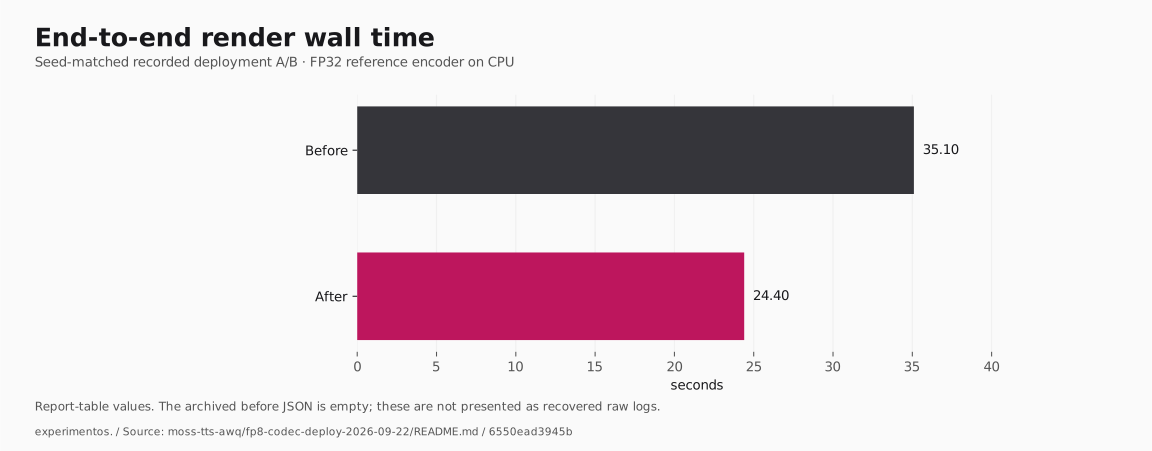
| Moving speech decode onto the GPU | Speech & codecs | Decode dropped from 3.36 seconds to 0.24; total render wall time dropped from 35.1 to 24.4 seconds. | |
| Putting a watermark gate in front of training | Images & video | The binary screen accepted 24/25 cleaned images; both known positive controls were detected. | |
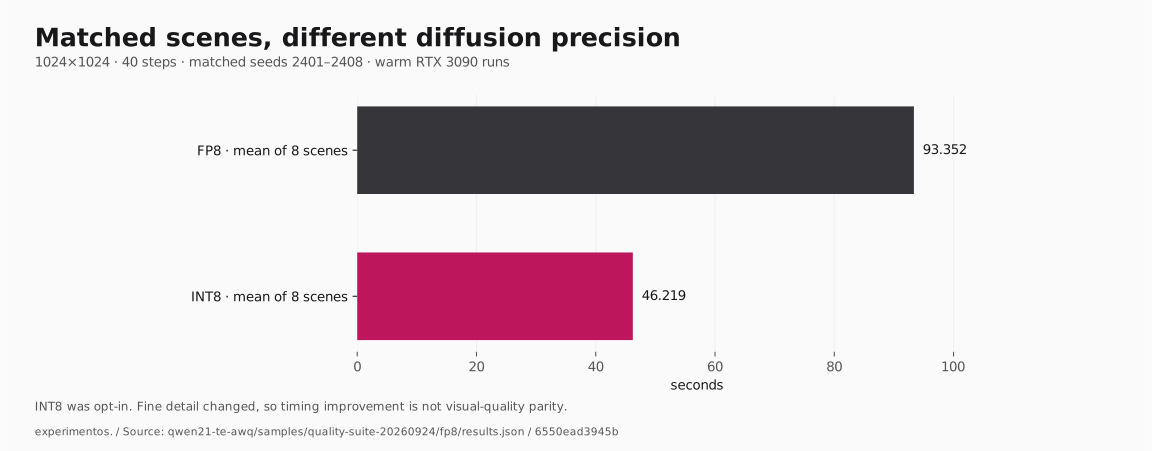
| A complete image stack on one 24GB GPU | Images & video | RTX 3090 | Eight matched 1024-square scenes averaged 93.352 seconds with FP8 and 46.219 with opt-in INT8. |
| Long speech, bounded memory | Speech & codecs | A 551-character, eight-sentence input rendered in two chunks with 48.0 seconds of healthy audio. | |
| Round-trip tests expose a broken encoder | Speech & codecs | The new 1.76GB FP8-E4M3 codec reached FP32-control parity in the measured round-trip test with its encoder intact. | |
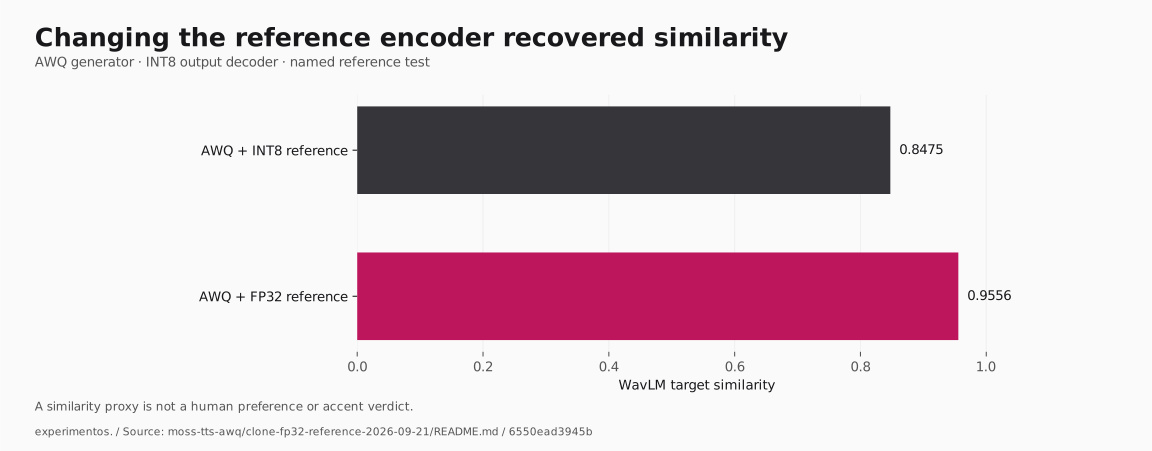
| The clone bug was in the reference encoder | Speech & codecs | Using FP32 reference encoding lifted AWQ WavLM target similarity from 0.8475 to 0.9556 while retaining INT8 output decode. | |
| The faster image pipeline that produced nothing | Images & video | The balanced two-GPU path took 48.1 seconds but every image was invalid flat gray noise. | |
| The same story, six precision combinations | Speech & codecs | Generator precision affected the measured ranking; changing the output codec shifted similarity by at most about 0.001. | |
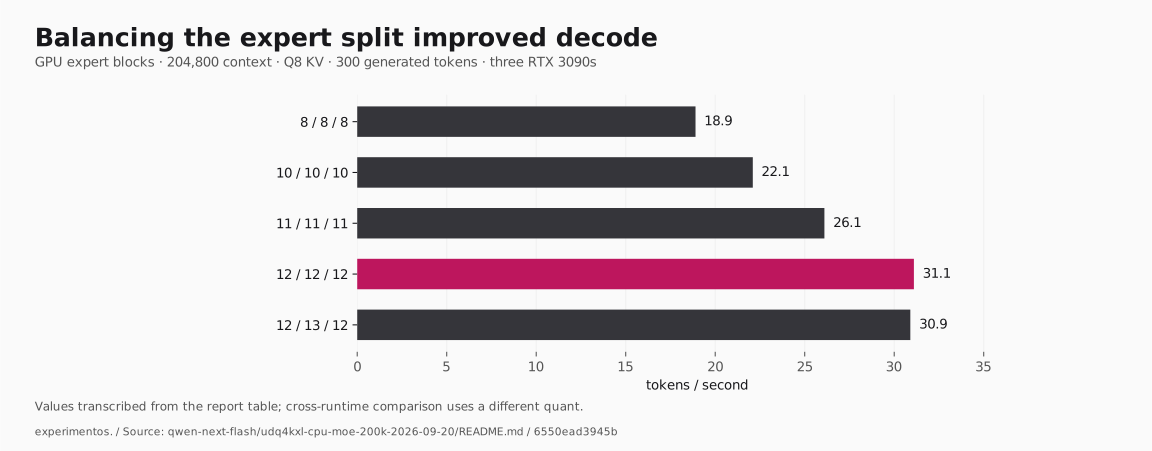
| Balancing GPU experts when the model will not fit | Language models | RTX 3090 | An explicit 12/12/12 GPU expert split plus 12 CPU blocks measured 31.1 tokens per second. |
| Pipeline parallelism, INT4, and a 262K context | Language models | The patched vLLM stack measured 67.4 tokens per second for one stream and 73.1 aggregate for two. | |
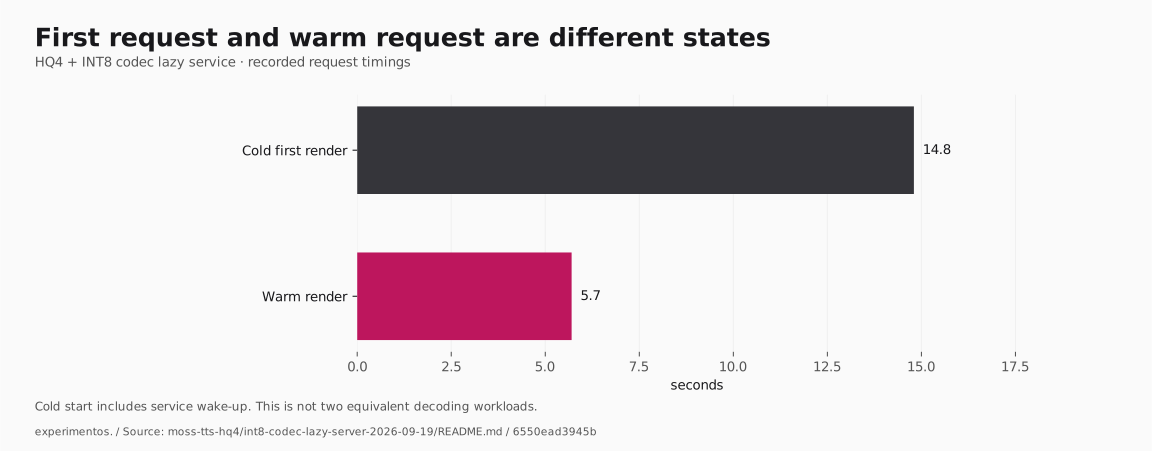
| A speech service that sleeps between requests | Speech & codecs | The recorded service used about 10.3GB resident memory; first render took 14.8 seconds and warm render 5.7. | |
| A quantization job goes silent | Speech & codecs | The full-spec job stopped after six of 36 blocks; the monitor detected the dead wrapper and idle GPU. | |
| AWQ speech: fast enough, with a memory catch | Speech & codecs | AWQ passed 33/33 prompts with pooled real-time factor 0.43 and 35.8 tokens per second. | |
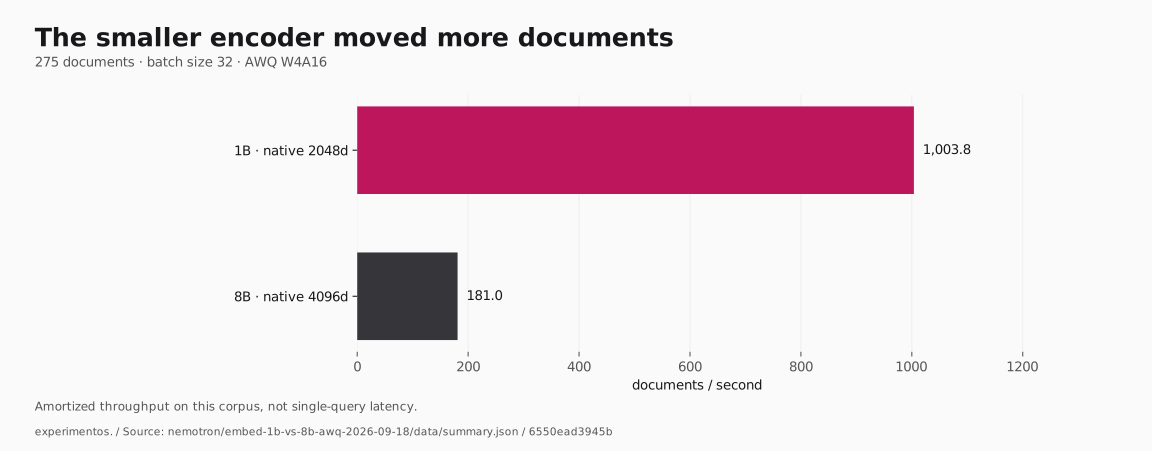
| Do you really need the bigger embedding model? | Language models | The 1B encoder embedded 1,004 documents per second; the 8B encoder reached 181, with no proven retrieval-quality win. | |
| FP32, BF16, INT8: separating codec drift from speech | Speech & codecs | Pure TTS legs shared token sequences, and normalized transcription differences were zero across the tested codec legs. | |
| Keeping the audio-sensitive layers intact | Speech & codecs | The HQ4 preview matched 96.5% of text tokens in the greedy test and passed three staged-memory probes at 6.7–6.8 GiB. | |
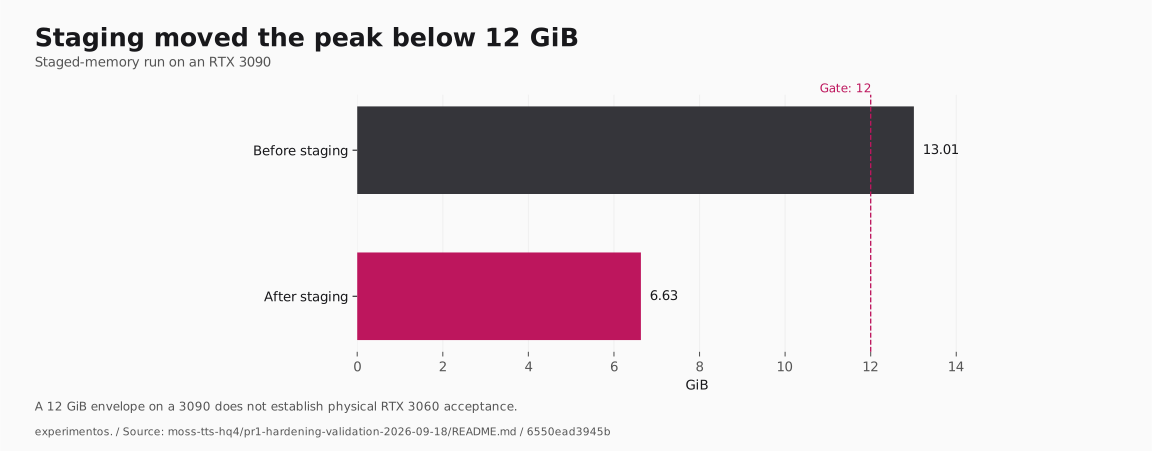
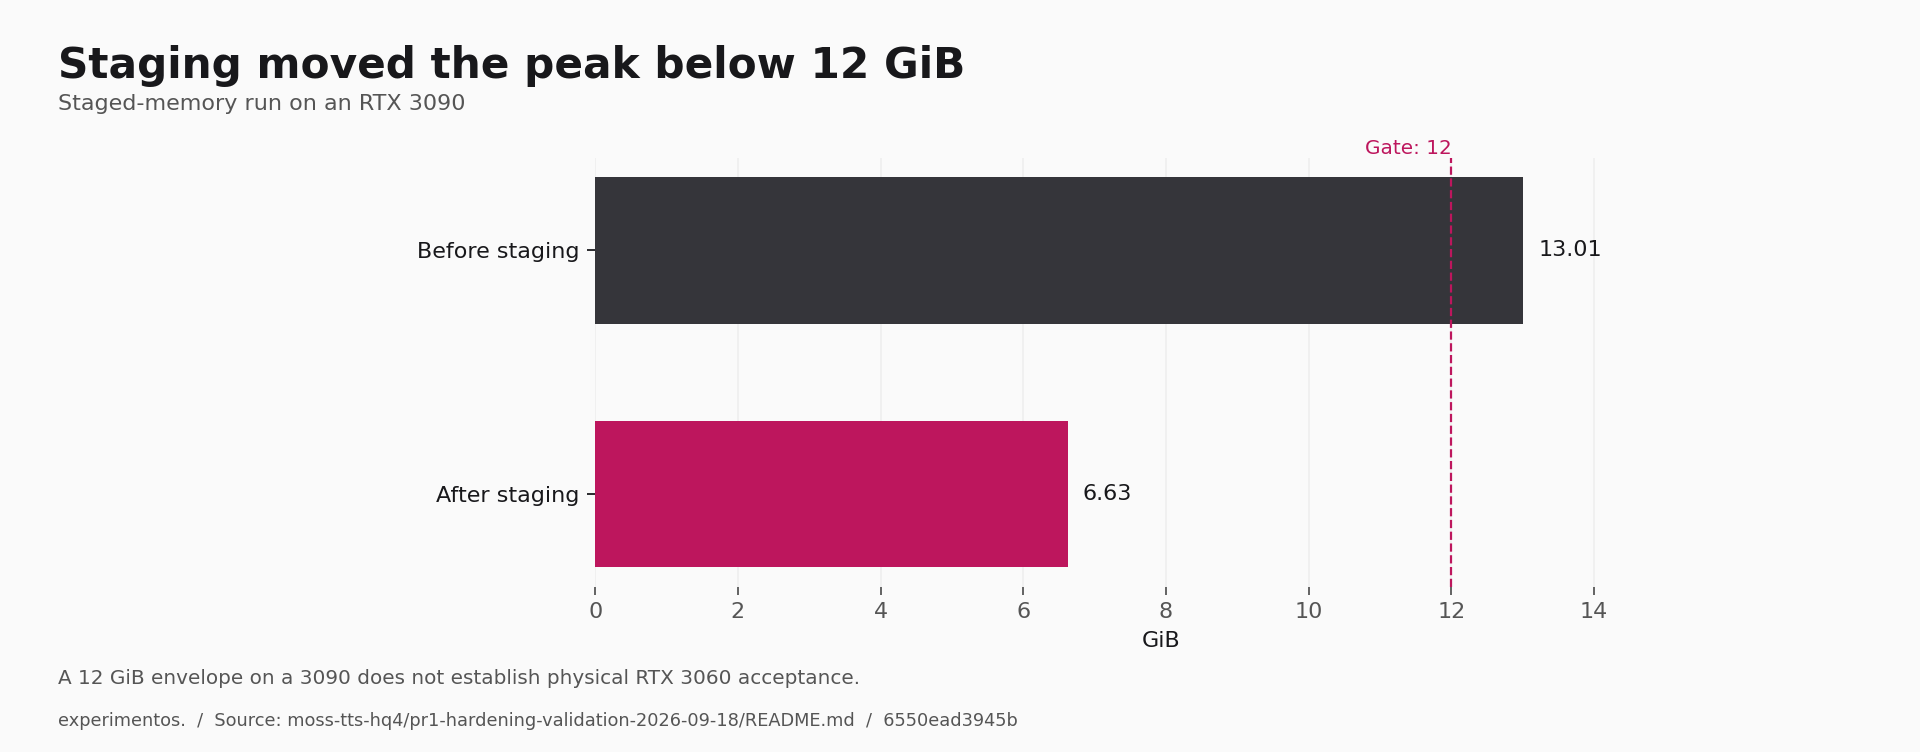
| Staging the speech stack under a 12GB envelope | Speech & codecs | RTX 3090 | The staged run peaked at 6.63 GiB, down from 13.01 before staging; 252 INT4 projections passed the verifier. |
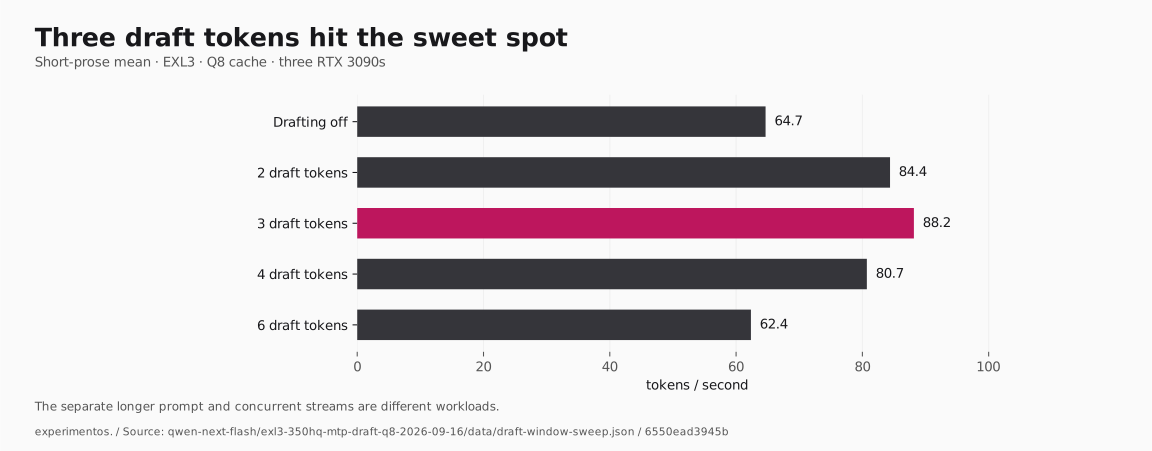
| Three draft tokens hit the sweet spot | Language models | RTX 3090 | Draft length three reached a short-prose mean of 88.16 tokens per second, versus 64.67 with drafting off. |
| From a model download to a working local service | Language models | The deployment notebook records the EXL3 serving family, cache choices and real runtime constraints. | |
| The EXL3 quantization journey | Language models | The notebook follows official BF16 weights through EXL3 conversion, artifact checks and deployment work. | |
| A model proxy earns its promotion | Agents & systems | The promoted merge passed 107 tests with one environmental skip. | |
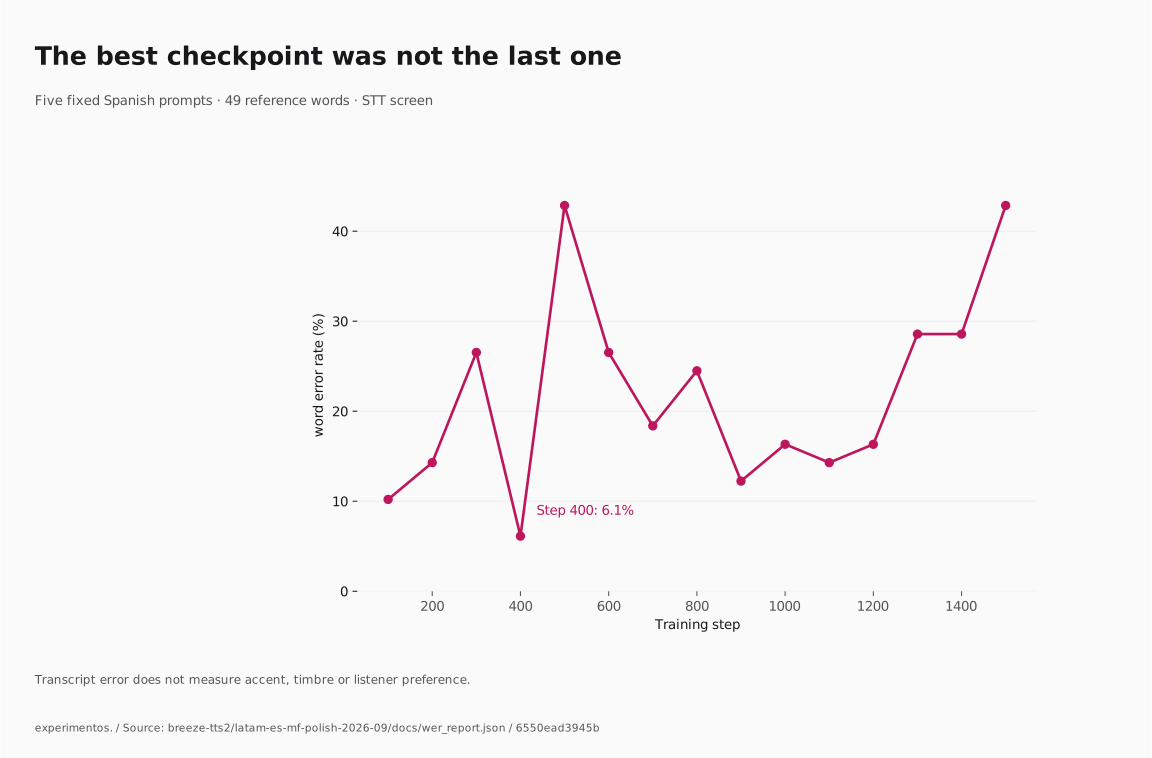
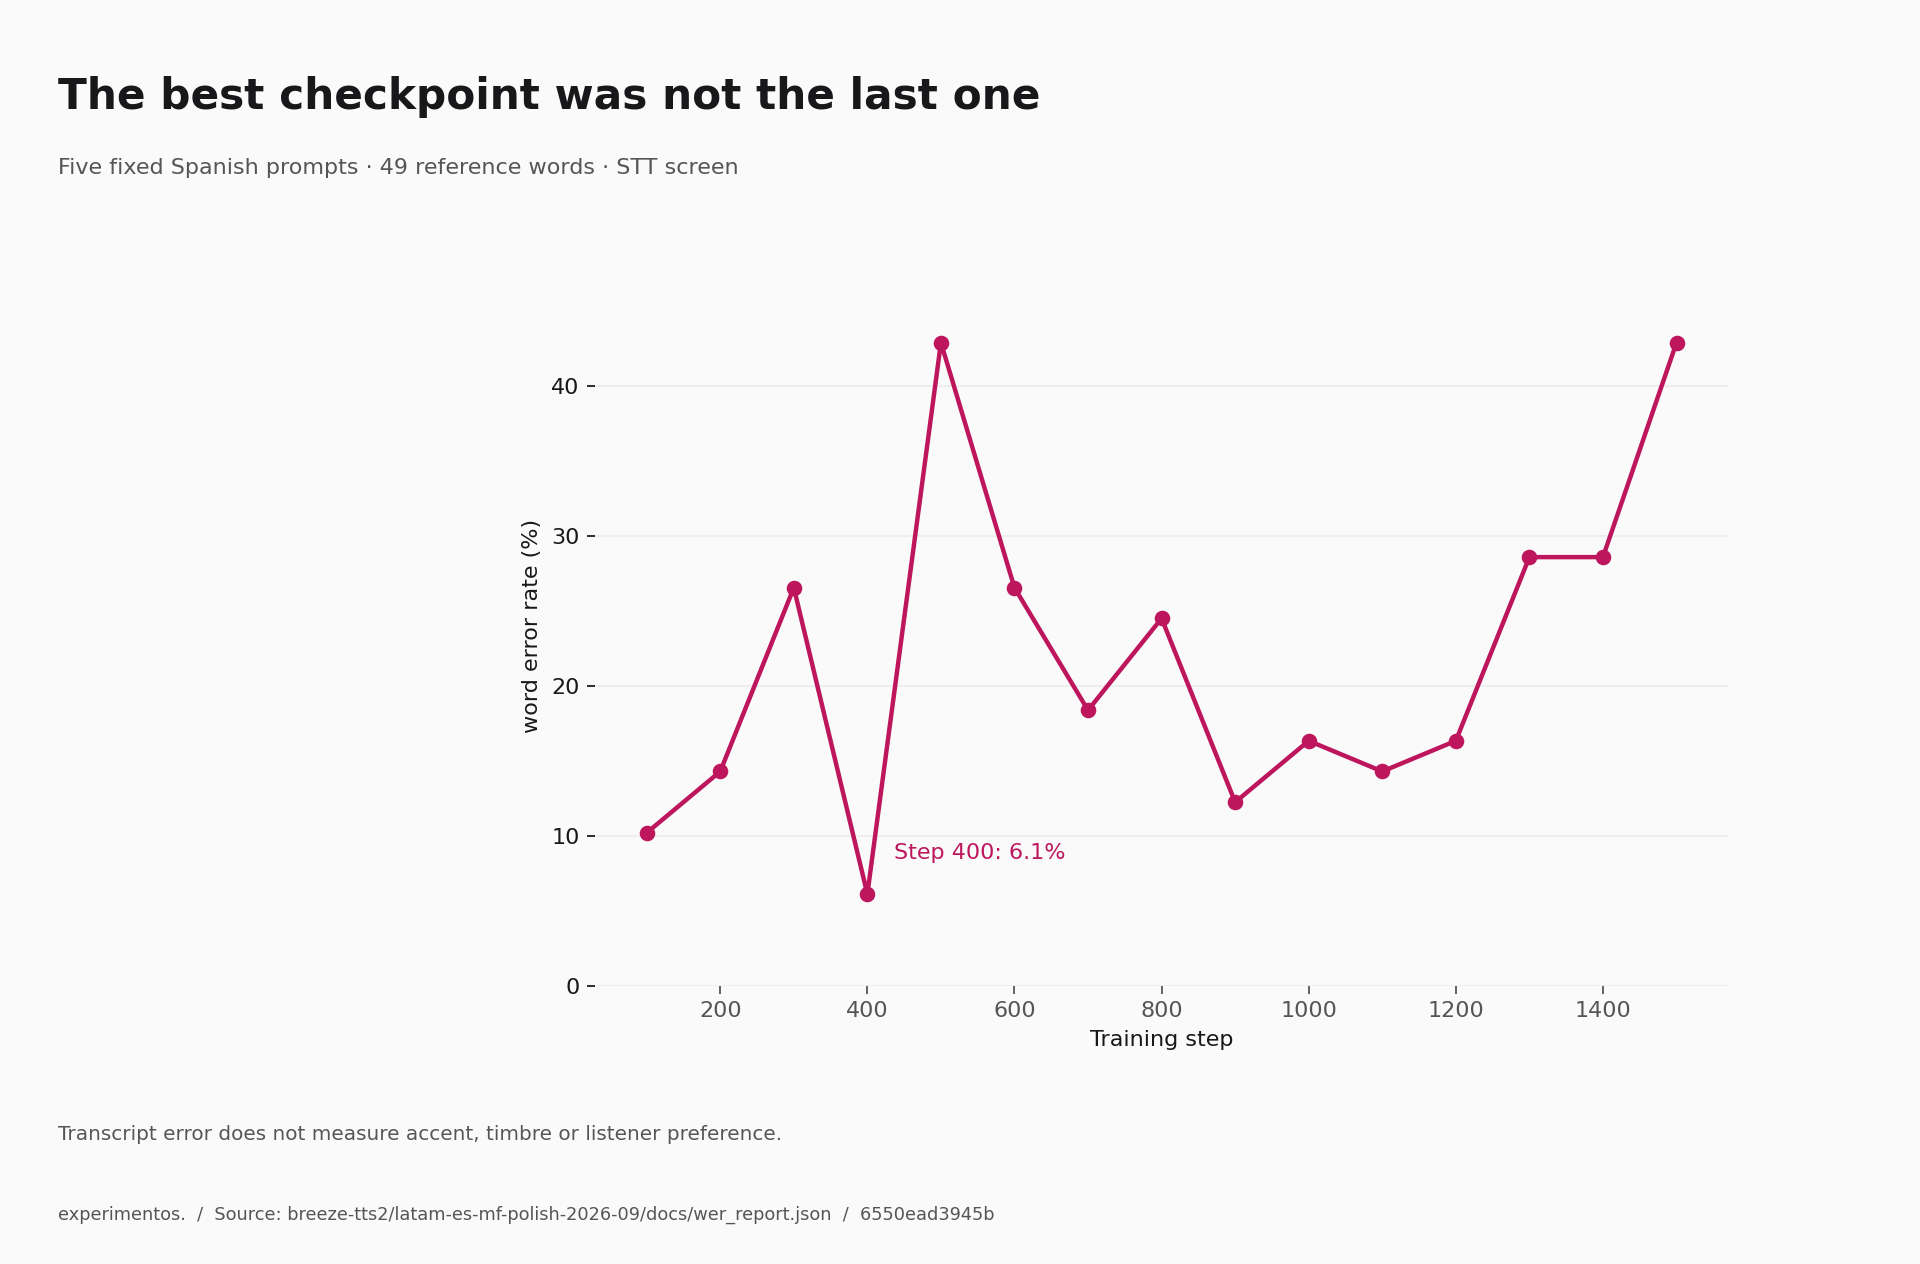
| The best checkpoint was not the last one | Speech & codecs | Polish step 400 measured 6.1% word error rate; the final step 1500 measured 42.9%. | |
| Rebuilding calibration for an agentic quant | Language models | The clean agentic importance matrix recovered the hard T3 task; later draft decoding improved measured throughput. | |
| A draft head, a rollback fix, and a midnight incident | Language models | The rollback fix brought draft decoding to parity at temperature 0.7 and a 24% gain at greedy sampling. | |
| Making room for a 200K context | Language models | The warm proxy decode median was 59.17 tokens per second; a 198,960-token request passed with GPU headroom. | |
| DFlash2 on a single RTX 3090 | Language models | Ornith measured 210.16 tokens per second on the realistic 256-token prompt and 270.40 on predictable prose. | |
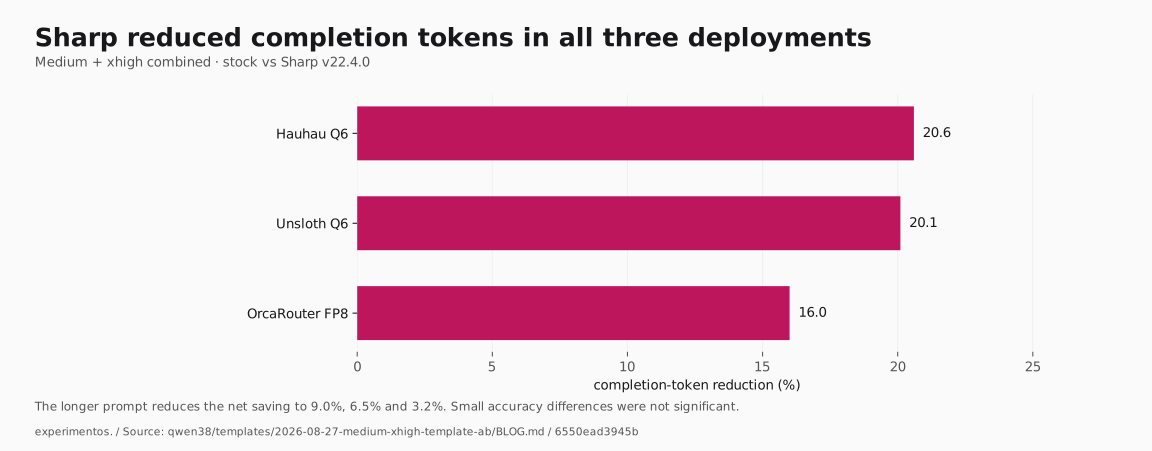
| Less thinking, fewer tokens: a template A/B | Language models | Sharp reduced completion tokens by 20.6%, 20.1% and 16.0% across the three deployments. | |
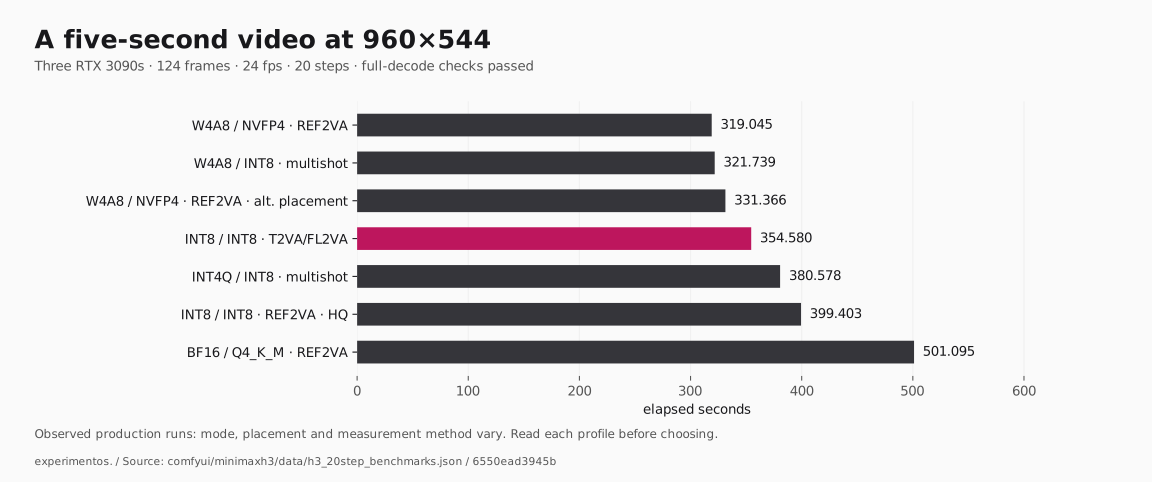
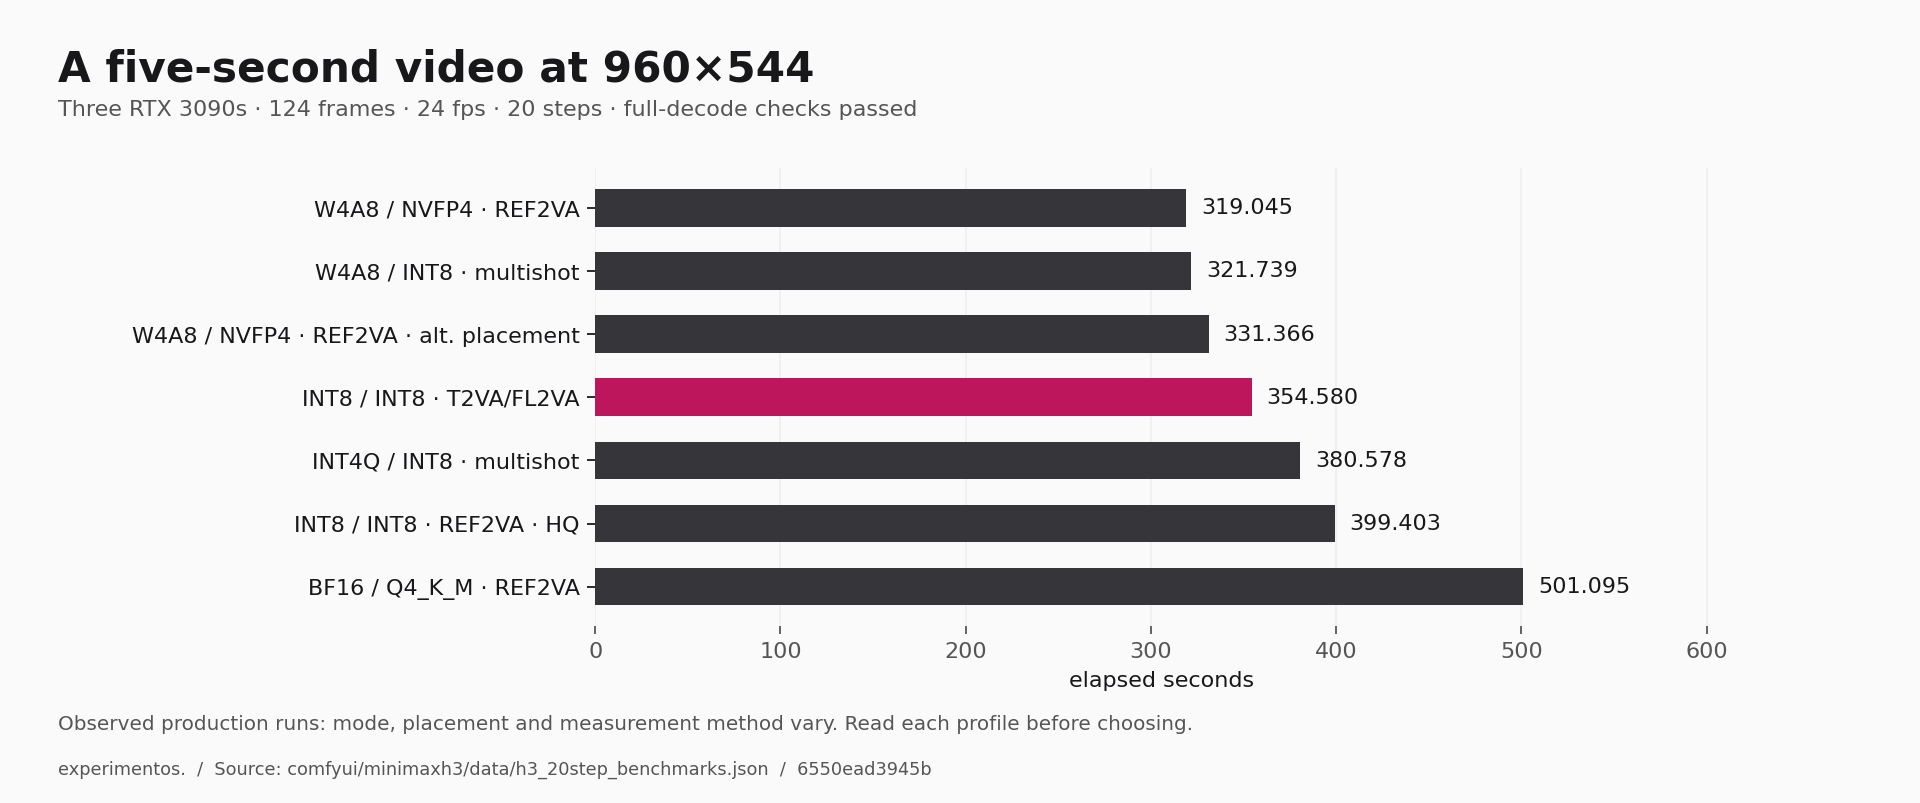
| The real cost of a five-second video | Images & video | RTX 3090 | At 960×544, dual INT8 completed a 124-frame, 20-step run in 354.580 seconds. |
Agents & systems
A coding agent that knows when to ask for help · 1 Oct 2026 · RTX 3090
What recovery cost in three live scenarios
Single RTX 3090 · local Qwen worker + GLM reviewer · each scenario finished 10/10 checks
- Repeated failures · 2 reviews150
- Acceptance failure · 1 review142
- Successful task · no review9
seconds
Deliberately triggered integration scenarios; duration does not measure general coding accuracy.
View data & source
| Configuration | Value |
|---|---|
| Repeated failures · 2 reviews | 150 |
| Acceptance failure · 1 review | 142 |
| Successful task · no review | 9 |
Origin: structured measurements. Revision 6550ead3945b.
A coding agent that knows when to ask for help · 1 Oct 2026 · RTX 3090
A compact handoff can still add information
Serialized context at the recovery handoff
- Repeated failures · before14,325
- Repeated failures · after5,723
- Acceptance failure · before5,290
- Acceptance failure · after6,566
characters
The short acceptance request grew after adding diagnostic information; this is not a universal compression ratio.
View data & source
| Configuration | Value |
|---|---|
| Repeated failures · before | 14,325 |
| Repeated failures · after | 5,723 |
| Acceptance failure · before | 5,290 |
| Acceptance failure · after | 6,566 |
Origin: structured measurements. Revision 6550ead3945b.
144 recoveries, one carefully bounded task · 7 Oct 2026
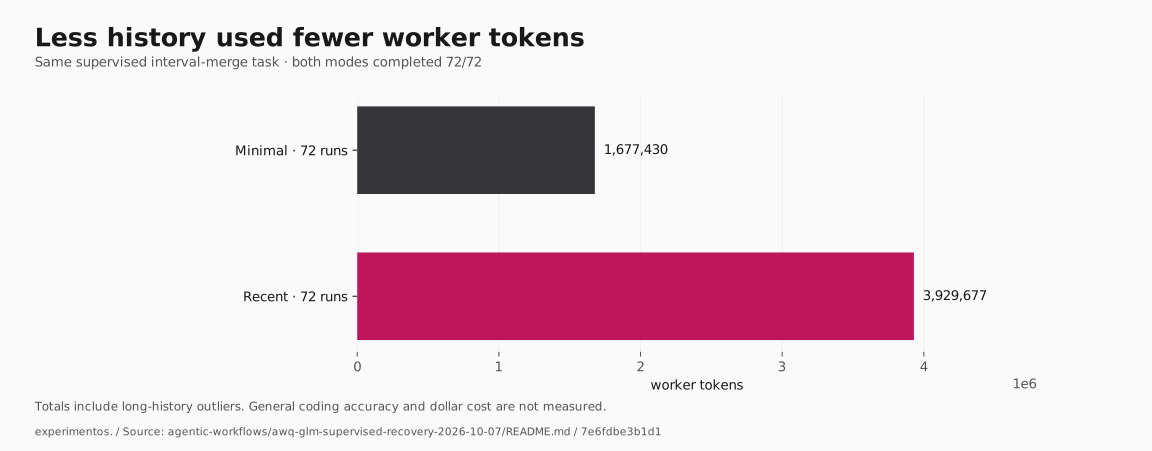
Less history used fewer worker tokens
Same supervised interval-merge task · both modes completed 72/72
- Minimal · 72 runs1,677,430
- Recent · 72 runs3,929,677
worker tokens
Totals include long-history outliers. General coding accuracy and dollar cost are not measured.
View data & source
| Configuration | Value |
|---|---|
| Minimal · 72 runs | 1,677,430 |
| Recent · 72 runs | 3,929,677 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
Game learning
A second dish, a new frozen test · 29 Sept 2026
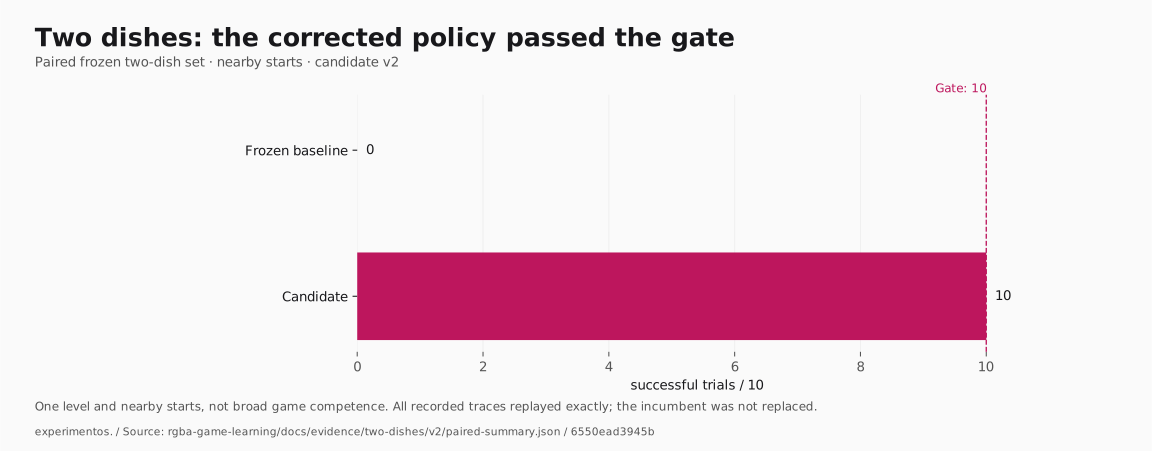
Two dishes: the corrected policy passed the gate
Paired frozen two-dish set · nearby starts · candidate v2
- Frozen baseline0
- Candidate10
successful trials / 10 · gate: 10
One level and nearby starts, not broad game competence. All recorded traces replayed exactly; the incumbent was not replaced.
View data & source
| Configuration | Value |
|---|---|
| Frozen baseline | 0 |
| Candidate | 10 |
Origin: structured measurements. Revision 6550ead3945b.
Eight clears are still not a promotion · 29 Sept 2026
Eight clears still failed the strict gate
Mac v3 protocol · paired frozen full-kitchen set
- Frozen baseline0
- Candidate8
successful trials / 10 · gate: 10
One level and nearby starts, not broad game competence. V3 and v4 are separate protocols.
View data & source
| Configuration | Value |
|---|---|
| Frozen baseline | 0 |
| Candidate | 8 |
Origin: structured measurements. Revision 6550ead3945b.
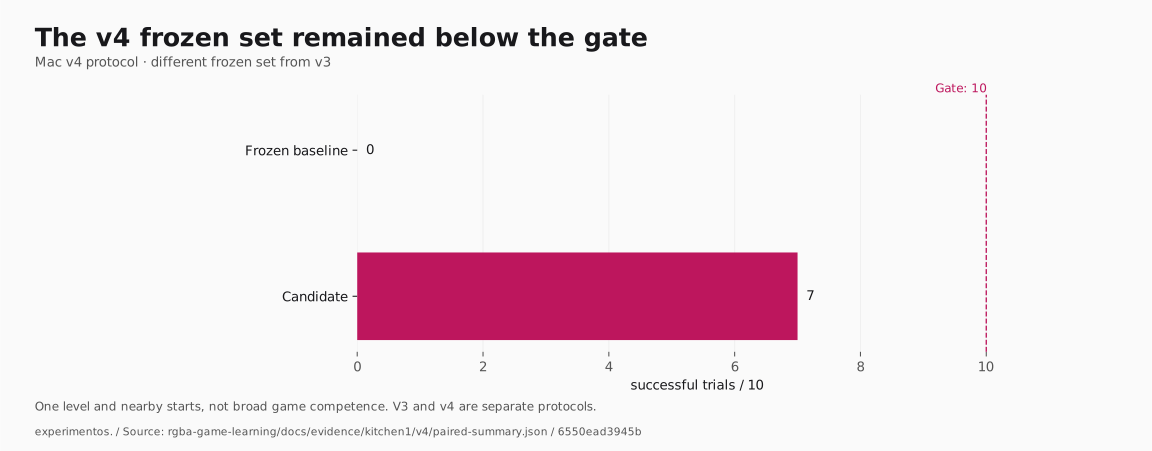
Eight clears are still not a promotion · 29 Sept 2026
The v4 frozen set remained below the gate
Mac v4 protocol · different frozen set from v3
- Frozen baseline0
- Candidate7
successful trials / 10 · gate: 10
One level and nearby starts, not broad game competence. V3 and v4 are separate protocols.
View data & source
| Configuration | Value |
|---|---|
| Frozen baseline | 0 |
| Candidate | 7 |
Origin: structured measurements. Revision 6550ead3945b.
Corrective data meets a fresh gameplay gate · 30 Sept 2026
Corrective data vs a same-host retraining control
Ubuntu CPU · initial paired full-kitchen evaluation
- Retraining control7
- Candidate10
successful trials / 10 · gate: 10
One level and nearby starts, not broad game competence. All recorded traces replayed exactly; the incumbent was not replaced.
View data & source
| Configuration | Value |
|---|---|
| Retraining control | 7 |
| Candidate | 10 |
Origin: structured measurements. Revision 6550ead3945b.
Corrective data meets a fresh gameplay gate · 30 Sept 2026
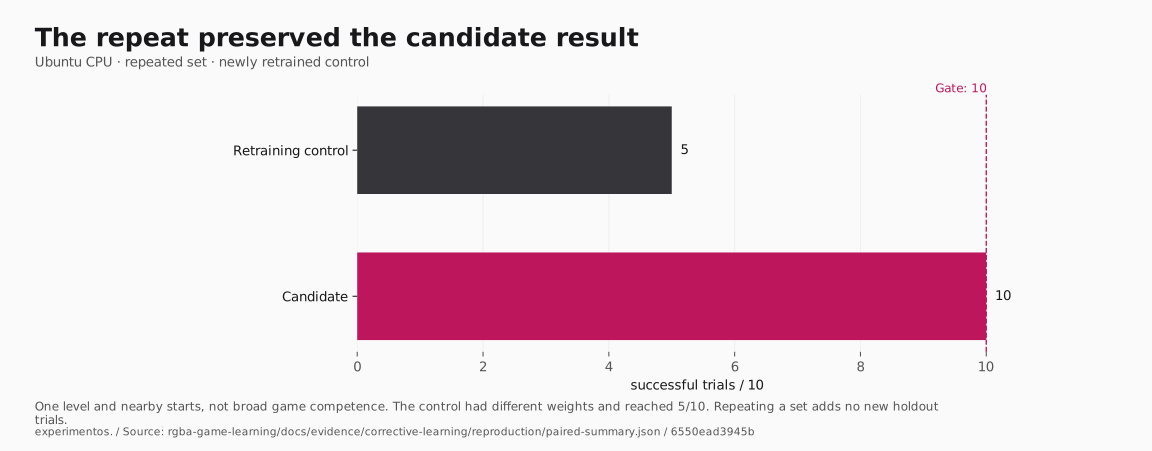
The repeat preserved the candidate result
Ubuntu CPU · repeated set · newly retrained control
- Retraining control5
- Candidate10
successful trials / 10 · gate: 10
One level and nearby starts, not broad game competence. The control had different weights and reached 5/10. Repeating a set adds no new holdout trials.
View data & source
| Configuration | Value |
|---|---|
| Retraining control | 5 |
| Candidate | 10 |
Origin: structured measurements. Revision 6550ead3945b.
Images & video
A complete image stack on one 24GB GPU · 21 Sept 2026 · RTX 3090
Matched scenes, different diffusion precision
1024×1024 · 40 steps · matched seeds 2401–2408 · warm RTX 3090 runs
- FP8 · mean of 8 scenes93.352
- INT8 · mean of 8 scenes46.219
seconds
INT8 was opt-in. Fine detail changed, so timing improvement is not visual-quality parity.
View data & source
| Configuration | Value |
|---|---|
| FP8 · mean of 8 scenes | 93.352 |
| INT8 · mean of 8 scenes | 46.219 |
Origin: structured measurements. Revision 6550ead3945b.
- qwen21-te-awq/samples/quality-suite-20260924/fp8/results.json
- qwen21-te-awq/samples/quality-suite-20260924/int8/results.json
A complete image stack on one 24GB GPU · 21 Sept 2026 · RTX 3090
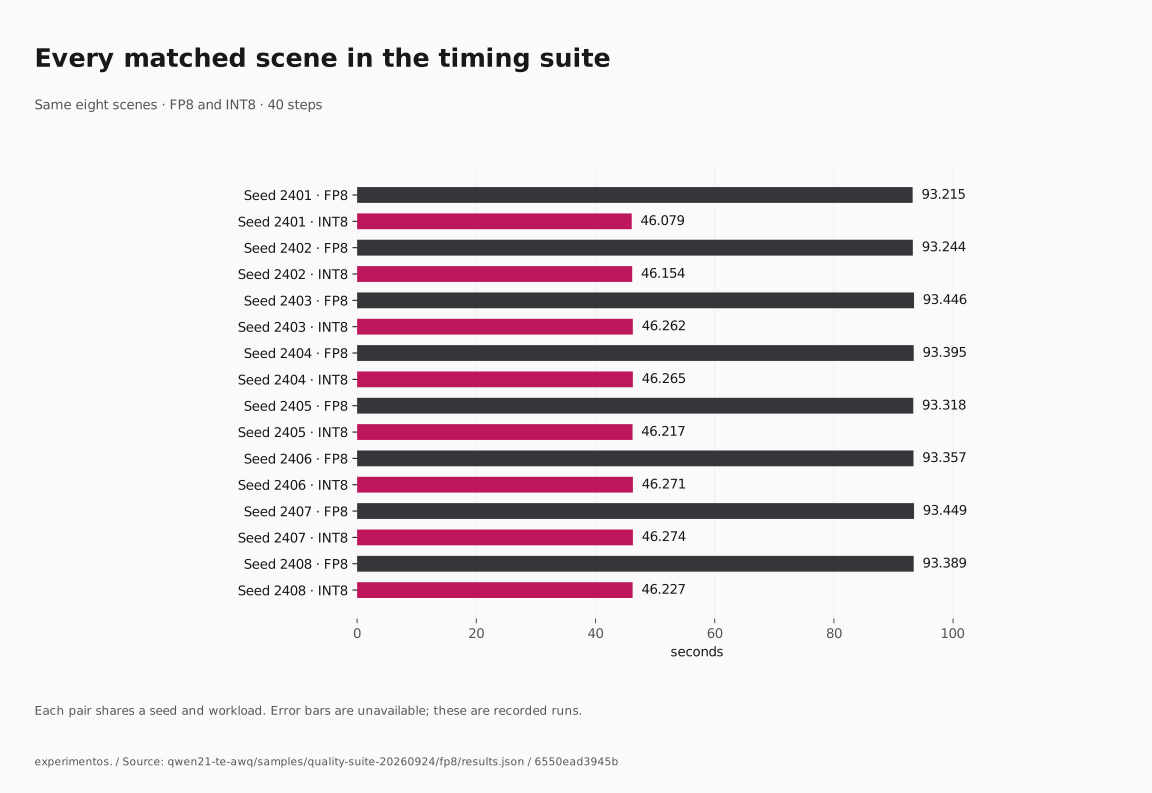
Every matched scene in the timing suite
Same eight scenes · FP8 and INT8 · 40 steps
- Seed 2401 · FP893.215
- Seed 2401 · INT846.079
- Seed 2402 · FP893.244
- Seed 2402 · INT846.154
- Seed 2403 · FP893.446
- Seed 2403 · INT846.262
- Seed 2404 · FP893.395
- Seed 2404 · INT846.265
- Seed 2405 · FP893.318
- Seed 2405 · INT846.217
- Seed 2406 · FP893.357
- Seed 2406 · INT846.271
- Seed 2407 · FP893.449
- Seed 2407 · INT846.274
- Seed 2408 · FP893.389
- Seed 2408 · INT846.227
seconds
Each pair shares a seed and workload. Error bars are unavailable; these are recorded runs.
View data & source
| Configuration | Value |
|---|---|
| Seed 2401 · FP8 | 93.215 |
| Seed 2401 · INT8 | 46.079 |
| Seed 2402 · FP8 | 93.244 |
| Seed 2402 · INT8 | 46.154 |
| Seed 2403 · FP8 | 93.446 |
| Seed 2403 · INT8 | 46.262 |
| Seed 2404 · FP8 | 93.395 |
| Seed 2404 · INT8 | 46.265 |
| Seed 2405 · FP8 | 93.318 |
| Seed 2405 · INT8 | 46.217 |
| Seed 2406 · FP8 | 93.357 |
| Seed 2406 · INT8 | 46.271 |
| Seed 2407 · FP8 | 93.449 |
| Seed 2407 · INT8 | 46.274 |
| Seed 2408 · FP8 | 93.389 |
| Seed 2408 · INT8 | 46.227 |
Origin: structured measurements. Revision 6550ead3945b.
- qwen21-te-awq/samples/quality-suite-20260924/fp8/results.json
- qwen21-te-awq/samples/quality-suite-20260924/int8/results.json
The real cost of a five-second video · 27 Aug 2026 · RTX 3090
A five-second video at 960×544
Three RTX 3090s · 124 frames · 24 fps · 20 steps · full-decode checks passed
- W4A8 / NVFP4 · REF2VA319.045
- W4A8 / INT8 · multishot321.739
- W4A8 / NVFP4 · REF2VA · alt. placement331.366
- INT8 / INT8 · T2VA/FL2VA354.580
- INT4Q / INT8 · multishot380.578
- INT8 / INT8 · REF2VA · HQ399.403
- BF16 / Q4_K_M · REF2VA501.095
elapsed seconds
Observed production runs: mode, placement and measurement method vary. Read each profile before choosing.
View data & source
| Configuration | Value |
|---|---|
| W4A8 / NVFP4 · REF2VA | 319.045 |
| W4A8 / INT8 · multishot | 321.739 |
| W4A8 / NVFP4 · REF2VA · alt. placement | 331.366 |
| INT8 / INT8 · T2VA/FL2VA | 354.580 |
| INT4Q / INT8 · multishot | 380.578 |
| INT8 / INT8 · REF2VA · HQ | 399.403 |
| BF16 / Q4_K_M · REF2VA | 501.095 |
Origin: structured measurements. Revision 6550ead3945b.
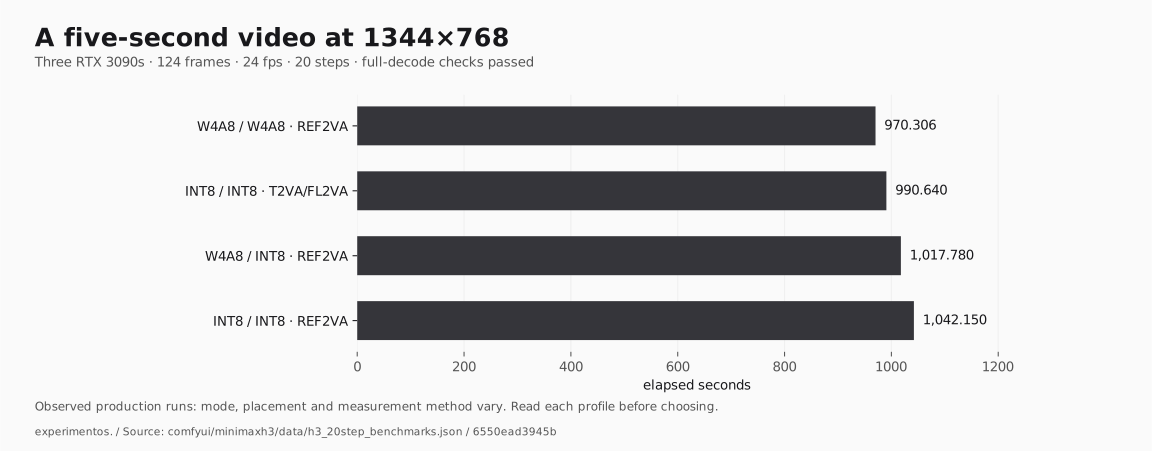
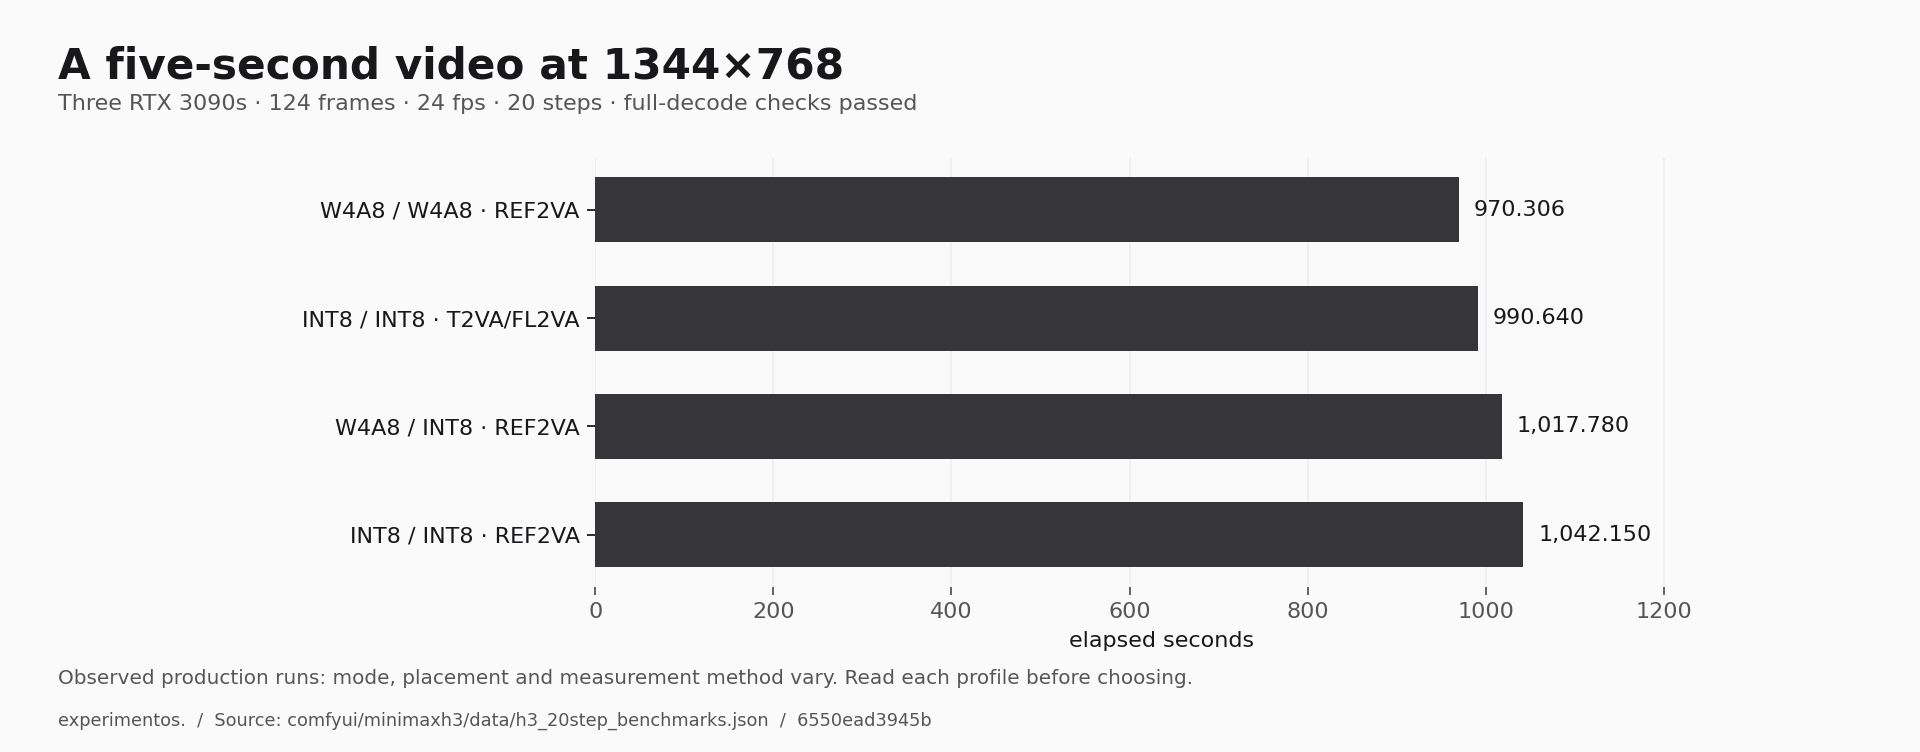
The real cost of a five-second video · 27 Aug 2026 · RTX 3090
A five-second video at 1344×768
Three RTX 3090s · 124 frames · 24 fps · 20 steps · full-decode checks passed
- W4A8 / W4A8 · REF2VA970.306
- INT8 / INT8 · T2VA/FL2VA990.640
- W4A8 / INT8 · REF2VA1,017.780
- INT8 / INT8 · REF2VA1,042.150
elapsed seconds
Observed production runs: mode, placement and measurement method vary. Read each profile before choosing.
View data & source
| Configuration | Value |
|---|---|
| W4A8 / W4A8 · REF2VA | 970.306 |
| INT8 / INT8 · T2VA/FL2VA | 990.640 |
| W4A8 / INT8 · REF2VA | 1,017.780 |
| INT8 / INT8 · REF2VA | 1,042.150 |
Origin: structured measurements. Revision 6550ead3945b.
Language models
Do you really need the bigger embedding model? · 18 Sept 2026
The smaller encoder moved more documents
275 documents · batch size 32 · AWQ W4A16
- 1B · native 2048d1,003.8
- 8B · native 4096d181.0
documents / second
Amortized throughput on this corpus, not single-query latency.
View data & source
| Configuration | Value |
|---|---|
| 1B · native 2048d | 1,003.8 |
| 8B · native 4096d | 181.0 |
Origin: structured measurements. Revision 6550ead3945b.
Do you really need the bigger embedding model? · 18 Sept 2026
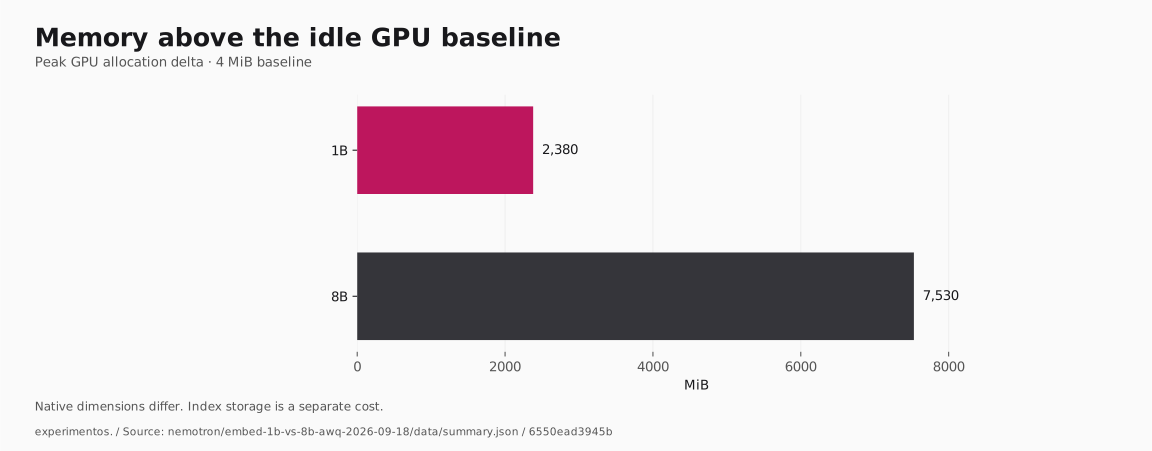
Memory above the idle GPU baseline
Peak GPU allocation delta · 4 MiB baseline
- 1B2,380
- 8B7,530
MiB
Native dimensions differ. Index storage is a separate cost.
View data & source
| Configuration | Value |
|---|---|
| 1B | 2,380 |
| 8B | 7,530 |
Origin: structured measurements. Revision 6550ead3945b.
Do you really need the bigger embedding model? · 18 Sept 2026
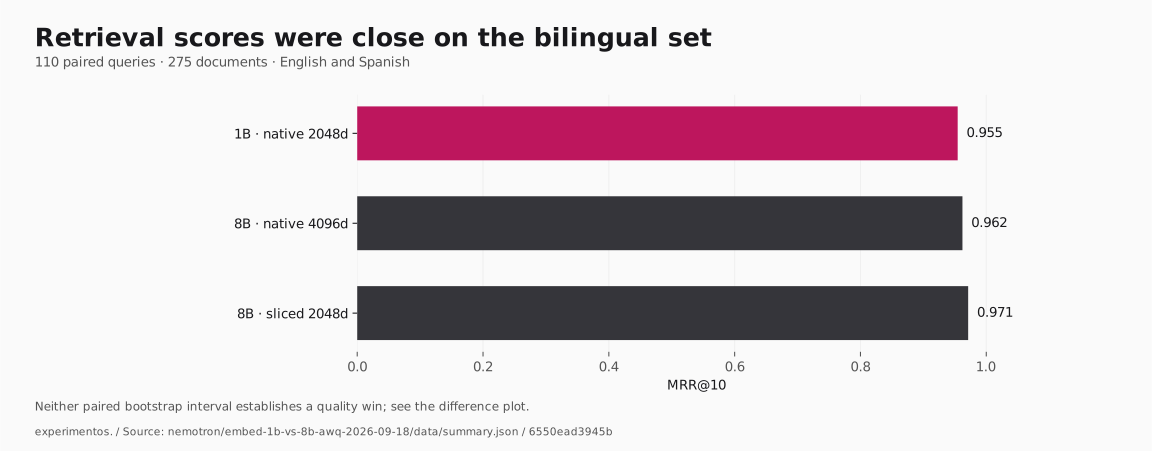
Retrieval scores were close on the bilingual set
110 paired queries · 275 documents · English and Spanish
- 1B · native 2048d0.955
- 8B · native 4096d0.962
- 8B · sliced 2048d0.971
MRR@10
Neither paired bootstrap interval establishes a quality win; see the difference plot.
View data & source
| Configuration | Value |
|---|---|
| 1B · native 2048d | 0.955 |
| 8B · native 4096d | 0.962 |
| 8B · sliced 2048d | 0.971 |
Origin: structured measurements. Revision 6550ead3945b.
Do you really need the bigger embedding model? · 18 Sept 2026
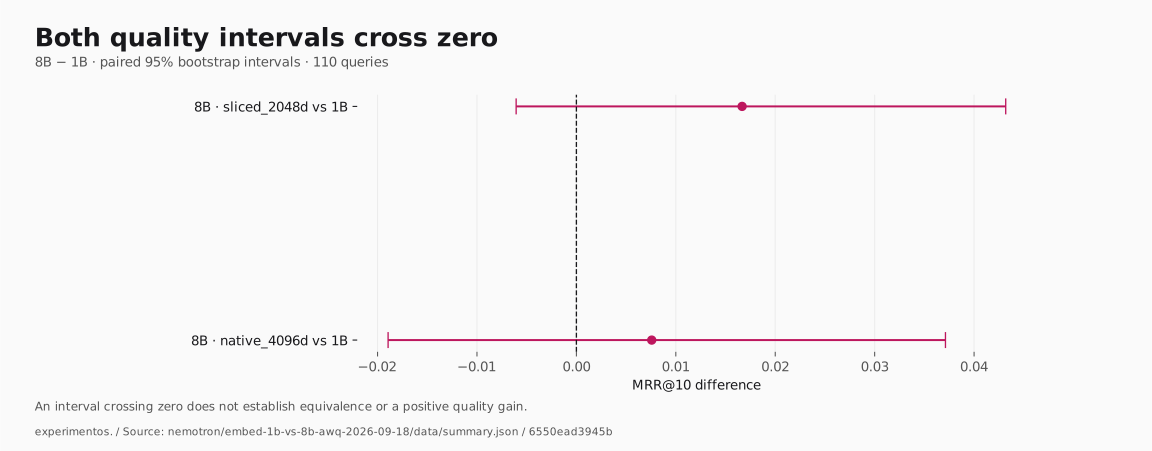
Both quality intervals cross zero
8B − 1B · paired 95% bootstrap intervals · 110 queries
- 8B · sliced_2048d vs 1B0.0167
95% interval: -0.0061 to 0.0432 · zero marked
- 8B · native_4096d vs 1B0.0076
95% interval: -0.0189 to 0.0371 · zero marked
An interval crossing zero does not establish equivalence or a positive quality gain.
View data & source
| Configuration | Value | 95% low | 95% high |
|---|---|---|---|
| 8B · sliced_2048d vs 1B | 0.0167 | -0.0061 | 0.0432 |
| 8B · native_4096d vs 1B | 0.0076 | -0.0189 | 0.0371 |
Origin: structured measurements. Revision 6550ead3945b.
Three draft tokens hit the sweet spot · 16 Sept 2026 · RTX 3090
Three draft tokens hit the sweet spot
Short-prose mean · EXL3 · Q8 cache · three RTX 3090s
- Drafting off64.7
- 2 draft tokens84.4
- 3 draft tokens88.2
- 4 draft tokens80.7
- 6 draft tokens62.4
tokens / second
The separate longer prompt and concurrent streams are different workloads.
View data & source
| Configuration | Value |
|---|---|
| Drafting off | 64.7 |
| 2 draft tokens | 84.4 |
| 3 draft tokens | 88.2 |
| 4 draft tokens | 80.7 |
| 6 draft tokens | 62.4 |
Origin: structured measurements. Revision 6550ead3945b.
Balancing GPU experts when the model will not fit · 20 Sept 2026 · RTX 3090
Balancing the expert split improved decode
GPU expert blocks · 204,800 context · Q8 KV · 300 generated tokens · three RTX 3090s
- 8 / 8 / 818.9
- 10 / 10 / 1022.1
- 11 / 11 / 1126.1
- 12 / 12 / 1231.1
- 12 / 13 / 1230.9
tokens / second
Values transcribed from the report table; cross-runtime comparison uses a different quant.
View data & source
| Configuration | Value |
|---|---|
| 8 / 8 / 8 | 18.9 |
| 10 / 10 / 10 | 22.1 |
| 11 / 11 / 11 | 26.1 |
| 12 / 12 / 12 | 31.1 |
| 12 / 13 / 12 | 30.9 |
Origin: reported table. Revision 6550ead3945b.
Finding a local model for the inbox · 27 Sept 2026
Thinking-on inbox performance across configurations
Same 50 inbox tasks · fixed sampling · different hardware, quantizations and runtimes
- A Swift-1.5 27B IQ3_S (Win)94
- B Bonsai-2-27B-Abl PQ2_0 (RTX 3060)94
- C Qwen3.8-27B GSQ-RCO IQ3_S (Win)90
- D Gemma4-12B Q4_K_M+MTP (RTX 3060)76
- E Xing4.0-29B-A4B IQ3_XXS (RTX 3060)32
- F MiMo-9B MLX 4bit (Mac)52
- F MiMo-9B MLX 4bit (Mac)64
- G Hermes-4-14B-OBL EXL3 4.0 (RTX 3060)10
- H Bonsai-2-27B MLX 2bit (Mac)94
- I Bonsai-2-27B-Abl PQ2_0 (Mac)90
- J54 Bonsai-2-27B PQ2_0+MTP (RTX 3060)96
- JMac Bonsai-2-27B PQ2_0+MTP (Mac)96
- L ThinkingCap-Qwen3.8-27B IQ3_S (Mac)92
- M ZDTaichu5.0-9B MLX 8bit (Mac, text-only)82
- K54 Bonsai-2 PQ2_0+DFlash2 (3060, CPU draft)96
- KMac Bonsai-2 PQ2_0+DFlash2 (Mac)98
- NMac HauhauCS Qwen3.8-27B IQ3_XS+MTP (Mac)86
strict pass (%)
One observed workload. Each label retains the hardware; forced thinking is a distinct mode.
View data & source
| Configuration | Value |
|---|---|
| A Swift-1.5 27B IQ3_S (Win) | 94 |
| B Bonsai-2-27B-Abl PQ2_0 (RTX 3060) | 94 |
| C Qwen3.8-27B GSQ-RCO IQ3_S (Win) | 90 |
| D Gemma4-12B Q4_K_M+MTP (RTX 3060) | 76 |
| E Xing4.0-29B-A4B IQ3_XXS (RTX 3060) | 32 |
| F MiMo-9B MLX 4bit (Mac) | 52 |
| F MiMo-9B MLX 4bit (Mac) | 64 |
| G Hermes-4-14B-OBL EXL3 4.0 (RTX 3060) | 10 |
| H Bonsai-2-27B MLX 2bit (Mac) | 94 |
| I Bonsai-2-27B-Abl PQ2_0 (Mac) | 90 |
| J54 Bonsai-2-27B PQ2_0+MTP (RTX 3060) | 96 |
| JMac Bonsai-2-27B PQ2_0+MTP (Mac) | 96 |
| L ThinkingCap-Qwen3.8-27B IQ3_S (Mac) | 92 |
| M ZDTaichu5.0-9B MLX 8bit (Mac, text-only) | 82 |
| K54 Bonsai-2 PQ2_0+DFlash2 (3060, CPU draft) | 96 |
| KMac Bonsai-2 PQ2_0+DFlash2 (Mac) | 98 |
| NMac HauhauCS Qwen3.8-27B IQ3_XS+MTP (Mac) | 86 |
Origin: reported aggregate table. Revision 6550ead3945b.
Finding a local model for the inbox · 27 Sept 2026
The cost of the same inbox workload
Thinking-on and forced-thinking rows · same 50 tasks
- A Swift-1.5 27B IQ3_S (Win)51.2
- B Bonsai-2-27B-Abl PQ2_0 (RTX 3060)26.6
- C Qwen3.8-27B GSQ-RCO IQ3_S (Win)59.9
- D Gemma4-12B Q4_K_M+MTP (RTX 3060)8.0
- E Xing4.0-29B-A4B IQ3_XXS (RTX 3060)69.0
- F MiMo-9B MLX 4bit (Mac)6.7
- F MiMo-9B MLX 4bit (Mac)17.4
- G Hermes-4-14B-OBL EXL3 4.0 (RTX 3060)94.4
- H Bonsai-2-27B MLX 2bit (Mac)87.0
- I Bonsai-2-27B-Abl PQ2_0 (Mac)81.7
- J54 Bonsai-2-27B PQ2_0+MTP (RTX 3060)15.8
- JMac Bonsai-2-27B PQ2_0+MTP (Mac)67.1
- L ThinkingCap-Qwen3.8-27B IQ3_S (Mac)81.9
- M ZDTaichu5.0-9B MLX 8bit (Mac, text-only)65.0
- K54 Bonsai-2 PQ2_0+DFlash2 (3060, CPU draft)52.0
- KMac Bonsai-2 PQ2_0+DFlash2 (Mac)71.6
- NMac HauhauCS Qwen3.8-27B IQ3_XS+MTP (Mac)135.5
median seconds / task
Median client wall time. A higher pass rate does not automatically give a faster workflow.
View data & source
| Configuration | Value |
|---|---|
| A Swift-1.5 27B IQ3_S (Win) | 51.2 |
| B Bonsai-2-27B-Abl PQ2_0 (RTX 3060) | 26.6 |
| C Qwen3.8-27B GSQ-RCO IQ3_S (Win) | 59.9 |
| D Gemma4-12B Q4_K_M+MTP (RTX 3060) | 8.0 |
| E Xing4.0-29B-A4B IQ3_XXS (RTX 3060) | 69.0 |
| F MiMo-9B MLX 4bit (Mac) | 6.7 |
| F MiMo-9B MLX 4bit (Mac) | 17.4 |
| G Hermes-4-14B-OBL EXL3 4.0 (RTX 3060) | 94.4 |
| H Bonsai-2-27B MLX 2bit (Mac) | 87.0 |
| I Bonsai-2-27B-Abl PQ2_0 (Mac) | 81.7 |
| J54 Bonsai-2-27B PQ2_0+MTP (RTX 3060) | 15.8 |
| JMac Bonsai-2-27B PQ2_0+MTP (Mac) | 67.1 |
| L ThinkingCap-Qwen3.8-27B IQ3_S (Mac) | 81.9 |
| M ZDTaichu5.0-9B MLX 8bit (Mac, text-only) | 65.0 |
| K54 Bonsai-2 PQ2_0+DFlash2 (3060, CPU draft) | 52.0 |
| KMac Bonsai-2 PQ2_0+DFlash2 (Mac) | 71.6 |
| NMac HauhauCS Qwen3.8-27B IQ3_XS+MTP (Mac) | 135.5 |
Origin: reported aggregate table. Revision 6550ead3945b.
Less thinking, fewer tokens: a template A/B · 27 Aug 2026
Sharp reduced completion tokens in all three deployments
Medium + xhigh combined · stock vs Sharp v22.4.0
- Hauhau Q620.6
- Unsloth Q620.1
- OrcaRouter FP816.0
completion-token reduction (%)
The longer prompt reduces the net saving to 9.0%, 6.5% and 3.2%. Small accuracy differences were not significant.
View data & source
| Configuration | Value |
|---|---|
| Hauhau Q6 | 20.6 |
| Unsloth Q6 | 20.1 |
| OrcaRouter FP8 | 16.0 |
Origin: reported paired aggregate table. Revision 6550ead3945b.
A context setting is not a context test · 6 Oct 2026
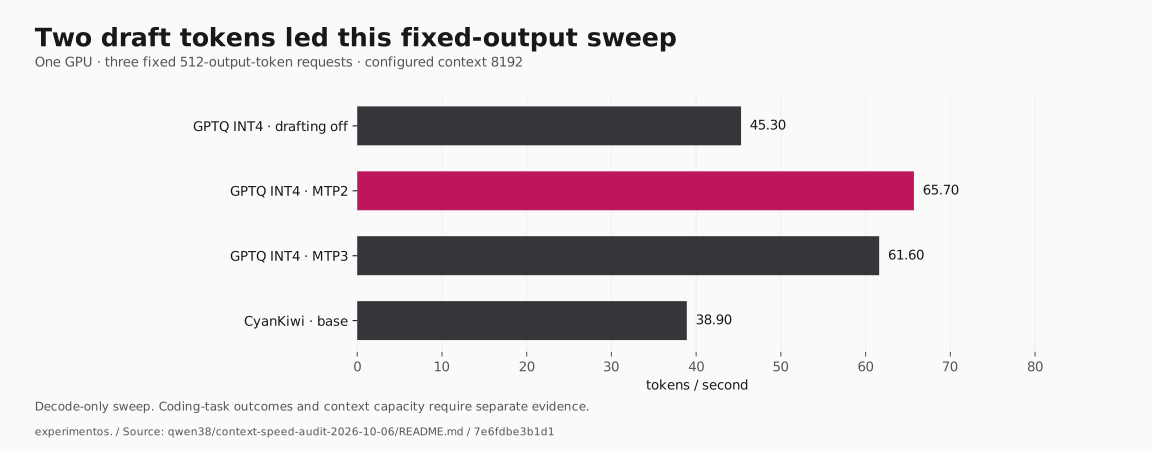
Two draft tokens led this fixed-output sweep
One GPU · three fixed 512-output-token requests · configured context 8192
- GPTQ INT4 · drafting off45.30
- GPTQ INT4 · MTP265.70
- GPTQ INT4 · MTP361.60
- CyanKiwi · base38.90
tokens / second
Decode-only sweep. Coding-task outcomes and context capacity require separate evidence.
View data & source
| Configuration | Value |
|---|---|
| GPTQ INT4 · drafting off | 45.30 |
| GPTQ INT4 · MTP2 | 65.70 |
| GPTQ INT4 · MTP3 | 61.60 |
| CyanKiwi · base | 38.90 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
An unfinished gauntlet cannot name a winner · 8 Oct 2026
The completed matched cells were tied
Incomplete campaign · 15 shared cells · six passes and nine failures each
- Qwen6
- Bonsai6
passes / 15 matched cells
Three extra Qwen passes are unpaired. Only 18 of 54 planned cells completed.
View data & source
| Configuration | Value |
|---|---|
| Qwen | 6 |
| Bonsai | 6 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
Speech & codecs
The best checkpoint was not the last one · 11 Sept 2026
The best checkpoint was not the last one
Five fixed Spanish prompts · 49 reference words · STT screen
Transcript error does not measure accent, timbre or listener preference.
View data & source
| Configuration | Value |
|---|---|
| Step 100 | 10.2 |
| Step 200 | 14.3 |
| Step 300 | 26.5 |
| Step 400 | 6.1 |
| Step 500 | 42.9 |
| Step 600 | 26.5 |
| Step 700 | 18.4 |
| Step 800 | 24.5 |
| Step 900 | 12.2 |
| Step 1000 | 16.3 |
| Step 1100 | 14.3 |
| Step 1200 | 16.3 |
| Step 1300 | 28.6 |
| Step 1400 | 28.6 |
| Step 1500 | 42.9 |
Origin: structured measurements. Revision 6550ead3945b.
Moving speech decode onto the GPU · 22 Sept 2026
GPU decode shortened the final stage
Seed-matched recorded deployment A/B · FP32 reference encoder on CPU
- CPU INT8 decode3.36
- GPU FP8 decode0.24
seconds
Report-table values. The archived before JSON is empty; these are not presented as recovered raw logs.
View data & source
| Configuration | Value |
|---|---|
| CPU INT8 decode | 3.36 |
| GPU FP8 decode | 0.24 |
Origin: reported table. Revision 6550ead3945b.
Moving speech decode onto the GPU · 22 Sept 2026
End-to-end render wall time
Seed-matched recorded deployment A/B · FP32 reference encoder on CPU
- Before35.10
- After24.40
seconds
Report-table values. The archived before JSON is empty; these are not presented as recovered raw logs.
View data & source
| Configuration | Value |
|---|---|
| Before | 35.10 |
| After | 24.40 |
Origin: reported table. Revision 6550ead3945b.
Moving speech decode onto the GPU · 22 Sept 2026
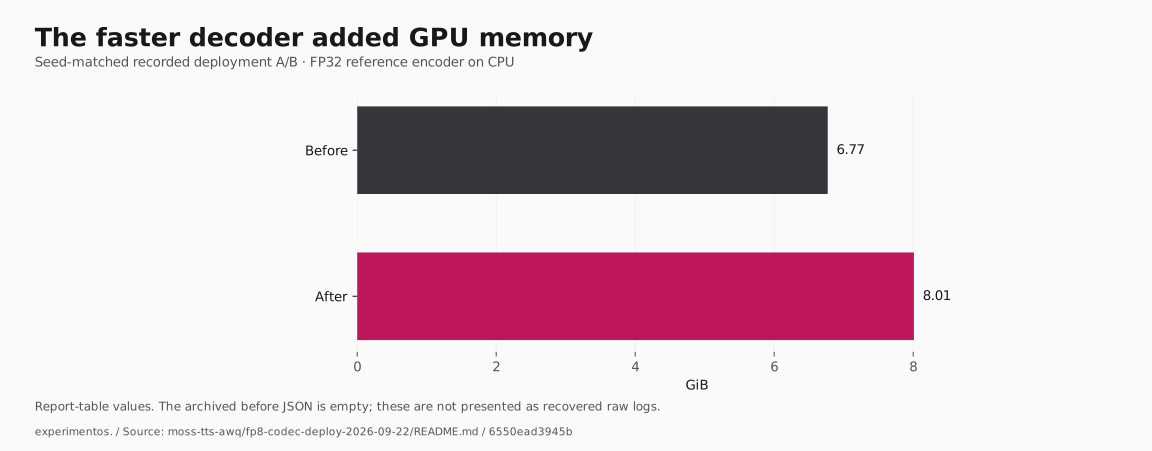
The faster decoder added GPU memory
Seed-matched recorded deployment A/B · FP32 reference encoder on CPU
- Before6.77
- After8.01
GiB
Report-table values. The archived before JSON is empty; these are not presented as recovered raw logs.
View data & source
| Configuration | Value |
|---|---|
| Before | 6.77 |
| After | 8.01 |
Origin: reported table. Revision 6550ead3945b.
The clone bug was in the reference encoder · 21 Sept 2026
Changing the reference encoder recovered similarity
AWQ generator · INT8 output decoder · named reference test
- AWQ + INT8 reference0.8475
- AWQ + FP32 reference0.9556
WavLM target similarity
A similarity proxy is not a human preference or accent verdict.
View data & source
| Configuration | Value |
|---|---|
| AWQ + INT8 reference | 0.8475 |
| AWQ + FP32 reference | 0.9556 |
Origin: reported table. Revision 6550ead3945b.
Staging the speech stack under a 12GB envelope · 18 Sept 2026 · RTX 3090
Staging moved the peak below 12 GiB
Staged-memory run on an RTX 3090
- Before staging13.01
- After staging6.63
GiB · gate: 12
A 12 GiB envelope on a 3090 does not establish physical RTX 3060 acceptance.
View data & source
| Configuration | Value |
|---|---|
| Before staging | 13.01 |
| After staging | 6.63 |
Origin: reported table. Revision 6550ead3945b.
FP32, BF16, INT8: separating codec drift from speech · 18 Sept 2026
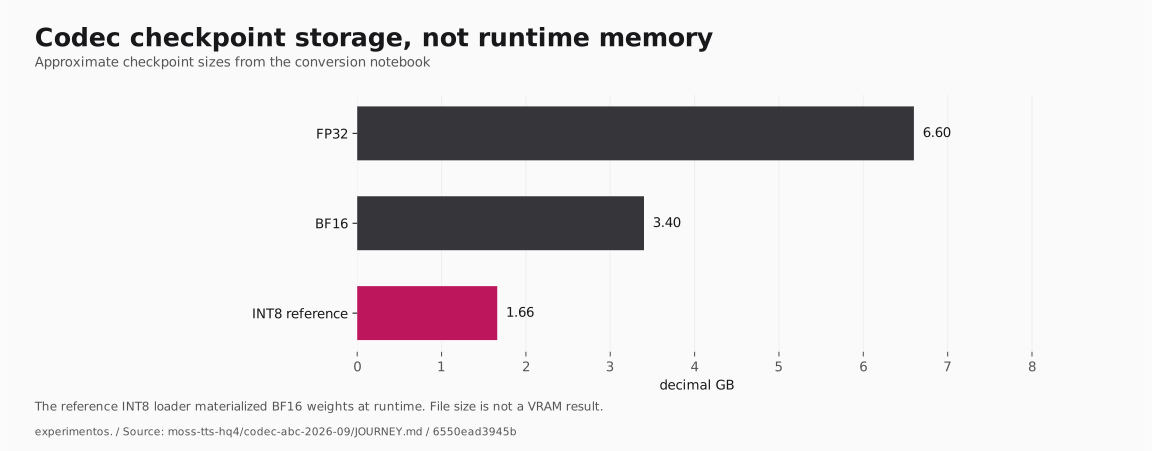
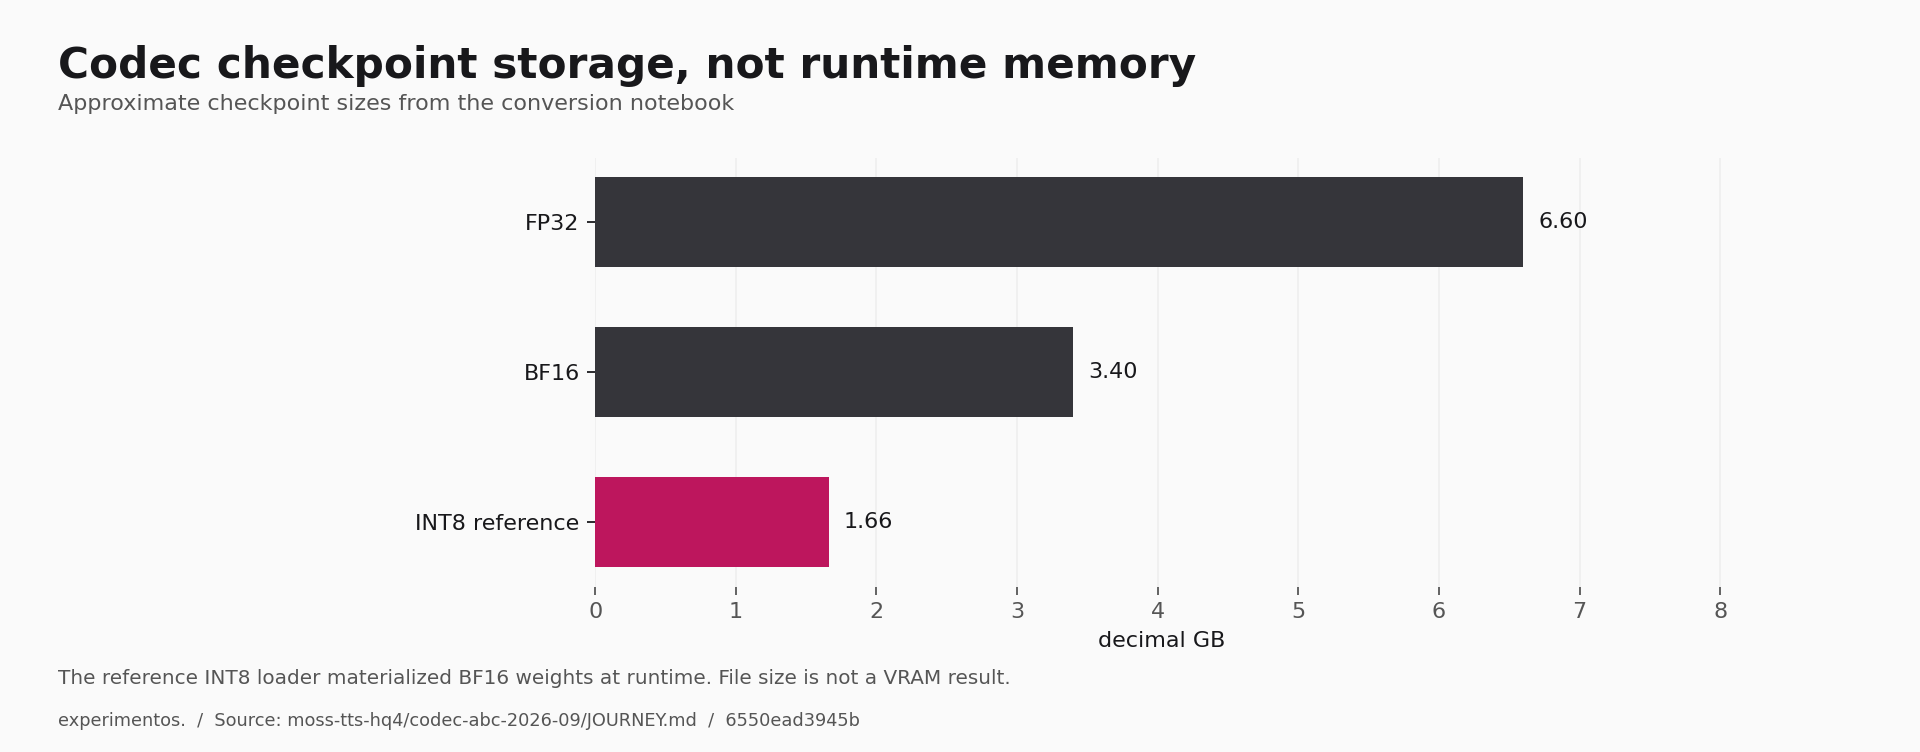
Codec checkpoint storage, not runtime memory
Approximate checkpoint sizes from the conversion notebook
- FP326.60
- BF163.40
- INT8 reference1.66
decimal GB
The reference INT8 loader materialized BF16 weights at runtime. File size is not a VRAM result.
View data & source
| Configuration | Value |
|---|---|
| FP32 | 6.60 |
| BF16 | 3.40 |
| INT8 reference | 1.66 |
Origin: reported conversion sizes. Revision 6550ead3945b.
A speech service that sleeps between requests · 19 Sept 2026
First request and warm request are different states
HQ4 + INT8 codec lazy service · recorded request timings
- Cold first render14.8
- Warm render5.7
seconds
Cold start includes service wake-up. This is not two equivalent decoding workloads.
View data & source
| Configuration | Value |
|---|---|
| Cold first render | 14.8 |
| Warm render | 5.7 |
Origin: reported live-service timings. Revision 6550ead3945b.
A smaller speech model earns its place on the iPhone · 3 Oct 2026 · iPhone 15 Pro
Fewer observed transcription errors in both languages
iPhone 15 Pro · 24 English + 24 Spanish clips · 325 + 242 reference words
- English · ONNX · 2 CPU threads3.69
- English · Aidana · MLX GPU2.15
- Spanish · ONNX · 2 CPU threads9.50
- Spanish · Aidana · MLX GPU5.37
word error rate (%)
Short public read speech, one completed pass per stack. English’s paired interval crosses zero; this does not establish all-accent or noisy-microphone accuracy.
View data & source
| Configuration | Value |
|---|---|
| English · ONNX · 2 CPU threads | 3.69 |
| English · Aidana · MLX GPU | 2.15 |
| Spanish · ONNX · 2 CPU threads | 9.50 |
| Spanish · Aidana · MLX GPU | 5.37 |
Origin: structured measurements. Revision 6550ead3945b.
A smaller speech model earns its place on the iPhone · 3 Oct 2026 · iPhone 15 Pro
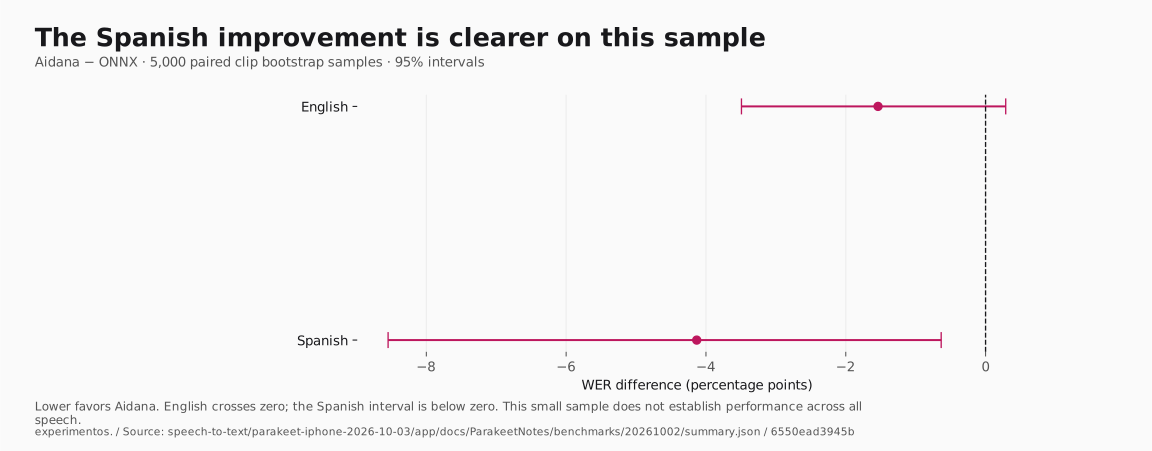
The Spanish improvement is clearer on this sample
Aidana − ONNX · 5,000 paired clip bootstrap samples · 95% intervals
- English-1.54
95% interval: -3.49 to 0.29 · zero marked
- Spanish-4.13
95% interval: -8.55 to -0.63 · zero marked
Lower favors Aidana. English crosses zero; the Spanish interval is below zero. This small sample does not establish performance across all speech.
View data & source
| Configuration | Value | 95% low | 95% high |
|---|---|---|---|
| English | -1.54 | -3.49 | 0.29 |
| Spanish | -4.13 | -8.55 | -0.63 |
Origin: structured measurements. Revision 6550ead3945b.
A smaller speech model earns its place on the iPhone · 3 Oct 2026 · iPhone 15 Pro
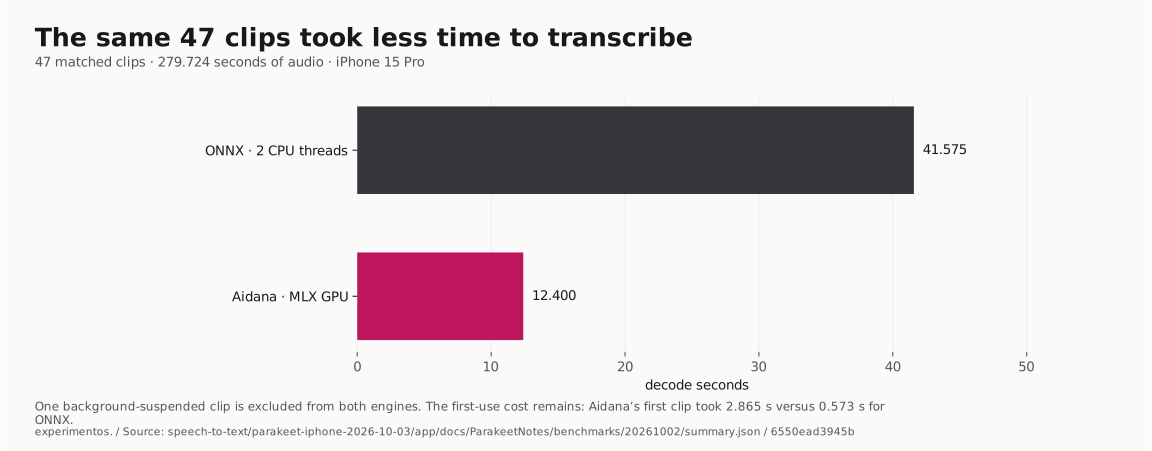
The same 47 clips took less time to transcribe
47 matched clips · 279.724 seconds of audio · iPhone 15 Pro
- ONNX · 2 CPU threads41.575
- Aidana · MLX GPU12.400
decode seconds
One background-suspended clip is excluded from both engines. The first-use cost remains: Aidana’s first clip took 2.865 s versus 0.573 s for ONNX.
View data & source
| Configuration | Value |
|---|---|
| ONNX · 2 CPU threads | 41.575 |
| Aidana · MLX GPU | 12.400 |
Origin: structured measurements. Revision 6550ead3945b.
A faster speech encoder with the same 50 transcripts · 5 Oct 2026 · RTX 3060
A faster encoder with unchanged transcripts
50 clean English clips · 304.515 s · sum of per-clip warm medians
- CUDA FP32128.80
- TRT FP16 encoder + FP32 decoder159.76
times real time
Three timing repeats per clip. Aggregate offline speed is not first-word or conversation latency.
View data & source
| Configuration | Value |
|---|---|
| CUDA FP32 | 128.80 |
| TRT FP16 encoder + FP32 decoder | 159.76 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
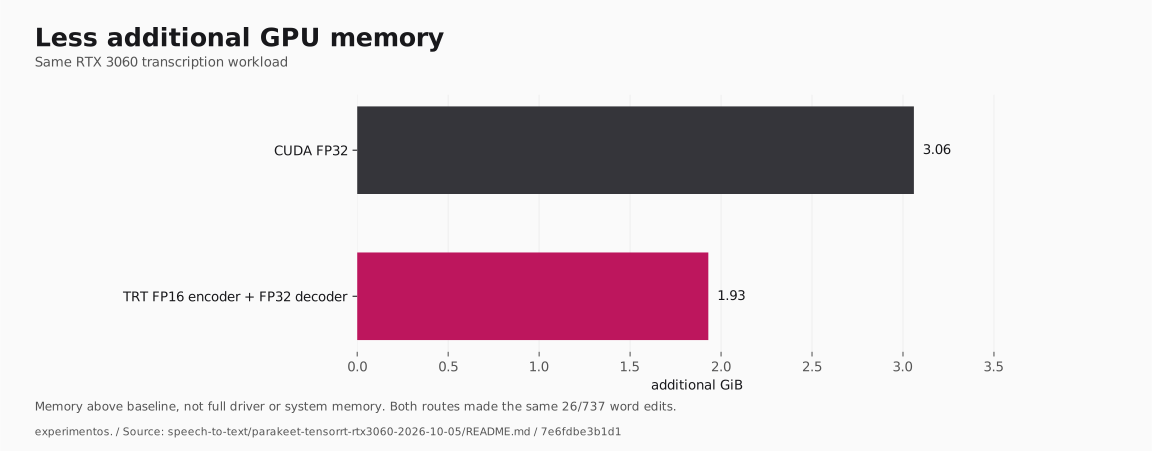
A faster speech encoder with the same 50 transcripts · 5 Oct 2026 · RTX 3060
Less additional GPU memory
Same RTX 3060 transcription workload
- CUDA FP323.06
- TRT FP16 encoder + FP32 decoder1.93
additional GiB
Memory above baseline, not full driver or system memory. Both routes made the same 26/737 word edits.
View data & source
| Configuration | Value |
|---|---|
| CUDA FP32 | 3.06 |
| TRT FP16 encoder + FP32 decoder | 1.93 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
Making MOSS fit: the codec and the chunk budget · 6 Oct 2026 · RTX 3060
The codec shortened each tested native render
RTX 3060 · HQ4 · native-voice cases only
- 45 characters · before35.4
- 45 characters · GPU codec26.4
- 143 characters · before40.8
- 143 characters · GPU codec32.4
- 193 characters · before51.0
- 193 characters · GPU codec37.7
- Three sentences · before53.9
- Three sentences · GPU codec38.0
wall seconds
The female-reference encode changed separately. This chart does not establish cloned-voice parity.
View data & source
| Configuration | Value |
|---|---|
| 45 characters · before | 35.4 |
| 45 characters · GPU codec | 26.4 |
| 143 characters · before | 40.8 |
| 143 characters · GPU codec | 32.4 |
| 193 characters · before | 51.0 |
| 193 characters · GPU codec | 37.7 |
| Three sentences · before | 53.9 |
| Three sentences · GPU codec | 38.0 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
Native AWQ saved idle memory and cost speech time · 8 Oct 2026 · RTX 3060
Idle-memory savings came with slower generation
English held-out 50-word story · two warm repetitions · RTX 3060
- Turbo · original0.446
- Turbo · native AWQ0.564
- English G64 · original0.888
- English G64 · native AWQ1.221
- Multilingual v2 · original1.014
- Multilingual v2 · native AWQ1.344
real-time factor
Lower is faster. These are separate model comparisons, not a multilingual quality leaderboard.
View data & source
| Configuration | Value |
|---|---|
| Turbo · original | 0.446 |
| Turbo · native AWQ | 0.564 |
| English G64 · original | 0.888 |
| English G64 · native AWQ | 1.221 |
| Multilingual v2 · original | 1.014 |
| Multilingual v2 · native AWQ | 1.344 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
What six bits preserved in Chatterbox Turbo · 9 Oct 2026
Decoder error grew as oQ storage shrank
Three English sentences · fixed original tokens and conditioning
- Community affine 6-bit1.308
- oQ61.839
- oQ53.013
- oQ45.130
log-mel difference (dB)
A spectral difference, not a human quality score. Whole-generation token changes are evaluated separately.
View data & source
| Configuration | Value |
|---|---|
| Community affine 6-bit | 1.308 |
| oQ6 | 1.839 |
| oQ5 | 3.013 |
| oQ4 | 5.130 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
The audio was identical. The benchmark numbers changed. · 9 Oct 2026 · Apple M5
Identical audio, new timing conditions
M5 · battery · Low Power Mode off · five warm repeats of one sentence
- Original FP322.861
- Community affine 6-bit1.535
- oQ61.489
- oQ51.445
- oQ41.389
warm median seconds
All 30 comparison WAV hashes match the earlier run. This is not additional prompt coverage.
View data & source
| Configuration | Value |
|---|---|
| Original FP32 | 2.861 |
| Community affine 6-bit | 1.535 |
| oQ6 | 1.489 |
| oQ5 | 1.445 |
| oQ4 | 1.389 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
A faithful decoder can still be the slower pipeline · 10 Oct 2026 · Apple M5
The complete Python adapter was slower
M5 · battery · three sentences · same reported comparison
- Community 6-bit MLX1.359
- CoreML/ONNX adapter4.974
warm median seconds
Not a native Swift or proven ANE result. Controlled-noise decoder diagnostics are a separate cohort.
View data & source
| Configuration | Value |
|---|---|
| Community 6-bit MLX | 1.359 |
| CoreML/ONNX adapter | 4.974 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
The decoder swap passed its word-error gate · 10 Oct 2026 · Apple M5
The ONNX audio stage added generation time
Same MLX T3 tokens · unchanged published ONNX decoder · M5
- Generic · MLX1.111
- Generic · hybrid2.069
- Selected voice · MLX0.954
- Selected voice · hybrid1.799
warm median seconds
No added ASR errors in 40 matched comparisons. This does not establish human quality or Spanish performance.
View data & source
| Configuration | Value |
|---|---|
| Generic · MLX | 1.111 |
| Generic · hybrid | 2.069 |
| Selected voice · MLX | 0.954 |
| Selected voice · hybrid | 1.799 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
A local LatAm conversion failed the content gate · 10 Oct 2026
The local LatAm conversions added content edits
Five Spanish phrases · two seeds · matched local conversion test
- Current multilingual Q80
- Community FP320
- Local LatAm Q89
- Local LatAm FP328
- Q8 · FP16 vocoder trial0
edits / 142 reference words
Recorded content normalization differs from strict WER. Upstream PyTorch was not tested.
View data & source
| Configuration | Value |
|---|---|
| Current multilingual Q8 | 0 |
| Community FP32 | 0 |
| Local LatAm Q8 | 9 |
| Local LatAm FP32 | 8 |
| Q8 · FP16 vocoder trial | 0 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
Q6 saved space; predicted MOS did not settle naturalness · 9 Oct 2026
A real reduction in main checkpoint storage
Main checkpoint only · external tokenizer excluded
- FP322,711.1
- Q8 G64877.8
- Q6 G64718.4
decimal MB
Storage is not runtime memory or uniform compute precision. Unsupported tensors remain FP32.
View data & source
| Configuration | Value |
|---|---|
| FP32 | 2,711.1 |
| Q8 G64 | 877.8 |
| Q6 G64 | 718.4 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
Holding speech tokens fixed made the Q8 advantage clearer · 10 Oct 2026
Q8 stayed closer under the fixed-token control
Three English + three Spanish phrases · two seeds · same FP32 conditioning
- Q8 G640.332
- Q6 G641.001
log-mel RMS difference (dB)
Decoder fidelity is not naturalness. Whole generation can change tokens, duration and omissions.
View data & source
| Configuration | Value |
|---|---|
| Q8 G64 | 0.332 |
| Q6 G64 | 1.001 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
MOSS: the best similarity score did not mean the fewest word errors · 9 Oct 2026
Generator variants changed Spanish word errors
Separate Spanish extension · three phrases · one seed · same conditioning
- BF16 + same LoRA4
- Older Q49
- Older Q525
- Q6/Q8 from 8-bit33
- Q6/Q8 from BF162
- oMLX Q3/Q4/Q610
- oMLX Q4/Q5/Q647
- oMLX Q5/Q69
- Uniform Q64
ASR edits / 65 words
One generation per phrase. Baseline uses split generation/decoding; no comparable end-to-end latency claim.
View data & source
| Configuration | Value |
|---|---|
| BF16 + same LoRA | 4 |
| Older Q4 | 9 |
| Older Q5 | 25 |
| Q6/Q8 from 8-bit | 33 |
| Q6/Q8 from BF16 | 2 |
| oMLX Q3/Q4/Q6 | 10 |
| oMLX Q4/Q5/Q6 | 47 |
| oMLX Q5/Q6 | 9 |
| Uniform Q6 | 4 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
MOSS on a 3090: Q2 failed, AWQ4 stayed closer · 17 Oct 2026
Q2 failed the tiny Spanish quality screen
Three Spanish prompts · two seeds · same cached codes and FP32 decoder
- Original BF161.53
- Sensitivity Q2 · rejected121.85
- Sensitivity Q31.45
- AWQ41.70
- AutoRoundQ32.04
normalized character error (%)
Insertions can push CER above 100%. Different bit budgets prevent isolating the quantizer algorithm.
View data & source
| Configuration | Value |
|---|---|
| Original BF16 | 1.53 |
| Sensitivity Q2 · rejected | 121.85 |
| Sensitivity Q3 | 1.45 |
| AWQ4 | 1.70 |
| AutoRoundQ3 | 2.04 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
Longer Spanish phrases exposed the voice-transfer cost · 13 Oct 2026
The longer Spanish set exposed word errors
Six Spanish utterances · 56 reference words · timbre-only transfer
- Original Supertonic5.36
- Voice transfer · 4 steps10.71
- Voice transfer · 8 steps8.93
- Voice transfer · 12 steps7.14
ASR word error (%)
ASR proxy, not human listening. Six phrases are too few for a general language-quality claim.
View data & source
| Configuration | Value |
|---|---|
| Original Supertonic | 5.36 |
| Voice transfer · 4 steps | 10.71 |
| Voice transfer · 8 steps | 8.93 |
| Voice transfer · 12 steps | 7.14 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
More diffusion steps did not reliably improve the voice match · 13 Oct 2026
More steps added substantial conversion delay
Six matched Spanish utterances · existing conversions
- 4 steps1.263
- 8 steps2.214
- 12 steps3.241
median conversion seconds
Conversion stage only; phone capture, translation, synthesis and network time are excluded.
View data & source
| Configuration | Value |
|---|---|
| 4 steps | 1.263 |
| 8 steps | 2.214 |
| 12 steps | 3.241 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
Supertonic: half the storage did not mean faster CPU speech · 13 Oct 2026
FP16 saved storage without winning CPU latency
Verified graph inventory · same source Supertonic 3
- FP32398.1
- FP16 except duration201.6
- Mixed INT8383.6
decimal MB
Mixed INT8 quantizes the vector estimator only; other components remain FP32.
View data & source
| Configuration | Value |
|---|---|
| FP32 | 398.1 |
| FP16 except duration | 201.6 |
| Mixed INT8 | 383.6 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
Keeping FP32 and moving Supertonic to Triton · 13 Oct 2026
FP32 GPU execution reduced first-audio delay
96 renders · 12 phrases per language · two repeats · paired CPU/GPU
- English · CPU1.154
- English · Triton GPU0.349
- Spanish · CPU1.079
- Spanish · Triton GPU0.341
median seconds to first PCM byte
NVIDIA Triton ONNX backend with CUDA execution. Excludes ASR, phone capture and call network delay.
View data & source
| Configuration | Value |
|---|---|
| English · CPU | 1.154 |
| English · Triton GPU | 0.349 |
| Spanish · CPU | 1.079 |
| Spanish · Triton GPU | 0.341 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
Drama3: BF16 decoded the same codes about three times faster · 16 Oct 2026 · RTX 3090
BF16 was the fastest tested waveform decoder
RTX 3090 · same Spanish codes · 21.5481 s audio · five timed repeats
- FP32390.07
- BF16129.54
- Mixed BF16173.79
- INT8 W8A16 · dequantized180.34
- INT8 W8A8 · custom kernels276.71
median decoder milliseconds
Decoder only, including waveform copy. Autoregressive generation, loading and compilation are excluded.
View data & source
| Configuration | Value |
|---|---|
| FP32 | 390.07 |
| BF16 | 129.54 |
| Mixed BF16 | 173.79 |
| INT8 W8A16 · dequantized | 180.34 |
| INT8 W8A8 · custom kernels | 276.71 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
Drama3: BF16 decoded the same codes about three times faster · 16 Oct 2026 · RTX 3090
The English code replay showed the same ordering
RTX 3090 · same English codes · 15.8824 s audio · five timed repeats
- FP32292.42
- BF1696.88
- Mixed BF16129.68
- INT8 W8A16 · dequantized135.39
- INT8 W8A8 · custom kernels203.29
median decoder milliseconds
One utterance in this language. This is not a complete request, listening test or production deployment.
View data & source
| Configuration | Value |
|---|---|
| FP32 | 292.42 |
| BF16 | 96.88 |
| Mixed BF16 | 129.68 |
| INT8 W8A16 · dequantized | 135.39 |
| INT8 W8A8 · custom kernels | 203.29 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
Training & adaptation
When the retention gate says stop · 30 Sept 2026
Every candidate crossed the retention floor
Public regression set · first evaluation block · no confirmation/transfer reads
- Frozen parent446
- LR 1e-5 · after 8 steps429
- LR 2e-5 · after 8 steps346
- LR 3e-5 · after 8 steps386
- Restored parent446
checks passed / 446 · gate: 440
All three runs rolled back. A restored parent is not an improved trained checkpoint.
View data & source
| Configuration | Value |
|---|---|
| Frozen parent | 446 |
| LR 1e-5 · after 8 steps | 429 |
| LR 2e-5 · after 8 steps | 346 |
| LR 3e-5 · after 8 steps | 386 |
| Restored parent | 446 |
Origin: structured measurements. Revision 6550ead3945b.
- llm-polisher/retention-replay-kd-v1-20260930/evidence/runs/main/report.json
- llm-polisher/retention-replay-kd-v1-20260930/evidence/runs/low/report.json
- llm-polisher/retention-replay-kd-v1-20260930/evidence/runs/high/report.json
Teaching a 4B model to read tmux status · 24 Sept 2026
The adapter learned the teacher’s status labels
202 test examples · Qwen3.5-4B QLoRA classifier
- Base model97
- Tuned model192
teacher-agreement cases / 202
Teacher agreement is not independent ground truth. Tuned macro-F1: 0.8625514403292182.
View data & source
| Configuration | Value |
|---|---|
| Base model | 97 |
| Tuned model | 192 |
Origin: structured measurements. Revision 6550ead3945b.
Teaching a 4B model to read tmux status · 24 Sept 2026
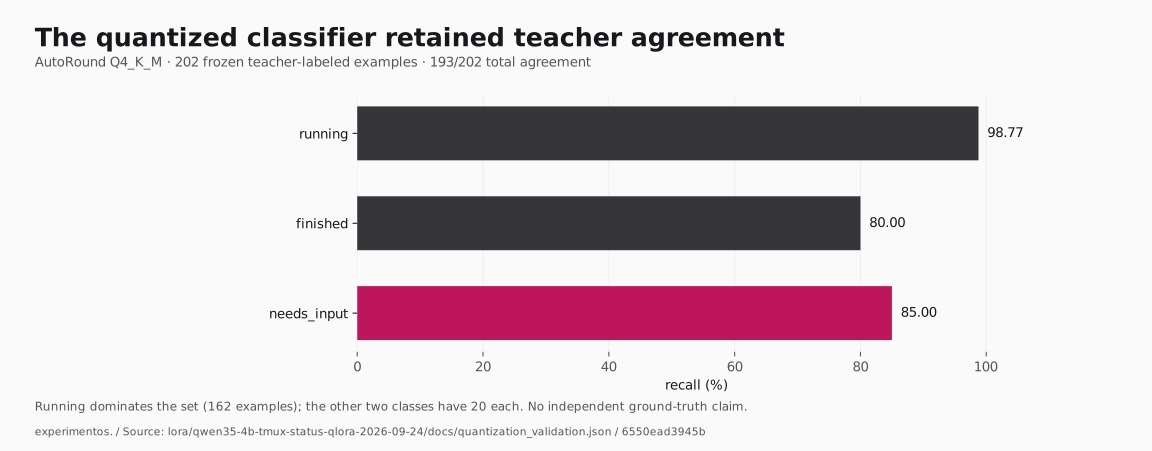
The quantized classifier retained teacher agreement
AutoRound Q4_K_M · 202 frozen teacher-labeled examples · 193/202 total agreement
- running98.77
- finished80.00
- needs_input85.00
recall (%)
Running dominates the set (162 examples); the other two classes have 20 each. No independent ground-truth claim.
View data & source
| Configuration | Value |
|---|---|
| running | 98.77 |
| finished | 80.00 |
| needs_input | 85.00 |
Origin: structured measurements. Revision 6550ead3945b.
Pending results
These experiments have no published result file yet. They are listed, not estimated.
- A benchmark harness that keeps dry runs out of the resultsDevices & tools · field-notes
- When the retention gate says stopTraining & adaptation · rejected
- Eight clears are still not a promotionGame learning · rejected
- The reusable RGBA learning pipelineGame learning · field-notes
- What counts as a successful episode?Game learning · field-notes
- The faster image pipeline that produced nothingImages & video · rejected
- A quantization job goes silentSpeech & codecs · incident
- From a model download to a working local serviceLanguage models · field-notes
- The EXL3 quantization journeyLanguage models · in-progress
- A draft head, a rollback fix, and a midnight incidentLanguage models · incident