FP32, BF16, INT8: separating codec drift from speech
Codec precision can change storage, waveform detail and reference encoding in different ways. The A/B/C experiment separated those effects using pure speech and clone cases, rather than letting transcription parity stand in for every kind of fidelity.
Key finding
Pure TTS legs shared token sequences, and normalized transcription differences were zero across the tested codec legs.
Edited finding from the pinned experiment record. The report and figure metadata preserve the original workload and limits.
The boundary
The voice-clone comparison used different reference codes. The reference INT8 loader materialized BF16 runtime weights.
Data
Reviewed aggregate results with explicit units, sources and qualification limits. Different cohorts remain separate.
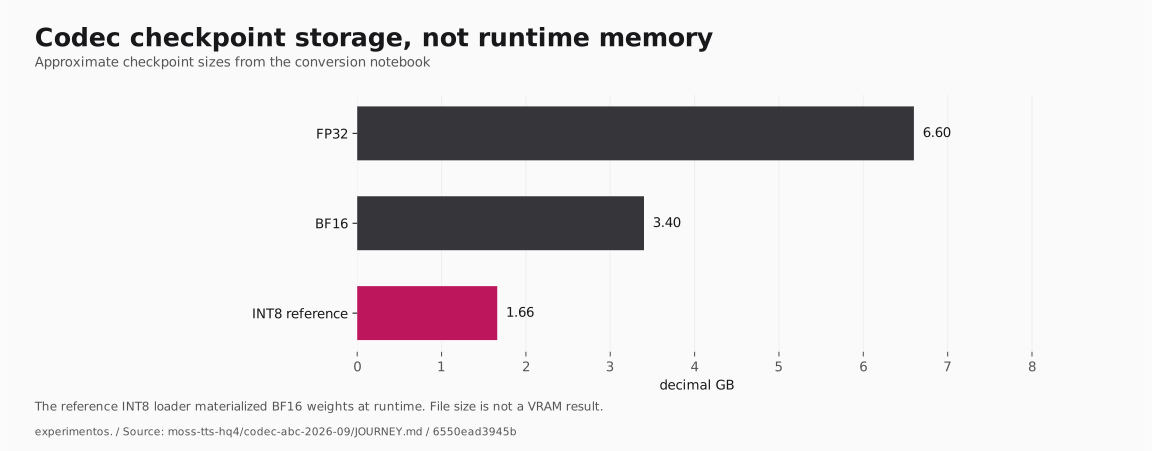
Codec checkpoint storage, not runtime memory
Approximate checkpoint sizes from the conversion notebook
- FP326.60
- BF163.40
- INT8 reference1.66
decimal GB
The reference INT8 loader materialized BF16 weights at runtime. File size is not a VRAM result.
View data & source
| Configuration | Value |
|---|---|
| FP32 | 6.60 |
| BF16 | 3.40 |
| INT8 reference | 1.66 |
Origin: reported conversion sizes. Revision 6550ead3945b.
Write-ups
Report moss-tts-hq4/codec-abc-2026-09/JOURNEY.md
The question
Codec precision can change storage, waveform detail and reference encoding in different ways. The A/B/C experiment separated those effects using pure speech and clone cases, rather than letting transcription parity stand in for every kind of fidelity.
From the original notebook
Background
After the HQ4 fast build (INT4 LLM backbone + FP32 codec), the codec was the biggest remaining chunk: 1.77B params, 6.6 GB FP32. Two reductions were tested against the FP32 reference on identical generations (seed 1234, same sampling):
- BF16:
weights/MOSS-Audio-Tokenizer-BF16(3.4 GB, 32 codebooks kept FP32) - INT8:
weights/MOSS-Audio-Tokenizer-INT8(1.66 GB, symmetric per-channel RTN over all 554 Linears + 66 weight-norm Conv1ds = 99.9% of params, codebooks FP32, biases/norms BF16). No calibration (RTN needs none).
Test GPUs were blocked (EXL3 server on all 3x3090); user authorized stopping it. The proxy (qwen36_variant_proxy, pid 4128370) was SIGSTOP-frozen during tests to prevent backend relaunch, then SIGCONT-resumed (self-heals on next request — its normal rotation behavior).
Journey
- BF16 forward crashed:
Input type (float) and bias type (bfloat16). Root cause: the modeling file hard-casts the quantizer core to FP32 (.float()everywhere — exact nearest-neighbor by design), but the BF16 checkpoint has BF16 in/out/output projections. No reduced-precision codec could EVER run without either FP32 quantizer convs or modeling casts. - Fix: 9-site
_match_proj_dtypepatch in the vendoredmodeling_moss_audio_tokenizer.py(conv input → weight dtype; encoder-entry cast for the FP32 waveform). Applied identically to both codec dirs. Proven no-op for FP32: fp32 output bit-identical before/after. - Pipeline proven bit-deterministic (two fp32 runs, separate processes → identical bytes). So pure-TTS legs share token sequences exactly; measured diffs are 100% codec decode drift. Clean science.
- clone_en confounded: each leg encodes the voice reference with its own codec → different ref codes → different takes (lengths differ). A fair clone comparison needs shared ref codes (harness work, deferred).
- INT8: converter (
tools/convert_codec_int8.py, worst weight err 8.9e-3)- reference loader (
tools/codec_int8_loader.py, dequantizes to BF16 compute) --codec-int8harness flag. INT8 adds ~40-60% more mean drift than BF16 (same order of magnitude). RTF unchanged. NOTE: the reference loader materializes BF16 on GPU, so runtime VRAM == BF16 leg; the 4x win is disk (+ load time). A real INT8 kernel (bnb/marlin-class) is the follow-up for runtime VRAM.
- reference loader (
- Deliveries: 12 WAVs to Hermes Telegram (batch 1: msgs 11806-11814, batch 2: 11824-11828; 11816-11823 were accidental script re-sends).
Numbers (benchmarks/codec_ab, codec_abc.json)
Pure-TTS legs, same tokens (max/mean abs sample diff):
- short: bf16/fp32 0.133/1.24e-3, int8/fp32 0.214/1.69e-3, int8/bf16 0.142/1.45e-3
- medium: bf16/fp32 0.092/5.05e-4, int8/fp32 0.109/7.39e-4, int8/bf16 0.068/5.08e-4
- long_es: bf16/fp32 0.034/5.52e-4, int8/fp32 0.040/8.06e-4, int8/bf16 0.024/7.25e-4
Maxima are isolated spikes; means ~5e-4-1.7e-3. The 5e-3 max-diff gate FAILs for both — unrealistic bar for a 1.7B BF16 decoder; ears are the arbiter.
WhisperX verdict + INT8 adoption
WhisperX (large-v3-turbo, float16, wav2vec2 alignment, per-case language) transcribed all 12 WAVs. Normalized WER int8-vs-fp32 = 0.000 on all 4 cases (0/16, 0/39, 0/66, 0/13 words — even the uncontrolled clone take speaks identical words). bf16-vs-fp32 also 0.000. The only vs-prompt deviation is long_es 0.031 (2/65), shared identically by all three legs → codec-independent (TTS/ASR artifact, not a quant effect).
Decision: INT8 is content-perfect → adopted as default. infer_hybrid_3060.py
now auto-detects INT8 dirs (manifest marker, placeholder config donor) and
defaults --codec to weights/MOSS-Audio-Tokenizer-INT8. Default-path output
verified bit-identical to the validated short_int8.wav. Bench/test tools keep
explicit FP32 defaults (reference role).
Open
- Blind-listening verdict (user) — WhisperX says perfect, ears confirm.
- Fair clone A/B with shared ref codes (optional harness work).
- INT8 runtime kernels for real VRAM win (optional).
- Full-spec HQ4 rebuild + manifest (parked per user).
Keep exploring
Original experiment record. Workstation paths have been generalized. Detailed measurements below retain their original workload and validation boundaries.
Supporting notebooks
More in Speech & codecs
MOSS on a 3090: Q2 failed, AWQ4 stayed closer
Every profile began with the pinned BF16 generator. The comparison reused fixed reference codes and an FP32 decoder for the main quality measurements, keeping codec changes separate from generator quantization.
AWQ4 stayed close to the BF16 reference on WavLM and character errors; the sensitivity Q2 candidate was rejected.
Drama3: BF16 decoded the same codes about three times faster
The experiment replayed saved Spanish and English codes representing 21.5481 and 15.8824 seconds of audio. It compared FP32, BF16, mixed BF16 and two INT8 decoder variants on one RTX 3090.
BF16 reduced median decoder time from 390.07 to 129.54 ms in Spanish and from 292.42 to 96.88 ms in English.
Keeping FP32 and moving Supertonic to Triton
Rather than reduce the CPU graph precision again, this follow-up used NVIDIA Triton’s ONNX backend with CUDA execution and the unchanged FP32 graphs. The paired comparison retained both speed and acoustic checks.
The paired GPU test cut median first-audio time to about 0.35 seconds while preserving the measured ASR results.