An unfinished gauntlet cannot name a winner
This campaign compared Qwen UD-Q4_K_XL with MTP2 against Bonsai through coding harnesses. It stopped at the 70 GiB free-space guard, retaining the incomplete evidence rather than risking the workstation.
Key finding
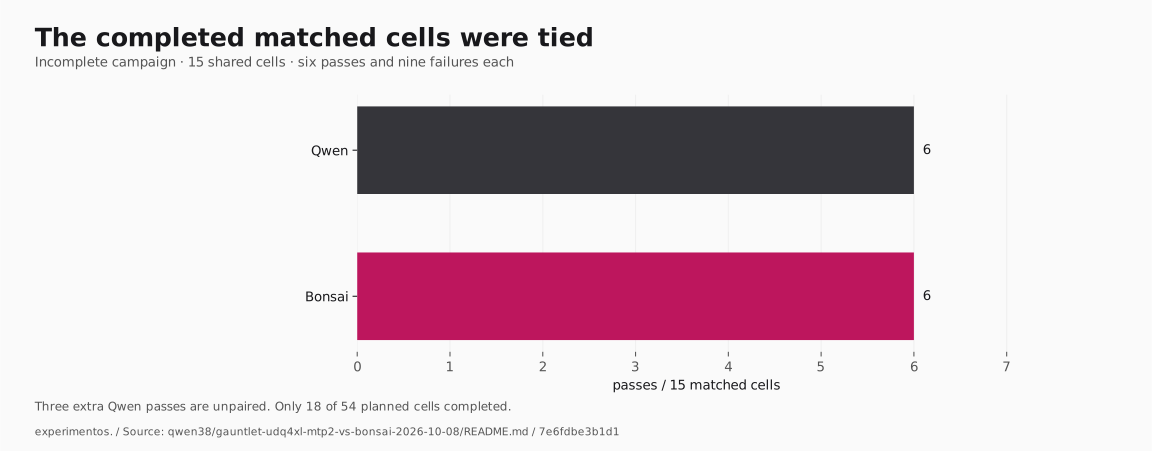
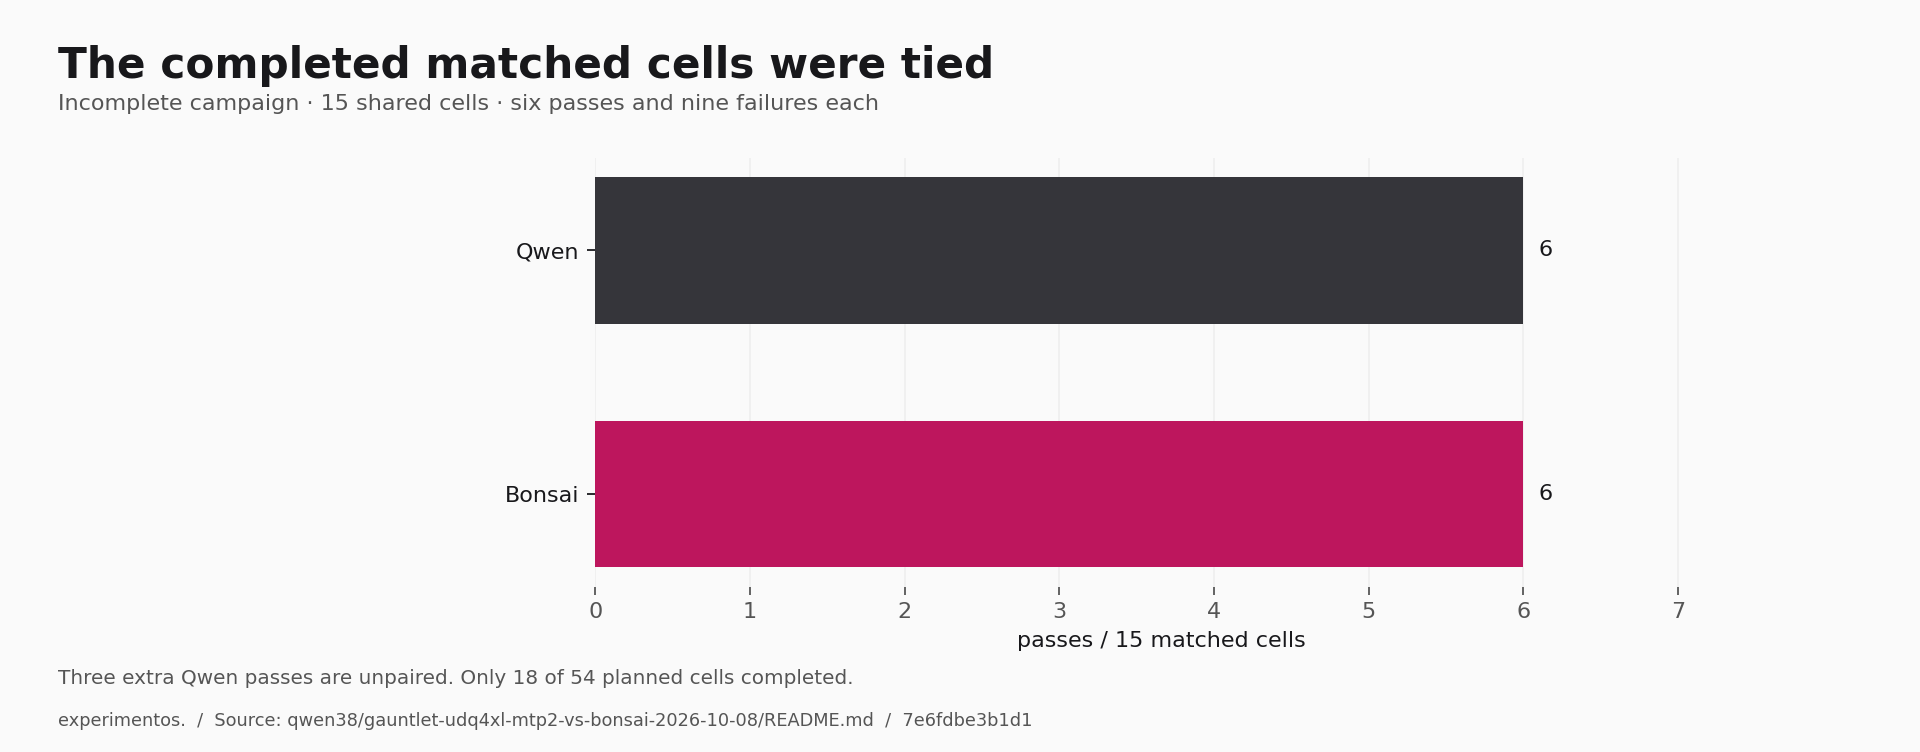
The 15 matched cells tied: six passes and nine failures for each model.
Edited finding from the pinned experiment record. The report and figure metadata preserve the original workload and limits.
The boundary
Only 18 of 54 planned cells ran before the disk guard stopped the campaign. Runtime, sampling and concurrency also differed.
Data
Reviewed aggregate results with explicit units, sources and qualification limits. Different cohorts remain separate.
The completed matched cells were tied
Incomplete campaign · 15 shared cells · six passes and nine failures each
- Qwen6
- Bonsai6
passes / 15 matched cells
Three extra Qwen passes are unpaired. Only 18 of 54 planned cells completed.
View data & source
| Configuration | Value |
|---|---|
| Qwen | 6 |
| Bonsai | 6 |
Origin: reviewed report table. Revision 7e6fdbe3b1d1.
Write-ups
Report qwen38/gauntlet-udq4xl-mtp2-vs-bonsai-2026-10-08/README.md
The comparison that actually finished
This campaign compared Qwen UD-Q4_K_XL with MTP2 against Bonsai through coding harnesses. It stopped at the 70 GiB free-space guard, retaining the incomplete evidence rather than risking the workstation.
Qwen finished 18 cells with nine passes. Bonsai finished 15 with six passes. The three extra Qwen passes were unpaired, so comparing 9/18 with 6/15 would tell the wrong story.
Matched evidence
On the 15 cells available for both, each model passed six and failed nine. Qwen made 564 API requests versus 823 and used 525,627 output tokens versus 768,296. Recorded API duration was 16,789.1 versus 19,805 seconds; effective output rates were 31.31 versus 38.79 tokens/s. Fewer tokens and requests can outweigh a lower decode rate on a task.
These are observed system outcomes under different runtime and sampling conditions. They do not isolate model weights, MTP or a single harness as the cause.
What remains
Resume only after restoring the storage budget, preserve the matched-cell protocol, and report the missing cells explicitly. There is no broad accuracy winner in this partial campaign.
Evidence and publication boundary
This is an edited account of the recorded experiment. The linked archive is private; the methods, aggregate findings and limits are included above. Reference recordings, raw conversations, authentication material and workstation configuration are excluded.
More in Language models
A context setting is not a context test
A server can accept a large context configuration without demonstrating useful work at that length. I separated configured capacity, an actual request, and a successful result before making another speed claim.
The largest verified successful coding prompt was 49,124 tokens; larger configured windows remained unproven.
Finding a local model for the inbox
Inbox work needs accurate structured answers and reasonable response times. The benchmark ran the same 50 tasks across local model, runtime and hardware configurations, with thinking on and off, to make that tradeoff visible.
Bonsai-2-27B PQ2_0 with MTP passed 48/50 tasks with thinking on, at a 15.8-second median on an RTX 3060.
Balancing GPU experts when the model will not fit
The quant was larger than the three GPUs could hold on their own. The experiment tested explicit GPU expert splits with CPU offload and measured the decode effect under the same large-context workload.
An explicit 12/12/12 GPU expert split plus 12 CPU blocks measured 31.1 tokens per second.